

Teaching AI with Quantum Data
We’ve teamed up with NVIDIA and Pfizer to expand the frontier of computational chemistry, combining AI and quantum computing in a canonical instance of GenQAI
AI + quantum computing: Quantinuum, NVIDIA, and Pfizer have combined transformer-based generative AI with quantum computing to automatically generate high-quality quantum chemistry circuits more efficiently than traditional optimization methods.
Practical pharma impact: The approach was used to prepare molecular ground states and validated on Quantinuum’s Helios hardware, demonstrating a path toward larger-scale computational chemistry and drug discovery.
Long-term vision: The team aims to build quantum foundation models that learn from increasingly complex quantum data, eventually enabling AI to design circuits for molecules too large for classical simulation.
Quantum computing has long promised a future that expands what we can do with compute — for example, in molecular simulation, materials discovery, or pharmaceuticals development. But between that promise and practical utility sits a stubborn bottleneck: quantum state preparation.
To run any algorithm on a quantum computer, you must first put the qubits in the right starting state. Think of it like setting up a Rube Goldberg machine- except in this case, you’re not sure exactly which initial setup will give you the results you want. This is what makes quantum state preparation so important: your choice of initial state dictates the accuracy and cost of the rest of the calculation.
We teamed up with NVIDIA and Pfizer to tackle this problem, with an eye towards developing meaningful industrial workflows. The result is a new generative quantum AI framework, called ADAPT-GQE, which we consider to be a canonical instance of GenQAI. ADAPT-GQE uses quantum data to train transformer models that ultimately synthesize quantum chemistry circuits faster, with better outcomes, in a sort of ‘virtuous cycle’.
Ultimately, this means we have developed a new interface between quantum computing and AI. By treating quantum circuit generation as a language modelling problem, we now have a system that can generate high-quality ground-state preparation circuits - with comparable or improved state preparation accuracy.
The Magic – and Difficulty – of Computational Chemistry
The goal of computational chemistry is to learn about chemical properties without performing expensive, time-consuming, and sometimes dangerous “wet-lab” experiments.
In principle, you can replace the majority of your physical experiments with computer simulations, saving billions of dollars and years of time.
In reality, computational chemistry is very tricky. To accurately simulate a chemical inside of a computer, you have to build it from the ground up. You start with a collection of atoms (in the case of imipramine, you have 19 Carbon atoms, 24 Hydrogen atoms, and 2 Nitrogen atoms). Then, like Nature’s ‘lego’, you assemble those atoms into a molecule: you set bond lengths, strengths, angles, interactions, and so on.
This is not straightforward: a single molecule can exist in many forms; with different angles, rotations, etc. We will call these different forms ‘conformations’.
Then, to actually estimate chemical properties, or to explore chemical reaction pathways, you have to reproduce the detailed physics that goes on at the atomic level: take your chosen conformation then figure out how each orbital is occupied, how the electrons are interacting with each other or the atomic nuclei, how is the addition of heat or a catalyst going to affect things.... it gets complicated, quickly.
Despite all this, computational chemistry is a powerhouse in pharmaceutical development. Right now, pharmaceutical companies save money and time by simulating as much as they can on computers, avoiding time consuming and expensive laboratory experiments. However, even with ~50 years of development, the existing classical methods have very real limitations.
This is where quantum computing comes in: this new computational paradigm can elide those limitations because it has many of the “hard parts” (like superposition or entanglement) natively encoded. Used correctly, quantum computing promises to break old barriers, further improving margins for pharma companies across the globe while contributing to meaningful, impactful, discoveries.
A Virtuous Cycle: Using Quantum Data to Train AI, Which Then Designs Better Quantum Circuits
While quantum computational chemistry is one of the strongest candidates for near-term quantum advantage, current hardware is still in the earlier stages of development. With limited qubits and error rates, algorithm designers need to make every gate count, keep circuits shallow, and be able to tolerate some level of noise.
This is where generative AI enters the picture.
Instead of hand-designing chemistry circuits and laboriously experimenting to see how well they run, there is another idea: what if we trained an AI to solve the problems that quantum computational chemistry faces?
Using this approach, not only can we save time and resources; but we can shorten the timeline to realize practical results. With better state prep and other circuits, applications that were once considered far in the future come into view.
Our first attempt at this is called ADAPT-GQE. The central idea behind ADAPT-GQE is deceptively simple: instead of laboriously searching for good quantum circuits from scratch, train a transformer model to generate them directly.
Importantly, the framework is model-agnostic, which we showed by deploying it on complementary transformer architectures - Nemotron (a pretrained LLM) and Gemma (trained from scratch).
From Iterative Optimization to Generative Models
The initial goal here is to find the ‘ground state’ of the molecule imipramine (this is the electronic state with the smallest amount of energy stored inside it). To do this, you have to find the right ‘state preparation circuit’, as described above.
Until now, a leading method for finding the ground state with quantum computers was the ‘Variational Quantum Eigensolver (VQE)’, a hybrid quantum-classical approach. The VQE process starts with a ‘guess’ circuit for a particular conformation of the molecule. The quantum computer runs the circuit to measure the associated energy of the molecule. This result is fed back into a classical optimizer that then tweaks the circuit parameters, hopefully resulting in one with a lower molecular energy. This loop repeats until a minimum energy is found.
Unfortunately, VQE has a few severe limitations that make it infeasible for widespread use. The recently proposed ADAPT-VQE was a crucial step forward meant to address some of the issues with “plain” VQE. In ADAPT-VQE, instead of starting with a guess for the initial circuit, the process builds a circuit in steps by selecting operators from a pool(typically using gradient information) and optimizing. This approach can be more effective, but unfortunately still grows too large too quickly.
This is where the joint team jumped in.
Combining the best of all worlds, the team’s new framework, ADAPT-GQE, combines AI with the ADAPT-VQE to create something entirely new – and something that, so far, is a scalable, hardware-validated pathway toward automated quantum circuit synthesis.
First, transformers (in this case, Nemotron and Gemma) are trained via supervised fine-tuning on ADAPT-VQE data. In this way, the old method isn’t thrown away but is instead treated as a high-quality data-producing “oracle”.
Then, once the transformer has been initially trained, it defines a distribution over circuits, each one with some probability of corresponding to the ground state. This distribution can be used in a fine-tuning loop, for example, reinforcement learning. In reinforcement learning, the framework takes a circuit from that distribution, runs it, and measures the energy. It feeds the results back into the transformer, which adjusts its distribution. Over time, the model learns to prioritize circuits that prepare increasingly accurate ground states.
Crucially, reinforcement learning allows the system to surpass its original training data instead of merely imitating it. The model is no longer acting as a compressed lookup table for ADAPT-VQE. It begins exploring novel circuit configurations that may outperform the teacher algorithm itself. This is one of the most important conceptual shifts in the project.
In this case, instead of running all the initial circuits on Quantinuum’s Helios, the reinforcement learning circuits were run using NVIDIA accelerated computing and the CUDA-Q platform, simulating a quantum processor.
Finally, once the transformers are optimized via reinforcement learning, the best resulting circuits are validated for accuracy and feasibility, by running them using InQuanto and Nexus on Quantinuum’s newest hardware, Helios. With InQuanto v5.2, users can now interface directly with both the Helios quantum computer and the Selene quantum emulator through Nexus.
This powerful combination of InQuanto and Nexus enabled the execution one of the largest AI-generated quantum chemistry circuits to date on a quantum computer; helping to turn the promise of quantum computing into a practical tool for pharmaceutical development.
Teaching a Transformer
Looking farther in the future, the researchers envision something much larger than a single molecular benchmark.
For bigger and more complex molecules, ADAPT-VQE won’t work in the first place as the initial training “oracle”. In addition, the molecular energy calculations used in the reinforcement learning grow too large for classical systems simulating quantum computers, so the quantum processor becomes essential.
Luckily, this is not a problem. The ultimate goal of the ADAPT-GQE framework is to develop a “curriculum” for the transformers. This means instead of re-training them for every new molecule, you instead keep what you already learned, and expand your knowledge from there.
By initially teaching it on molecules that are smaller, and that can be fully simulated, you ensure it learns on good data that can be double checked using known methods. From there, you can carefully build up the complexity to see how the transformer learns. Eventually, you hope to train it on molecules that can’t be simulated classically, using purely quantum data, all the while getting closer to the complexity levels you’re chasing.
This penultimate result is called a ‘foundation model’, which is a massive AI neural network trained on vast, broad datasets that can be adapted to a wide variety of downstream tasks. In this case, the team is building the very ‘foundations’ of a model that can solve the ‘electronic structure problem’, which is the core computational challenge lying at the heart of quantum (and classical) computational chemistry.
A New Interface Between AI and Quantum Computing
What makes this work particularly interesting is that it treats quantum circuit generation as a language modeling problem: circuits become sequences, transformers learn distributions over those sequences, and reinforcement learning optimizes them against physical reward functions.
The result is an AI system capable of proposing quantum circuits that were never explicitly programmed by humans.
That does not mean generative AI is replacing physics or chemistry. Instead, it is becoming a new interface layer for navigating unimaginably large search spaces that traditional optimization methods struggle to explore efficiently.
For quantum chemistry, that could become transformative.
If successful, frameworks like ADAPT-GQE may eventually allow researchers to synthesize useful quantum circuits for molecular systems too large for classical computation, accelerating everything from materials discovery to pharmaceutical design.
The broader implication is difficult to ignore: foundation models may eventually extend beyond language, images, and code — and into the fabric of physical reality itself.
About Quantinuum
Quantinuum, the world’s largest integrated quantum company, pioneers powerful quantum computers and advanced software solutions. Quantinuum’s technology drives breakthroughs in materials discovery, cybersecurity, and next-gen quantum AI. With over 500 employees, including 370+ scientists and engineers, Quantinuum leads the quantum computing revolution across continents.
- QUOPS is a new, architecture-agnostic benchmark designed to measure quantum performance across physical- and logical-qubit systems, using two metrics: Q (computation size) and Ω (operations per second).
- It addresses the limits of traditional metrics like qubit count, gate fidelity, and gate speed by measuring what a quantum system can actually execute successfully—including the effects of error correction, decoding, mitigation, compilation, and other system-level factors.
- QUOPS aims to create a common language for the industry, helping vendors demonstrate progress, enabling buyers and governments to make more objective procurement decisions, and giving researchers a standardized way to track progress toward utility-scale, fault-tolerant quantum computing.
Quantum computing is entering a new era. As systems move from Noisy Intermediate-Scale Quantum (NISQ) toward Fault-Tolerant Application-Scale Quantum (FASQ), traditional metrics like qubit count, gate fidelity, and gate speed are no longer enough to describe what a machine can actually deliver.
Introducing QUOPS
Developed by Sandia National Laboratories, with input from Quantinuum and NVIDIA, QUOPS—the Quantum Universal Operations Performance System—is a common, architecture-agnostic benchmark for measuring quantum performance across both physical- and logical-qubit systems on the path toward quantum utility.
QUOPS can be applied to different architectures, codes, modalities, and levels of fault tolerance. QUOPS runs the same randomized workloads across different computational shapes, measures whether each workload succeeds, identifies the boundary of a system’s capability region, and reports two summary metrics:
- Q: the largest benchmark circuit size that passes the success threshold inside a utility-motivated region. Size is defined as 2*(width)*(depth).
- Ω: the effective operations per second at that point.
The result is a direct measure of how much computation a system can perform and how quickly it can do so. Together, these measurements provide a two-dimensional view of capability while reducing system performance to a common currency: quantum operations.
Why Quantum Computing Needs a New Metric
Component-level metrics remain essential for engineering. Qubit count, two-qubit fidelity, and gate speed can reveal control errors, crosstalk, leakage, connectivity constraints, and other system limitations. But they do not necessarily predict system-level performance.
Fault tolerance makes this gap even larger. Physical operations become logical computation with the addition of logical encoding, syndrome measurement, decoding, logical gate construction, magic-state production, routing, and control. Ultimately, this means that fault tolerance expands the relevant currencies of computation. Code distance, logical fidelity, magic-state throughput, decoding, connectivity, and space-time volume can matter far more for performance than raw qubit count or individual gate speeds.
This creates a growing challenge for buyers, governments, and researchers. As organizations move from experimentation toward larger-scale and potentially on-premise quantum systems, they need to know a simple thing:
What computation can a machine actually execute successfully?
QUOPS addresses that question by measuring the integrated system rather than inferring performance from individual components.
This is particularly important as the field considers workloads requiring roughly 10⁹–10¹² operations on thousands of qubits. Today's measured capabilities are still orders of magnitude smaller; QUOPS turns that gap into a measurable quantity.
QUOPS for Procurement
QUOPS can also provide a practical layer for quantum procurement and planning.
HPC centers need to understand when quantum computing will become useful for real workloads. Customers may have a goal of procuring a system that can, for example, run a trillion error-free operations. Today, answering these questions can require complex resource estimates that depend on hardware modality, QEC code, magic-state factories, decoding, compilation, and other architectural choices.
In both cases, QUOPS provides a simpler system-level reference point: Q describes the size of computation a machine can execute, while Ω describes its effective throughput. Furthermore, because QUOPS is architecture-neutral and includes anti-gaming provisions, it can also help buyers compare competing systems without relying solely on vendor-selected metrics or announcements.
How Quantinuum stacks up
While QUOPS is a new benchmark, it has already been measured on several vendors’ hardware. This marks an important step for our industry: we can now compare vendors directly, assessing their capabilities in a way that flattens the differences introduced by modality and architecture choices.
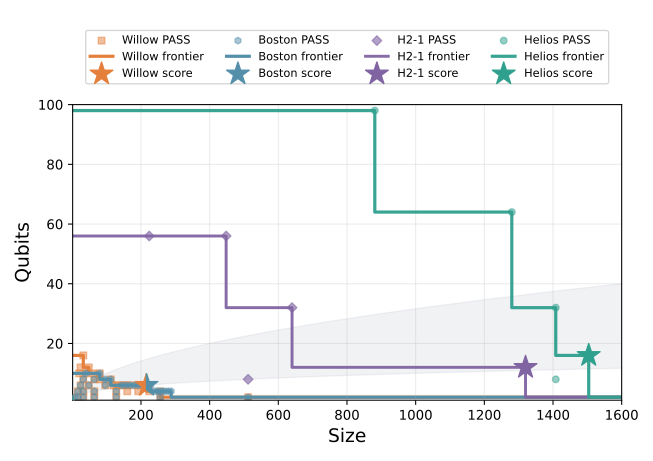
Figure 1. The QUOPS capability region and score for state-of-the-art processors from Quantinuum, Google, and IBM (adapted from Figure 2 of the scientific publication co-authored by Quantinuum, Sandia National Laboratories, and NVIDIA). QUOPS specifies a random circuit construction that can be built for a specified width (number of qubits) and size (number of quantum gates). A set of circuits is run at several width and size points and the average fidelity of those circuits are measured and compared to a predefined threshold. Each labeled point above represents experimental data from QUOPS circuits that passed the threshold with high confidence. The lines are filled capability limits of each machine between the points. The stars indicate the QUOPS score (Q), which is the experimental data point that passes the threshold with maximum size inside the shaded cone of width2 ≤ size ≤ width3.
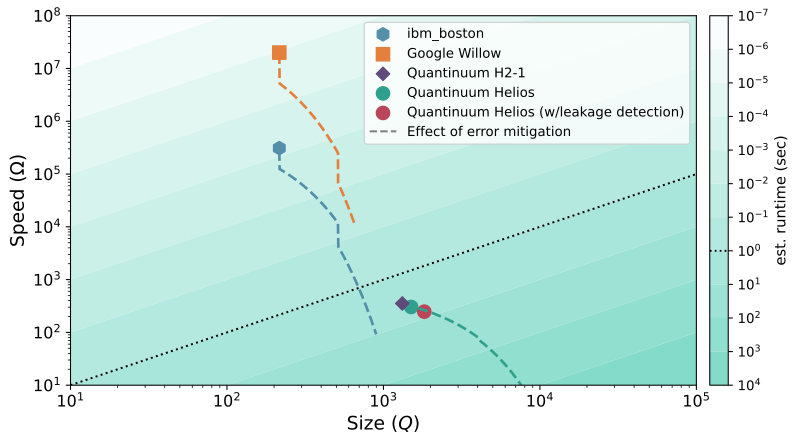
Figure 2. The QUOPS score (Q) vs rate (Ω) for state-of-the-art processors from Quantinuum, Google, and IBM (adapted from Figure 2 of the QUOPS scientific publication co-authored by Quantinuum, Sandia National Laboratories, and NVIDIA). Each point is the maximum QUOPS circuit size that passes the threshold within the specified cone and rate that it was run. The dashed lines indicate the extrapolated effect of error mitigation, which attenuates the rate by including the shot overhead needed for general-purpose error mitigation. The gradient lines show the estimated runtime of a circuit at a given score and rate.
Figures 1 and 2 show how QUOPS quantifies the capability tradeoffs between different systems. Willow and Boston are superconducting systems with very fast gate speeds but limited connectivity, while Helios is a trapped-ion QCCD system with effective all-to-all connectivity but much slower gates. Willow and Boston have smaller capability regions and QUOPS scores but higher QUOPS rates; while Helios reaches larger capability regions and QUOPS scores but lower QUOPS rates. All three systems have the ability to trade speed for larger circuits with error mitigation. This is commonly assumed in the community but is nicely quantified with the QUOPS rate, which accounts for the corresponding sampling overheads of general error mitigation techniques (as shown by the dashed lines in Figure 2).
Building a New Benchmarking Ecosystem
QUOPS will not replace every quantum benchmark. The field will continue to need application-specific suites, component-level measurements, hybrid-HPC benchmarks, and independent verification.
QUOPS instead serves as a common system-level yardstick that can make roadmaps more comparable, procurement more objective, and progress easier to track.
We are calling on vendors to report QUOPS metrics (Q, Ω) and capability regions alongside existing metrics, buyers and agencies to consider QUOPS thresholds in RFPs, and researchers to contribute fault-tolerant architectures and resource estimates.
As quantum computers become fault tolerant, success will no longer be defined simply by how many qubits a machine contains or how low its error rates are.
It will be defined by the computation the machine can deliver.
QUOPS is a step toward measuring that capability—and toward giving the quantum industry a benchmark built for the era ahead.
- A new experiment tests what makes a quantum computer genuinely quantum by using a simple game that demonstrates a provable advantage from quantum superposition, without relying on entanglement or assumptions about classical computational difficulty.
- The test was demonstrated on Quantinuum’s System Model H2, where researchers ran thousands of circuits and observed results close to theoretical quantum predictions. The approach also offers an efficiently verifiable way to test for non-classical behavior.
- The work provides a new way to think about quantum-computing verification: rather than focusing only on metrics like qubit count, we can ask whether a machine demonstrates capabilities that fundamentally distinguish quantum systems from classical ones. This validates that the computer is working as intended.
Building a quantum computer is one thing. Showing that it is genuinely using quantum mechanics is another.
A new experiment, just published in Nature Communications, takes a fresh approach to that question. Instead of relying on entanglement or the complex calculations often used to benchmark quantum computers, researchers designed a simple game (initially published in Physical Review Letters) that tests something more fundamental: quantum superposition.
Using superposition, the team constructed a game where quantum mechanics provides a provable advantage over classical approaches. Once the game was set, the team ran it on real hardware. The results showed a clear performance gap between the best possible classical system and our System Model H2 – a gap that only grew as the test became more difficult.
A game that classical computers can’t win
The game is played by a single player with access to a computer. The player receives a quantum state representing a set of numbers—for example, {0, 1, 5, 7}. Their goal is to return a number that belongs to the complement of that set: {2, 3, 4, 6}.
That sounds simple. But as the size of the sets grows, something remarkable happens.
A classical strategy needs to test many numbers to succeed. A quantum strategy, however, succeeds in one step. The authors show that the quantum strategy has a score that grows exponentially faster.
Importantly, this isn't based on an assumption that this problem is difficult for classical computers. The separation is mathematically proven. In other words, the researchers can show that the quantum advantage exists without relying on unproven assumptions from complexity theory.
Using our System Model H2, the experimenters were able to confirm the theoretically derived separation between the quantum and the classical strategy (up to the largest sizes they could fit on the quantum processor) with high confidence – showing that the violation remained close to exponential.
Testing quantum mechanics without entanglement
Many famous experiments testing quantum behavior rely on entanglement and non-locality, where multiple parties share parts of a quantum system.
This experiment is different.
There is only one player, who has access to the entire quantum system. The advantage comes from superposition—the ability of a quantum system to exist in a combination of states until it is measured.
That distinction matters because it provides another way to ask whether a quantum computer is actually behaving quantum mechanically.
The researchers turned their game into an experimental test and ran thousands of different circuits on Quantinuum's System Model H2. The scores they observed were close to the theoretical predictions for a quantum strategy.
Why verification matters
One of the challenges with existing quantum-computing demonstrations is figuring out whether the machine really produced the result it was supposed to produce.
For example, random circuit sampling can be extremely difficult to verify classically as systems become larger. That creates a tension: you want to demonstrate that a quantum computer is doing something a classical computer cannot easily reproduce, but you also need a practical way to check the result.
The complement-sampling game offers a different approach. The violation of classical performance can be efficiently verified with a classical computer.
That makes the test potentially more scalable: you don't need to reproduce the entire quantum computation on a classical computer just to determine whether the machine demonstrated non-classical behavior.
So, what makes a quantum computer “quantum”?
The deeper message of the experiment is that demonstrating a quantum computer isn't simply about having qubits.
A convincing demonstration should show that the machine is exploiting properties that genuinely distinguish quantum computation from classical computation. Here, the researchers focus on one of those defining properties—superposition—and construct a game where quantum mechanics provides a provable advantage.
This first experimental demonstration of complement sampling doesn't close every possible loophole, which is common for this sort of experiment – closing the major experimental loopholes in Bell-inequality tests took decades—a body of work that ultimately contributed to the 2022 Nobel Prize in Physics. The researchers explicitly note that the implementation relies on assumptions about how the input state is prepared, so the experimental results should be interpreted with some caution.
Still, the work provides a new way to probe the boundary between classical and quantum computation.
And that may be the most interesting part: rather than asking only “How many qubits does the machine have?”, we can ask a more meaningful question—
“What can this machine do that only a quantum system can?”
That is ultimately what it takes for a quantum computer to actually be quantum.
- Helix is Quantinuum’s QEC architecture designed for scalability, leveraging reconfigurable connectivity to reduce the physical-qubit and time overhead required for fault-tolerant computation.
- The architecture has been experimentally validated on Helios, demonstrating logical memory, logical computation, and logical entanglement across different QEC codes—all outperforming corresponding physical-level results without post-selection.
- Helix provides a foundation for Apollo, combining efficient logical gates, multiple QEC encodings, and a path to universal fault-tolerant computation. The results on commercial hardware validate Quantinuum’s roadmap toward scalable, fault-tolerant quantum computing.
The NISQ1 era is coming to an end. At Quantinuum, we’ve already demonstrated numerous QEC codes, all the primitives needed for logical computation, steadily declining logical error rates, and full computations at the logical level.
But there’s still a way to go. One of the defining challenges over the coming years will be putting it all together into a usable – and scalable – fault tolerant architecture. Today, we are excited to announce that we have experimentally validated one of our own leading candidates for such an architecture, the Helix code.
With this demonstration, we have put all the pieces together: logical memory, logical computation, a heterogenous code architecture that optimizes for magic vs gates, all with super efficient operations and record-breaking2 fidelity.
The Challenge of Fault Tolerance
The delicate nature of qubits gives them their strength – they can be entangled, placed into superpositions, and even teleported. However, this comes at a cost: on the hardware level, quantum bits (qubits) will always be noisier than classical bits.
Enter quantum error correction (QEC). QEC moves us past prohibitive physical noise to fidelities that really matter; where industrial workflows and scientific discovery live. Our field has been hard at work to realize - and optimize - QEC, and we are finally starting to reap the fruits of that labor.
However, for the most part, this work has taken shape only a few pieces at a time: a demonstration of fault tolerant gates here or memory there, sometimes even a full fault-tolerant algorithm, but rarely do we see demonstrations at the architectural scale needed to build our next generation of machines.
The difficulty is that encoding and performing fault-tolerant computation costs considerable space (qubit number) and time (circuit complexity), which QEC researchers summarize with a “spacetime volume”.
Introducing Helix: A QEC Architecture for Apollo
The Helix code was custom-designed to usher in the next generation of fault tolerance.
Using our reconfigurable qubits, we designed Helix to minimize its spacetime volume by employing more exotic entanglement schemes compared to traditional codes (imagine cat’s cradle compared to a simple, 2D net). This entanglement complexity is impossible with processors that don’t have reconfigurable connectivity.
Ultimately, this translates to a code that requires fewer physical qubits per logical qubit, while also giving you fast and simple computing.

To build the Helix code, we use the [[4,2,2]] code as the physical building block for each qubit in the [[10,2,3]] code. In other words, rather than constructing the torus directly from physical qubits, we construct it from logical qubits encoded in [[4,2,2]] code blocks. In the image on the left, the black dots represent these logical qubits, and the dashed lines represent the connections between them. Importantly, the dashed lines connect logical qubits within the same [[4,2,2]] code block.
This concatenation would be extremely difficult to implement without the reconfigurable connectivity enabled by our mobile qubits.
In general, gates between logical qubits can be quite difficult because logical qubits are composed of physical qubits that are entangled together in some specific way. Sometimes, a single physical qubit may even be shared between multiple logical qubits, as is the case with codes that offer lots of logical qubits per physical qubit. Performing gates across these complex structures can be tricky, and can take a lot of individual operations on physical qubit pairs to accomplish.
There are two major exceptions. The first, called a transversal gate, is where the logical operation maps directly onto the physical one: you just perform a regular 2-qubit gate between each physical qubit in each logical qubit.
The second is simpler still: gates can be accomplished by simple software-level qubit relabeling (eg simply renaming qubit A to qubit B), combined with easy, single qubit gates. This type of automorphism, or permutation-based gate, is particularly elegant.
The Helix code makes heavy use of transversal and automorphism gates, making it considerably faster and easier to compute with than a lot of other options. Ultimately, this translates to a significant reduction in both space (qubit) and time (circuit complexity) overheads: less space is needed for block encoding and ancilla; and time is drastically reduced when simple software relabeling or transversal gates are performed in the place of expensive protocols like lattice surgery.
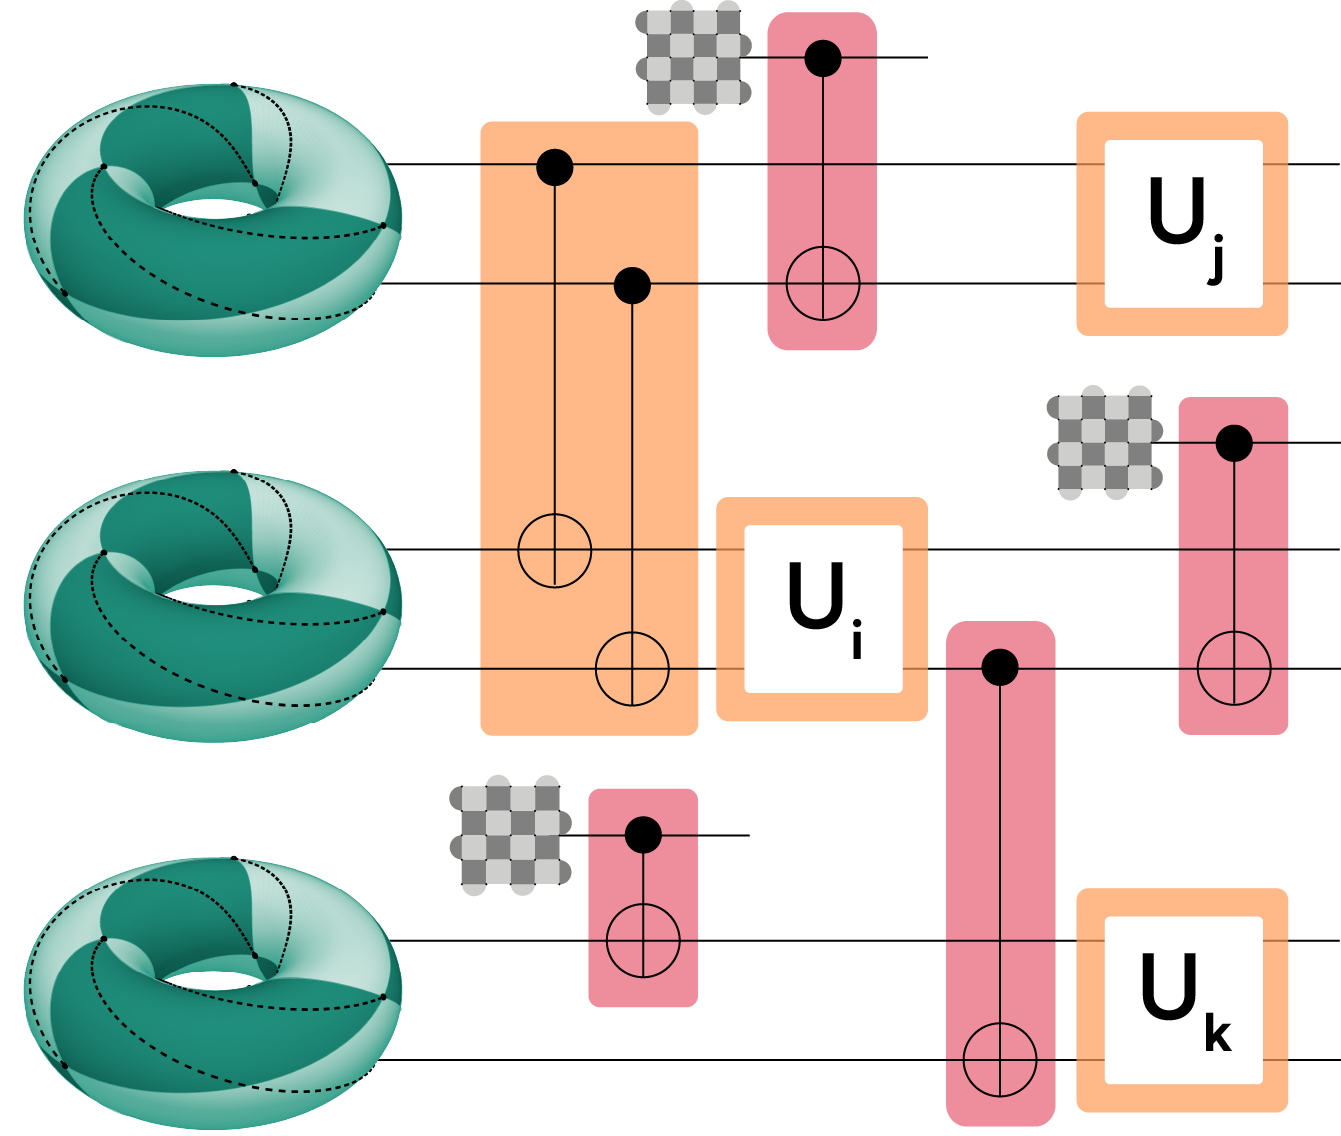
Demonstrating the Building Blocks of a Fault-Tolerant System
Experiment 1: Logical Memory
The team started by showing that the Helix code can successfully preserve encoded quantum information for extended periods of time.
To show this, the team started with their logical qubits in a given state. Then, they performed 20 rounds of syndrome extraction, paying special attention to leakage (a dominant source of error on Helios). To remove leakage, the team leveraged Helios’ new leakage repump capacity, as well as circuit-level leakage reduction units.
Result: per qubit, per round, they achieved an error rate of 4.6 x 10⁻⁵, with no post selection.
This amounts to a block logical error per round of 9.3 x 10⁻⁵, with no post selection. With a small amount of post selection (0.5%), the block logical error per round was reduced to 1.9 x 10⁻⁵.
Why This Matters
Quantum memory is one of the most fundamental building blocks of a fault-tolerant quantum computer. A useful quantum processor must be able to preserve quantum information long enough to perform the computation, error correction, and communication required by larger algorithms.
These results prove that encoded quantum information can be preserved with a lower error rate than the underlying physical operations – all without needing post selection.
Experiment 2: Logical Computation
A central feature of the Helix logical architecture is that encoding multiple logical qubits does not require correspondingly expensive logical computation. By construction, this code has a variety of logical gates all implementable with only physical single-qubit gates and qubit relabeling. These ‘SWAP-transversal’, or ‘automorphism’, gates provide the ability to do some logical circuits essentially for free, as permutations are realized by simple ion-transport and software level relabeling.
The team experimentally tested the code’s computational abilities by benchmarking the complete logical Clifford group (i.e., all gates except for T gates) while interleaving up to 27 rounds of active adaptive syndrome extraction.
Result: 2.8 x 10⁻⁴ logical error rate per Clifford gate, a significant improvement (4.28x) over Helios’ physical 2-qubit Clifford error rate, again achieved without post selection.
This impressive result is partially enabled by the team’s clever adaptive syndrome extraction (ASE) technique. Their ASE technique reduces the number of physical gates required per logical gate by about 33%. This pruning also shortens the physical run time, reducing the ‘wall clock duration’ by about 23%. Both gates and idling contribute significantly to errors, so these reductions translate to a lower logical error rate.
Why This Matters
This experiment proves the Helix code’s ability to compute, all while showing significant improvement over the physical level with no post selection. In addition, this marks the first demonstration of randomized benchmarking on a code encoding more than one logical qubit, an important milestone for our community.
Experiment 3: Universality via Logical Entanglement Across Different Codes
Clifford gates alone are insufficient for universal fault-tolerant computation; our QEC architecture must also provide access to non-Clifford resource states (often called “magic”). While the Helix code has many desirable features in terms of Clifford gates, it’s sub-optimal for preparing magic states. Rather than forcing the Helix code to work in this regime, we developed our architecture to employ two codes; one for Clifford gates and memory, and one for magic state preparation. Using different codes each optimized for their own tasks, called a heterogenous architecture, makes the entire assembly considerably more efficient and cost effective.
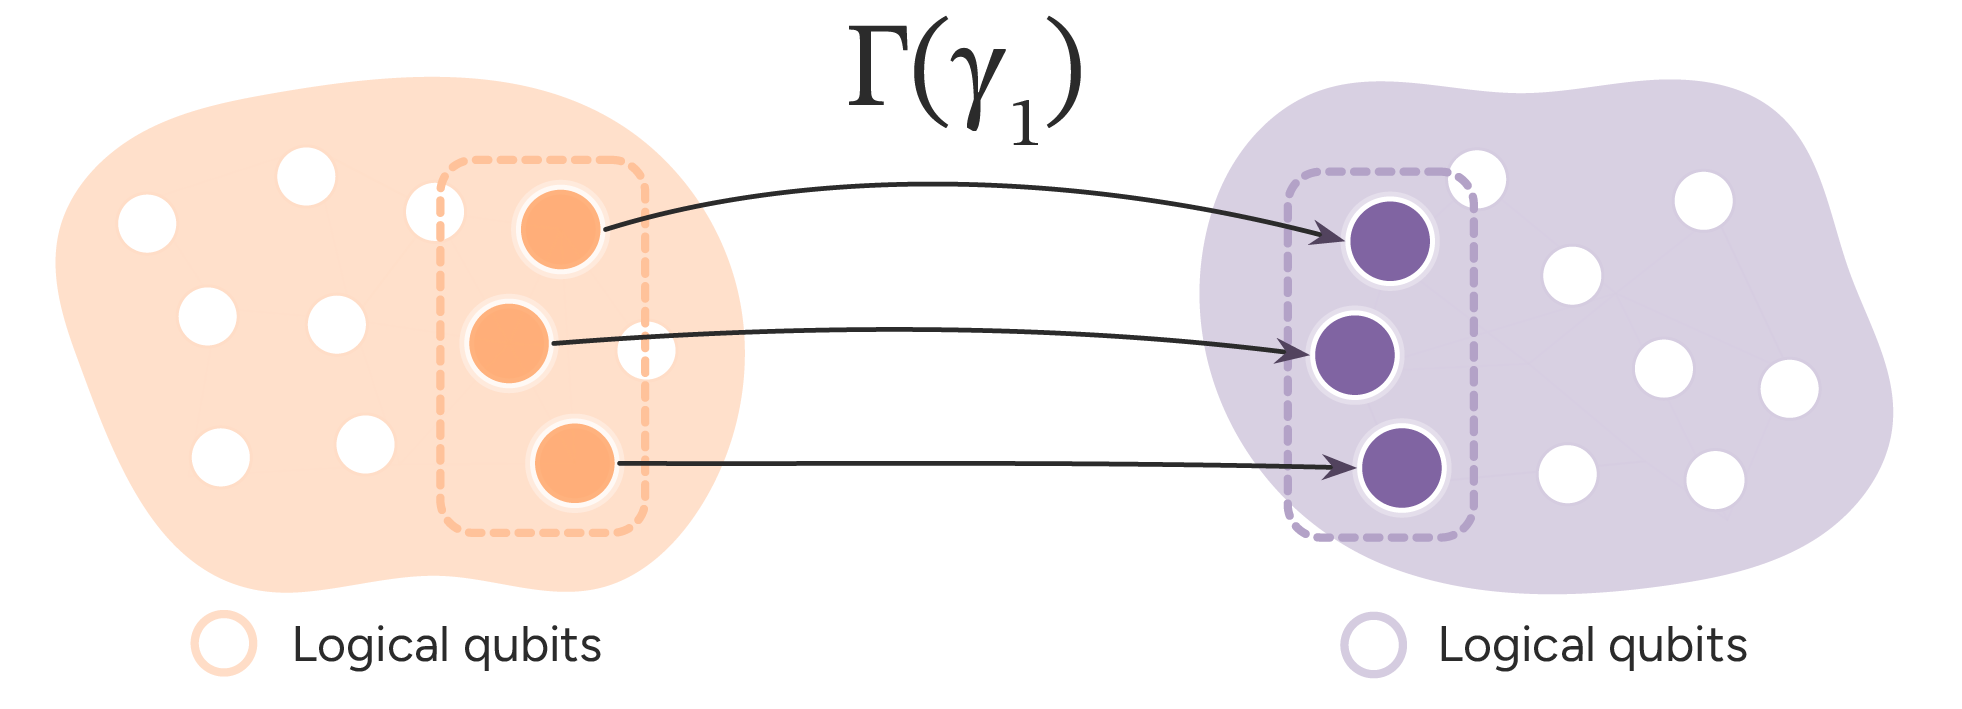
The trick that makes it all possible is something called chain-mapping, that allows the QPU to smoothly switch between underlying encoding schemes. To test this, the team used a rotated surface code for magic state generation, which would then be injected into the computational (Helix) code to generate non-Clifford gates (enabling fault tolerant universal computation).
Rather than performing magic state injection directly, the team wanted to benchmark the interface (the chain-map). To do this, they used their chain-mapped gates to prepare a three logical qubit GHZ state that spans the two different codes. The resulting GHZ state contained 1 logical qubit from the surface code and two from the Helix code, making for a truly heterogeneous structure.
Result: The logical GHZ state had a fidelity lower bound of 99.925%, and an upper bound of 99.975%. The lower bound exceeded the physical baseline, making all three experiments better than their physical counterparts.
Why This Matters
This experiment demonstrates one of our key architectural advantages: using our reconfigurable connectivity to employ multiple QEC encodings in a single fault tolerant architecture, improving our efficiency and reducing qubit costs.
Accelerating the Path to Apollo
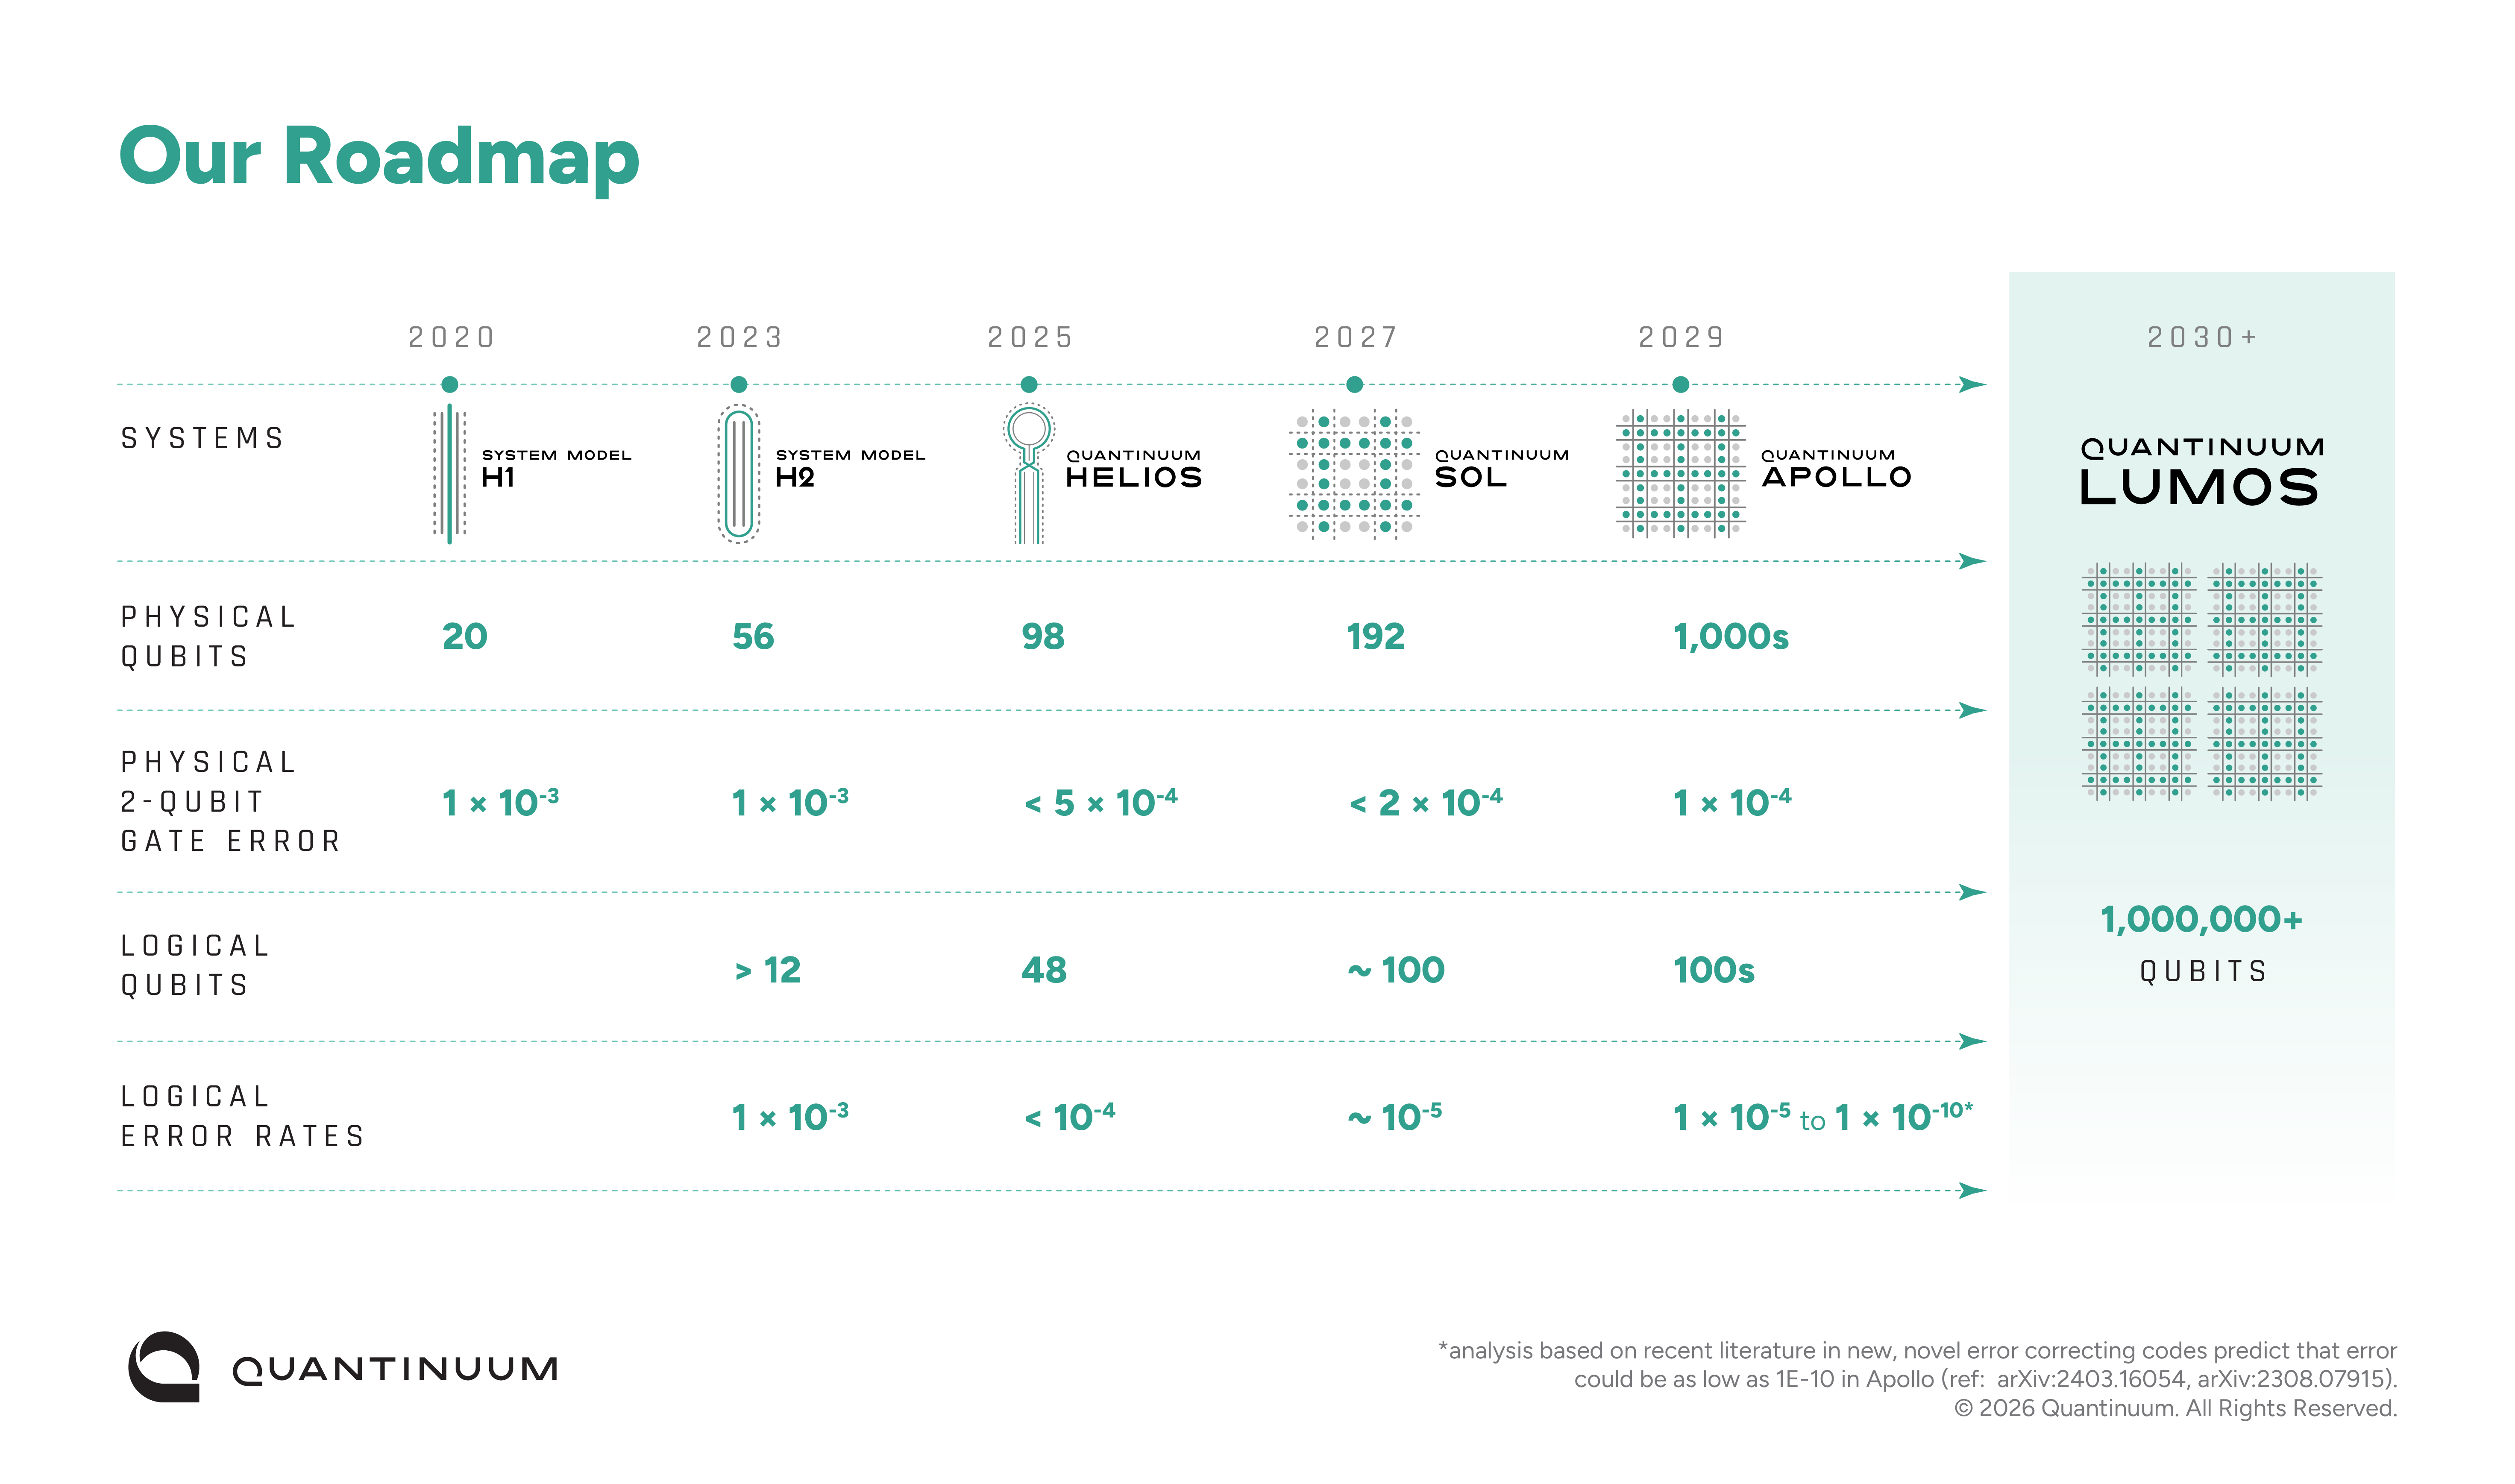
The quantum computing industry has proposed many approaches to error correction. This paper marks one of the first experimentally validated plans for a QEC architecture. With the low logical error rates (all improving on the physical baseline), the practical logical operations (which drastically reduce qubit costs and compute time), and real commercial hardware performance, this result helps to prove that we will deliver on our roadmap.
A crucial element of this demonstration is that these results were obtained on our commercial hardware. This is not a result from a testbed, or a result from hardware that has limited functionality. This is a result from the same computer as our customers use for their own research.
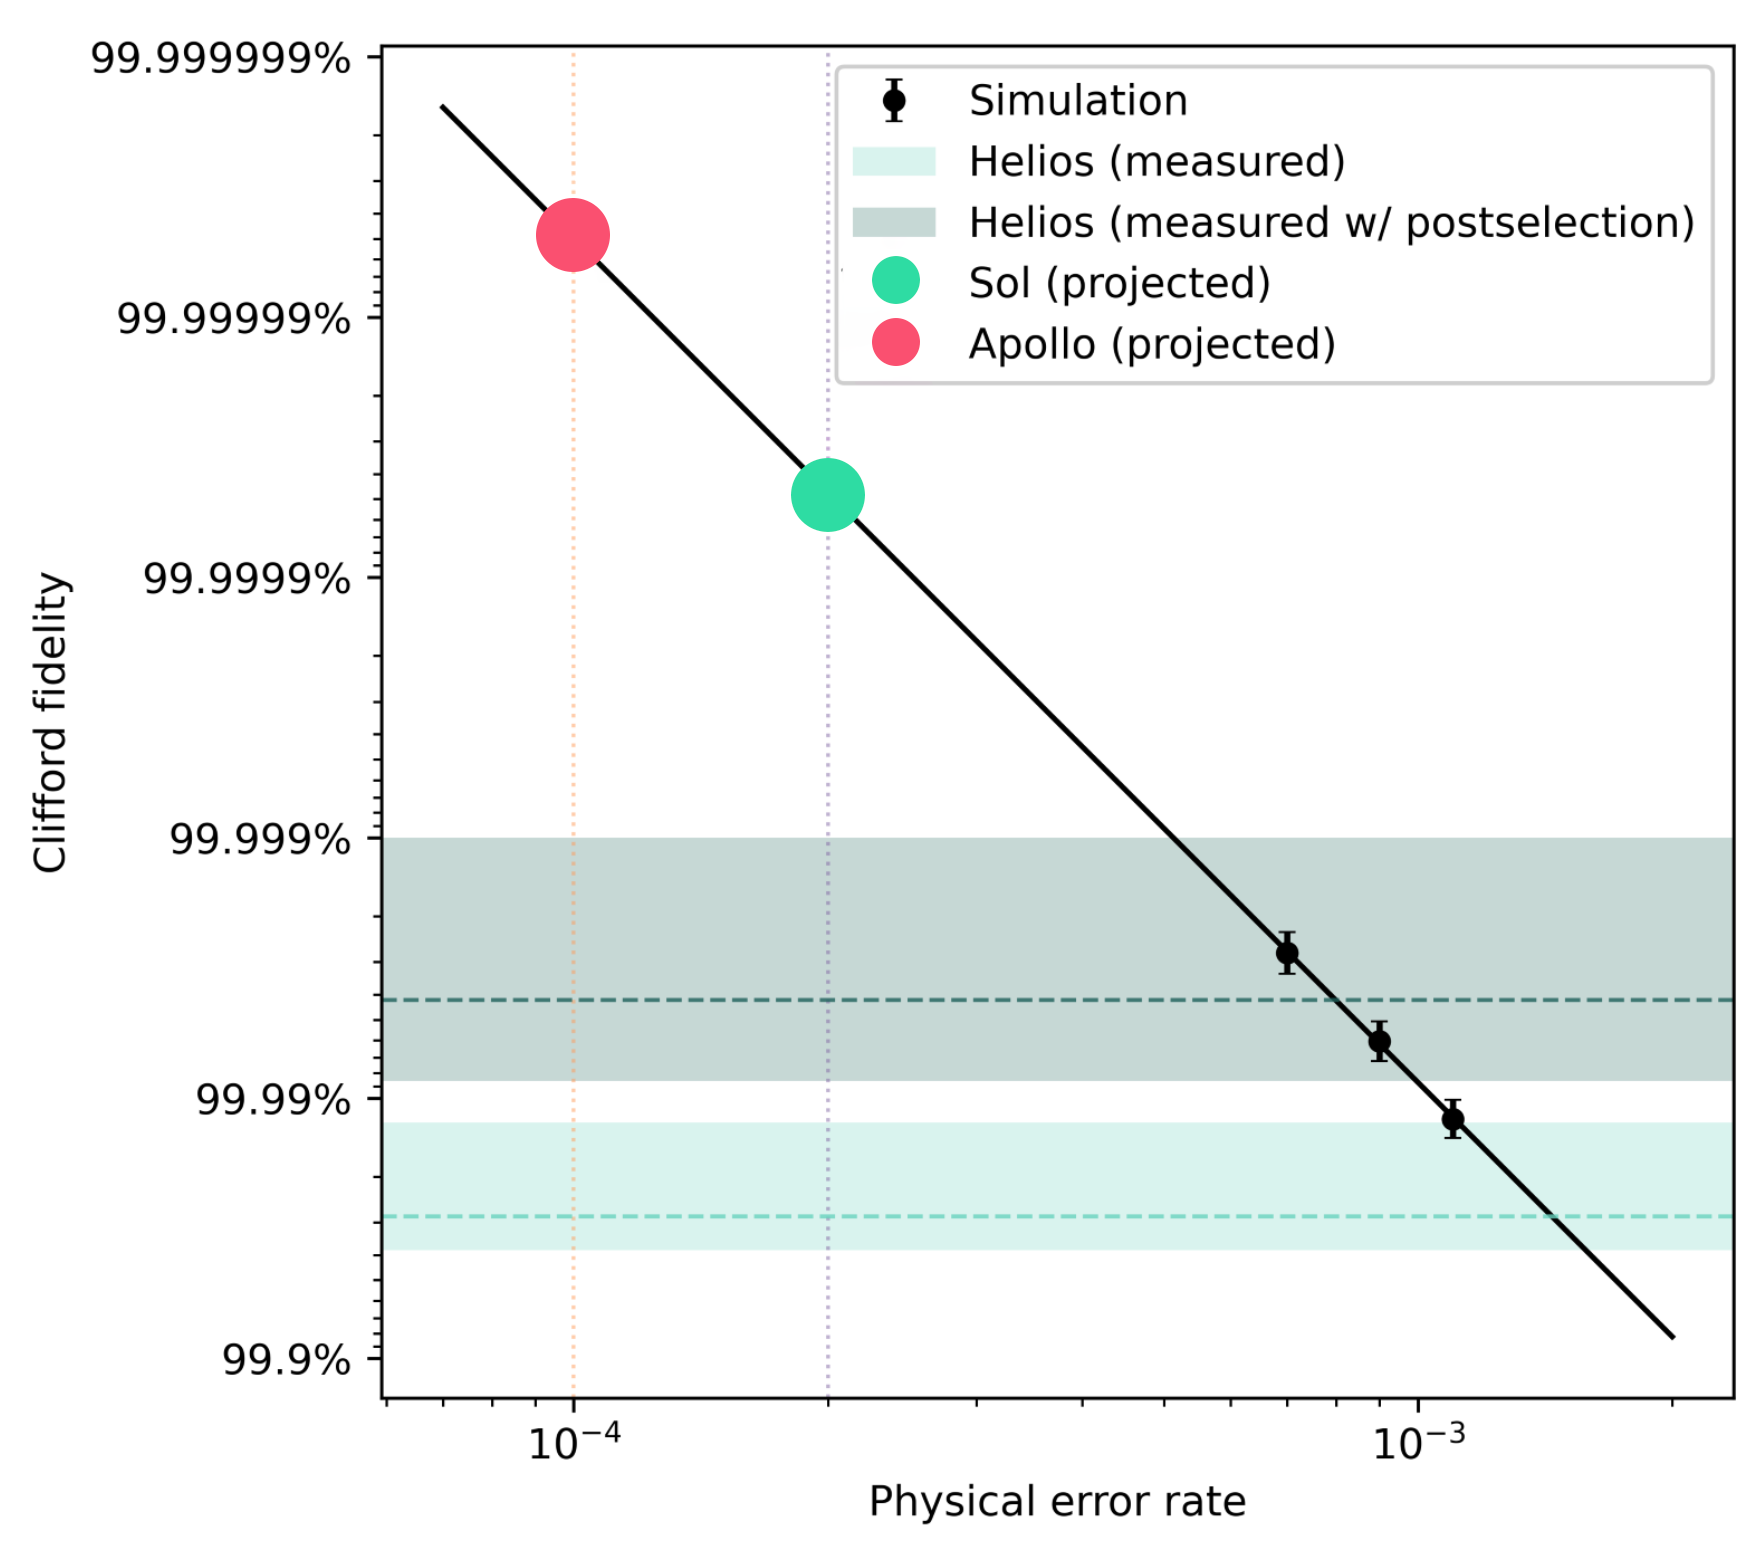
Furthermore, simulations indicate that the improvements in physical fidelity we expect from moving from Helios to Apollo will bring logical error rates in line with our roadmap targets. Because logical error rates depend strongly on physical error rates, Apollo’s expected improvements at the physical level should translate directly into lower logical error rates. Importantly, we expect to achieve these gains without increasing the code distance or using additional physical qubits per logical qubit.
Building a fault-tolerant quantum computer requires solving multiple engineering challenges. In this result we have proven our path to a scalable QEC architecture, showing not just one-off results on test stand hardware, but a harmonious whole consisting of:
✓ A candidate architectural code
✓ Logical memory
✓ Logical computation
✓ A path to magic
✓ Multiple encodings in one architecture
✓ Commercial hardware compatibility
By validating our fault-tolerant architecture on real commercial hardware, Quantinuum has taken a significant step toward Apollo - and toward quantum computers capable of solving meaningful problems at scale.
1 Noisy Intermediate-Scale Quantum
2 Based on a study of existing literature