

Quantinuum H-Series quantum computer accelerates through 3 more performance records for quantum volume
217, 218, and 219
In the last 6 months, Quantinuum H-Series hardware has demonstrated explosive performance improvement. Quantinuum’s System Model H1-1, Powered by Honeywell, has demonstrated going from 214 = 16,384 quantum volume (QV) announced in February 2023 to now 219 = 524,288, with all the details and data released on our GitHub repository for full transparency. At a quantum volume of 524,288, H1-1 is 1000x higher than the next best reported quantum volume.


We set a big goal back in 2020 when we launched our first quantum computer, HØ. HØ was launched with six qubits and a quantum volume of 26 = 64, and at that time we made the bold and audacious commitment to increasing the quantum volume of our commercial machines 10x per year for 5 years, equating to a quantum volume of 8,388,608 or 223 by the end of 2025. In an industry that is often accused of being over-hyped, a commitment like this was easy to forget. But we did not forget. Diligently, our scientists and engineers continued to achieve world-record after world-record in a tireless and determined pursuit to systematically improve the overall performance of our quantum computers. As seen in Figure 1, from 2020 to early 2023, we have steadily been increasing the quantum volume to demonstrate that increased qubit count while reducing errors directly translates to more computational power. Just within 2023 we’ve had multiple announcements of quantum volume improvements. In February we announced that H1-1 had leapfrogged 214 and achieved a quantum volume of 215. In May 2023, we launched H2-1 with 32 qubits at a quantum volume of 216. Now we are thrilled to announce the sequential improvements of 217, 218, and 219, all on H1-1.
Importantly, none of these results were “hero results”, meaning there are no special calibrations made just to try to make the system look better. Our quantum volume data is taken on our commercial systems interwoven with customer jobs. What we experience is what our customers experience. Instead of improving at 10x per year as we committed back in 2020, the pace of improvement over the past 6 months has been 30x, accelerating at least one year from our 5-year commitment. While these demonstrations were made using H1-1, the similarities in the designs of H1-2 (now upgraded with 20 qubits) and H2-1, our recently released second generation system, make it straightforward to share the improvements from one machine to another and achieve the same results.
In this young and rapidly evolving industry, there are and will be disagreements about which benchmarks are best to use. Quantum volume, developed by IBM, is undeniably rigorous. Quantum volume can be measured on any gate-based machine. Quantum volume has been peer-reviewed and has well defined assumptions and processes for making the measurements. Improvements in QV require consistent reductions in errors, making it likely that no matter the application, QV improvements translate to better performance. In fact, to realize the exponential increase in power that quantum computers promise, it is required to continue to reduce these error rates. The average two-qubit gate error with these three new QV demonstrations was 0.13%, the best in the industry. We measure many benchmarks, but it is for these reasons that we have adopted quantum volume as our primary system-wide benchmark to report our performance.
Putting aside the argument of which benchmark is better, year-over-year improvements in a rigorous benchmark do not happen accidentally. It can only happen because the dedicated, talented scientists and engineers that work on H-Series hardware have a deep understanding of its error model and a deep understanding of how to reduce the errors to make overall performance improvements. Equally important the talented scientists and engineers have mastery of their domain expertise and can dream-up and then implement the improvements. These validated error models become the bedrock of future systems’ design, instilling confidence that those systems will have well understood error models, and the performance of those systems can also be systematically improved and ultimate performance goals achieved. Taking nothing away from those talented scientists and engineers, but having perfect, identical qubits and employing our quantum charge coupled device (QCCD) architecture does give us an advantage that all the other architectures and other modalities do not have.
What should potential users of H-Series quantum computers take away from this write-up (and what do current users already know)?
- Quantinuum is committed to systematically improving the core performance of our quantum computing hardware. The better the fundamental performance, the lower the overhead will be when doing error mitigation, error detection, and ultimately error correction. This provides confidence in our ability to deliver fault-tolerant compute capabilities.
- Progress on your research, use-case, or application can be accelerated by getting access to H-series technology because our quantum computers can do circuits that other technologies cannot. “It actually works!” exclaim excited first-time users.
- Quantinuum intends to continue to be the quantum computing company that quietly over-delivers, even on big goals.
1. https://github.com/CQCL/quantinuum-hardware-quantum-volume
About Quantinuum
Quantinuum, the world’s largest integrated quantum company, pioneers powerful quantum computers and advanced software solutions. Quantinuum’s technology drives breakthroughs in materials discovery, cybersecurity, and next-gen quantum AI. With over 500 employees, including 370+ scientists and engineers, Quantinuum leads the quantum computing revolution across continents.
For enterprise and public sector executives evaluating quantum computing investment
Quantum computing is now a strategic priority for many organizations. It's on track to help solve some of the world's biggest challenges, from drug discovery, to materials science, to optimization problems – all at a scale classical computers simply can't reach. For executives responsible for R&D, technology strategy, or innovation investment, the question is no longer whether quantum computing matters. It's how to approach it wisely.
That's a harder question than it sounds. The quantum computing market is crowded, technical, and moving fast, and most of the guidance available is written for physicists, not for the executives who actually have to make the investment decision. Vendor claims are difficult to compare, pilot programs are easy to get wrong, and the gap between "quantum is exciting" and "quantum is worth investing in this year" isn't always well explained.
Our new guide, A Strategic Guide to Selecting the Right Quantum Computing Solution, is built to close that gap.
What's Inside
The guide is designed to give business and technology leaders a clear, practical path through four essential questions:
- Why quantum computing matters now, and why the window for early strategic advantage is open today
- How to evaluate vendors objectively, using a structured framework rather than marketing claims
- How to design an effective pilot, so early investment produces real, usable evidence
- How to take your first steps with confidence, whether you're just starting to explore or ready to scale
It also includes a glossary of key terms, so readers new to the field aren't left decoding jargon before they can evaluate a single vendor.
Who Should Read It
The guide is written for CTOs, CIOs, CISOs, R&D leaders, and program directors across enterprise and public sector organizations, at any stage of quantum familiarity. Whether your organization hasn't yet started exploring quantum computing, or you already have a program underway and are looking to sharpen your evaluation process, the framework inside is designed to apply.
How to Use It
The evaluation framework at the core of the guide isn't specific to any one vendor; it's designed to be applied to any quantum computing solution you're considering, so you can make an apples-to-apples comparison based on your organization's actual needs. The guide also walks through how Quantinuum maps to that same framework, and what it looks like to work with Quantinuum as a co-development partner, should you want a concrete reference point alongside the general framework.
Start With Confidence, Not Guesswork
Quantum computing is a strategic decision, not just a technical one. The organizations that approach it with a clear framework, rather than reacting to the noise, will be the ones positioned to capture real value as the technology matures.
- QUOPS is a new, architecture-agnostic benchmark designed to measure quantum performance across physical- and logical-qubit systems, using two metrics: Q (computation size) and Ω (operations per second).
- It addresses the limits of traditional metrics like qubit count, gate fidelity, and gate speed by measuring what a quantum system can actually execute successfully—including the effects of error correction, decoding, mitigation, compilation, and other system-level factors.
- QUOPS aims to create a common language for the industry, helping vendors demonstrate progress, enabling buyers and governments to make more objective procurement decisions, and giving researchers a standardized way to track progress toward utility-scale, fault-tolerant quantum computing.
Quantum computing is entering a new era. As systems move from Noisy Intermediate-Scale Quantum (NISQ) toward Fault-Tolerant Application-Scale Quantum (FASQ), traditional metrics like qubit count, gate fidelity, and gate speed are no longer enough to describe what a machine can actually deliver.
Introducing QUOPS
Developed by Sandia National Laboratories, with input from Quantinuum and NVIDIA, QUOPS—the Quantum Universal Operations Performance System—is a common, architecture-agnostic benchmark for measuring quantum performance across both physical- and logical-qubit systems on the path toward quantum utility.
QUOPS can be applied to different architectures, codes, modalities, and levels of fault tolerance. QUOPS runs the same randomized workloads across different computational shapes, measures whether each workload succeeds, identifies the boundary of a system’s capability region, and reports two summary metrics:
- Q: the largest benchmark circuit size that passes the success threshold inside a utility-motivated region. Size is defined as 2*(width)*(depth).
- Ω: the effective operations per second at that point.
The result is a direct measure of how much computation a system can perform and how quickly it can do so. Together, these measurements provide a two-dimensional view of capability while reducing system performance to a common currency: quantum operations.
Why Quantum Computing Needs a New Metric
Component-level metrics remain essential for engineering. Qubit count, two-qubit fidelity, and gate speed can reveal control errors, crosstalk, leakage, connectivity constraints, and other system limitations. But they do not necessarily predict system-level performance.
Fault tolerance makes this gap even larger. Physical operations become logical computation with the addition of logical encoding, syndrome measurement, decoding, logical gate construction, magic-state production, routing, and control. Ultimately, this means that fault tolerance expands the relevant currencies of computation. Code distance, logical fidelity, magic-state throughput, decoding, connectivity, and space-time volume can matter far more for performance than raw qubit count or individual gate speeds.
This creates a growing challenge for buyers, governments, and researchers. As organizations move from experimentation toward larger-scale and potentially on-premise quantum systems, they need to know a simple thing:
What computation can a machine actually execute successfully?
QUOPS addresses that question by measuring the integrated system rather than inferring performance from individual components.
This is particularly important as the field considers workloads requiring roughly 10⁹–10¹² operations on thousands of qubits. Today's measured capabilities are still orders of magnitude smaller; QUOPS turns that gap into a measurable quantity.
QUOPS for Procurement
QUOPS can also provide a practical layer for quantum procurement and planning.
HPC centers need to understand when quantum computing will become useful for real workloads. Customers may have a goal of procuring a system that can, for example, run a trillion error-free operations. Today, answering these questions can require complex resource estimates that depend on hardware modality, QEC code, magic-state factories, decoding, compilation, and other architectural choices.
In both cases, QUOPS provides a simpler system-level reference point: Q describes the size of computation a machine can execute, while Ω describes its effective throughput. Furthermore, because QUOPS is architecture-neutral and includes anti-gaming provisions, it can also help buyers compare competing systems without relying solely on vendor-selected metrics or announcements.
How Quantinuum stacks up
While QUOPS is a new benchmark, it has already been measured on several vendors’ hardware. This marks an important step for our industry: we can now compare vendors directly, assessing their capabilities in a way that flattens the differences introduced by modality and architecture choices.
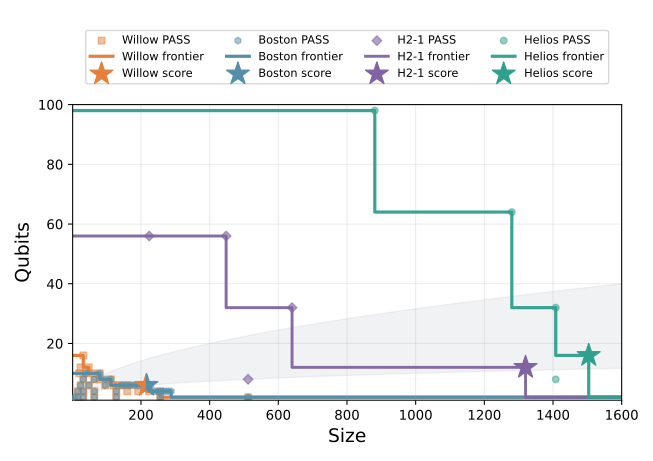
Figure 1. The QUOPS capability region and score for state-of-the-art processors from Quantinuum, Google, and IBM (adapted from Figure 2 of the scientific publication co-authored by Quantinuum, Sandia National Laboratories, and NVIDIA). QUOPS specifies a random circuit construction that can be built for a specified width (number of qubits) and size (number of quantum gates). A set of circuits is run at several width and size points and the average fidelity of those circuits are measured and compared to a predefined threshold. Each labeled point above represents experimental data from QUOPS circuits that passed the threshold with high confidence. The lines are filled capability limits of each machine between the points. The stars indicate the QUOPS score (Q), which is the experimental data point that passes the threshold with maximum size inside the shaded cone of width2 ≤ size ≤ width3.
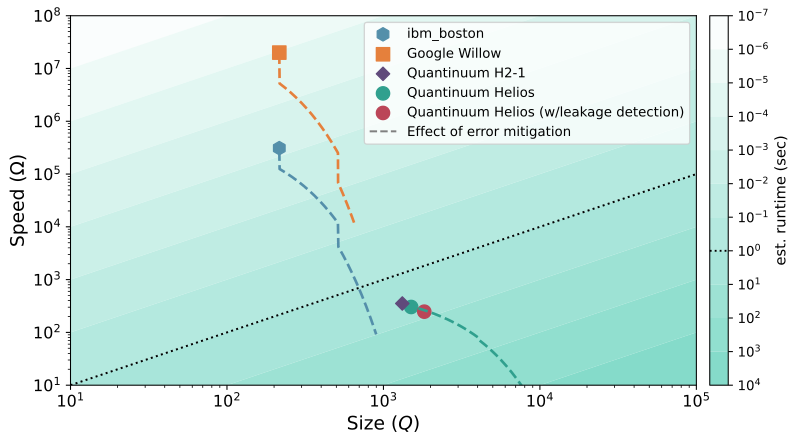
Figure 2. The QUOPS score (Q) vs rate (Ω) for state-of-the-art processors from Quantinuum, Google, and IBM (adapted from Figure 2 of the QUOPS scientific publication co-authored by Quantinuum, Sandia National Laboratories, and NVIDIA). Each point is the maximum QUOPS circuit size that passes the threshold within the specified cone and rate that it was run. The dashed lines indicate the extrapolated effect of error mitigation, which attenuates the rate by including the shot overhead needed for general-purpose error mitigation. The gradient lines show the estimated runtime of a circuit at a given score and rate.
Figures 1 and 2 show how QUOPS quantifies the capability tradeoffs between different systems. Willow and Boston are superconducting systems with very fast gate speeds but limited connectivity, while Helios is a trapped-ion QCCD system with effective all-to-all connectivity but much slower gates. Willow and Boston have smaller capability regions and QUOPS scores but higher QUOPS rates; while Helios reaches larger capability regions and QUOPS scores but lower QUOPS rates. All three systems have the ability to trade speed for larger circuits with error mitigation. This is commonly assumed in the community but is nicely quantified with the QUOPS rate, which accounts for the corresponding sampling overheads of general error mitigation techniques (as shown by the dashed lines in Figure 2).
Building a New Benchmarking Ecosystem
QUOPS will not replace every quantum benchmark. The field will continue to need application-specific suites, component-level measurements, hybrid-HPC benchmarks, and independent verification.
QUOPS instead serves as a common system-level yardstick that can make roadmaps more comparable, procurement more objective, and progress easier to track.
We are calling on vendors to report QUOPS metrics (Q, Ω) and capability regions alongside existing metrics, buyers and agencies to consider QUOPS thresholds in RFPs, and researchers to contribute fault-tolerant architectures and resource estimates.
As quantum computers become fault tolerant, success will no longer be defined simply by how many qubits a machine contains or how low its error rates are.
It will be defined by the computation the machine can deliver.
QUOPS is a step toward measuring that capability—and toward giving the quantum industry a benchmark built for the era ahead.
- A new experiment tests what makes a quantum computer genuinely quantum by using a simple game that demonstrates a provable advantage from quantum superposition, without relying on entanglement or assumptions about classical computational difficulty.
- The test was demonstrated on Quantinuum’s System Model H2, where researchers ran thousands of circuits and observed results close to theoretical quantum predictions. The approach also offers an efficiently verifiable way to test for non-classical behavior.
- The work provides a new way to think about quantum-computing verification: rather than focusing only on metrics like qubit count, we can ask whether a machine demonstrates capabilities that fundamentally distinguish quantum systems from classical ones. This validates that the computer is working as intended.
Building a quantum computer is one thing. Showing that it is genuinely using quantum mechanics is another.
A new experiment, just published in Nature Communications, takes a fresh approach to that question. Instead of relying on entanglement or the complex calculations often used to benchmark quantum computers, researchers designed a simple game (initially published in Physical Review Letters) that tests something more fundamental: quantum superposition.
Using superposition, the team constructed a game where quantum mechanics provides a provable advantage over classical approaches. Once the game was set, the team ran it on real hardware. The results showed a clear performance gap between the best possible classical system and our System Model H2 – a gap that only grew as the test became more difficult.
A game that classical computers can’t win
The game is played by a single player with access to a computer. The player receives a quantum state representing a set of numbers—for example, {0, 1, 5, 7}. Their goal is to return a number that belongs to the complement of that set: {2, 3, 4, 6}.
That sounds simple. But as the size of the sets grows, something remarkable happens.
A classical strategy needs to test many numbers to succeed. A quantum strategy, however, succeeds in one step. The authors show that the quantum strategy has a score that grows exponentially faster.
Importantly, this isn't based on an assumption that this problem is difficult for classical computers. The separation is mathematically proven. In other words, the researchers can show that the quantum advantage exists without relying on unproven assumptions from complexity theory.
Using our System Model H2, the experimenters were able to confirm the theoretically derived separation between the quantum and the classical strategy (up to the largest sizes they could fit on the quantum processor) with high confidence – showing that the violation remained close to exponential.
Testing quantum mechanics without entanglement
Many famous experiments testing quantum behavior rely on entanglement and non-locality, where multiple parties share parts of a quantum system.
This experiment is different.
There is only one player, who has access to the entire quantum system. The advantage comes from superposition—the ability of a quantum system to exist in a combination of states until it is measured.
That distinction matters because it provides another way to ask whether a quantum computer is actually behaving quantum mechanically.
The researchers turned their game into an experimental test and ran thousands of different circuits on Quantinuum's System Model H2. The scores they observed were close to the theoretical predictions for a quantum strategy.
Why verification matters
One of the challenges with existing quantum-computing demonstrations is figuring out whether the machine really produced the result it was supposed to produce.
For example, random circuit sampling can be extremely difficult to verify classically as systems become larger. That creates a tension: you want to demonstrate that a quantum computer is doing something a classical computer cannot easily reproduce, but you also need a practical way to check the result.
The complement-sampling game offers a different approach. The violation of classical performance can be efficiently verified with a classical computer.
That makes the test potentially more scalable: you don't need to reproduce the entire quantum computation on a classical computer just to determine whether the machine demonstrated non-classical behavior.
So, what makes a quantum computer “quantum”?
The deeper message of the experiment is that demonstrating a quantum computer isn't simply about having qubits.
A convincing demonstration should show that the machine is exploiting properties that genuinely distinguish quantum computation from classical computation. Here, the researchers focus on one of those defining properties—superposition—and construct a game where quantum mechanics provides a provable advantage.
This first experimental demonstration of complement sampling doesn't close every possible loophole, which is common for this sort of experiment – closing the major experimental loopholes in Bell-inequality tests took decades—a body of work that ultimately contributed to the 2022 Nobel Prize in Physics. The researchers explicitly note that the implementation relies on assumptions about how the input state is prepared, so the experimental results should be interpreted with some caution.
Still, the work provides a new way to probe the boundary between classical and quantum computation.
And that may be the most interesting part: rather than asking only “How many qubits does the machine have?”, we can ask a more meaningful question—
“What can this machine do that only a quantum system can?”
That is ultimately what it takes for a quantum computer to actually be quantum.