

Technical perspective: By the end of the decade, we will deliver universal, fully fault-tolerant quantum computing
By Dr. Harry Buhrman, Chief Scientist for Algorithms and Innovation, and Dr. Chris Langer, Fellow
This week, we confirm what has been implied by the rapid pace of our recent technical progress as we reveal a major acceleration in our hardware road map. By the end of the decade, our accelerated hardware roadmap will deliver a fully fault-tolerant and universal quantum computer capable of executing millions of operations on hundreds of logical qubits.
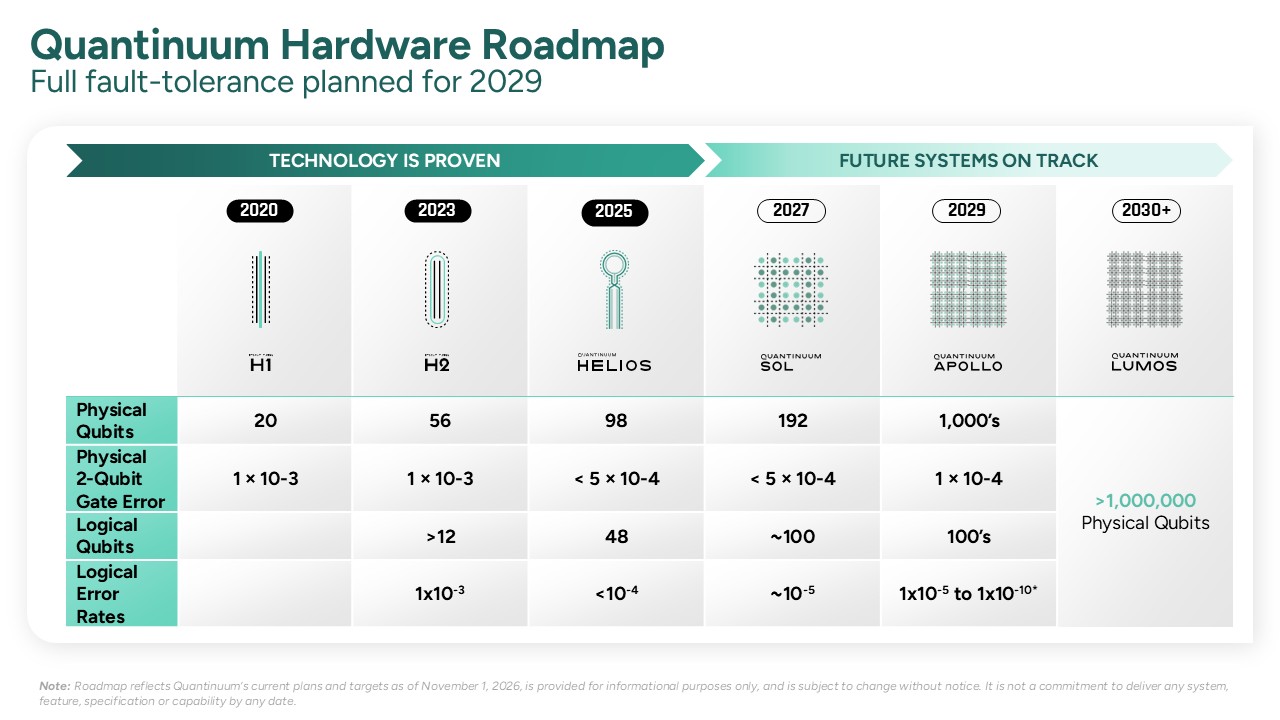
The next major milestone on our accelerated roadmap is Quantinuum Helios™, Powered by Honeywell, a device that will definitively push beyond classical capabilities in 2025. That sets us on a path to our fifth-generation system, Quantinuum Apollo™, a machine that delivers scientific advantage and a commercial tipping point this decade.

What is Apollo?
We are committed to continually advancing the capabilities of our hardware over prior generations, and Apollo makes good on that promise. It will offer:
- Thousands of physical qubits
- Physical error rate of 10-4
- All of our most competitive features: all-to-all connectivity, low crosstalk, mid-circuit measurement and qubit re-use
- Conditional logic
- Real-time classical co-compute
- Physical variable angle 1 qubit and 2 qubit gates
- Hundreds of logical qubits
- Logical error rates better than 10-6 with analysis based on recent literature estimating as low as 10-10
By leveraging our all-to-all connectivity and low error rates, we expect to enjoy significant efficiency gains in terms of fault-tolerance, including single-shot error correction (which saves time) and high-rate and high-distance Quantum Error Correction (QEC) codes (which mean more logical qubits, with stronger error correction capabilities, can be made from a smaller number of physical qubits).
Studies of several efficient QEC codes already suggest we can enjoy logical error rates much lower than our target 10-6 – we may even be able to reach 10-10, which enables exploration of even more complex problems of both industrial and scientific interest.
Error correcting code exploration is only just beginning – we anticipate discoveries of even more efficient codes. As new codes are developed, Apollo will be able to accommodate them, thanks to our flexible high-fidelity architecture. The bottom line is that Apollo promises fault-tolerant quantum advantage sooner, with fewer resources.
Like all our computers, Apollo is based on the quantum charged coupled device (QCCD) architecture. Here, each qubit’s information is stored in the atomic states of a single ion. Laser beams are applied to the qubits to perform operations such as gates, initialization, and measurement. The lasers are applied to individual qubits or co-located qubit pairs in dedicated operation zones. Qubits are held in place using electromagnetic fields generated by our ion trap chip. We move the qubits around in space by dynamically changing the voltages applied to the chip. Through an alternating sequence of qubit rearrangements via movement followed by quantum operations, arbitrary circuits with arbitrary connectivity can be executed.
The ion trap chip in Apollo will host a 2D array of trapping locations. It will be fabricated using standard CMOS processing technology and controlled using standard CMOS electronics. The 2D grid architecture enables fast and scalable qubit rearrangement and quantum operations – a critical competitive advantage. The Apollo architecture is scalable to the significantly larger systems we plan to deliver in the next decade.
What is Apollo good for?
Apollo’s scaling of very stable physical qubits and native high-fidelity gates, together with our advanced error correcting and fault tolerant techniques will establish a quantum computer that can perform tasks that do not run (efficiently) on any classical computer. We already had a first glimpse of this in our recent work sampling the output of random quantum circuits on H2, where we performed 100x better than competitors who performed the same task while using 30,000x less power than a classical supercomputer. But with Apollo we will travel into uncharted territory.
The flexibility to use either thousands of qubits for shorter computations (up to 10k gates) or hundreds of qubits for longer computations (from 1 million to 1 billion gates) make Apollo a versatile machine with unprecedented quantum computational power. We expect the first application areas will be in scientific discovery; particularly the simulation of quantum systems. While this may sound academic, this is how all new material discovery begins and its value should not be understated. This era will lead to discoveries in materials science, high-temperature superconductivity, complex magnetic systems, phase transitions, and high energy physics, among other things.
In general, Apollo will advance the field of physics to new heights while we start to see the first glimmers of distinct progress in chemistry and biology. For some of these applications, users will employ Apollo in a mode where it offers thousands of qubits for relatively short computations; e.g. exploring the magnetism of materials. At other times, users may want to employ significantly longer computations for applications like chemistry or topological data analysis.
But there is more on the horizon. Carefully crafted AI models that interact seamlessly with Apollo will be able to squeeze all the “quantum juice” out and generate data that was hitherto unavailable to mankind. We anticipate using this data to further the field of AI itself, as it can be used as training data.
The era of scientific (quantum) discovery and exploration will inevitably lead to commercial value. Apollo will be the centerpiece of this commercial tipping point where use-cases will build on the value of scientific discovery and support highly innovative commercially viable products.
Very interestingly, we will uncover applications that we are currently unaware of. As is always the case with disruptive new technology, Apollo will run currently unknown use-cases and applications that will make perfect sense once we see them. We are eager to co-develop these with our customers in our unique co-creation program.
How do we get there?
Today, System Model H2 is our most advanced commercial quantum computer, providing 56 physical qubits with physical two-qubit gate errors less than 10-3. System Model H2, like all our systems, is based on the QCCD architecture.
Starting from where we are today, our roadmap progresses through two additional machines prior to Apollo. The Quantinuum Helios™ system, which we are releasing in 2025, will offer around 100 physical qubits with two-qubit gate errors less than 5x10⁻⁴. In addition to expanded qubit count and better errors, Helios makes two departures from H2. First, Helios will use 137Ba+ qubits in contrast to the 171Yb+ qubits used in our H1 and H2 systems. This change enables lower two-qubit gate errors and less complex laser systems with lower cost. Second, for the first time in a commercial system, Helios will use junction-based qubit routing. The result will be a “twice-as-good" system: Helios will offer roughly 2x more qubits with 2x lower two-qubit gate errors while operating more than 2x faster than our 56-qubit H2 system.
After Helios we will introduce Quantinuum Sol™, our first commercially available 2D-grid-based quantum computer. Sol will offer hundreds of physical qubits with two-qubit gate errors less than 2x10⁻⁴, operating approximately 2x faster than Helios. Sol being a fully 2D-grid architecture is the scalability launching point for the significant size increase planned for Apollo.
Opportunity for early value creation discovery in Helios and Sol
Thanks to Sol’s low error rates, users will be able to execute circuits with up to 10,000 quantum operations. The usefulness of Helios and Sol may be extended with a combination of quantum error detection (QED) and quantum error mitigation (QEM). For example, the [[k+2, k, 2]] iceberg code is a light-weight QED code that encodes k+2 physical qubits into k logical qubits and only uses an additional 2 ancilla qubits. This low-overhead code is well-suited for Helios and Sol because it offers the non-Clifford variable angle entangling ZZ-gate directly without the overhead of magic state distillation. The errors Iceberg fails to detect are already ~10x lower than our physical errors, and by applying a modest run-time overhead to discard detected failures, the effective error in the computation can be further reduced. Combining QED with QEM, a ~10x reduction in the effective error may be possible while maintaining run-time overhead at modest levels and below that of full-blown QEC.
Why accelerate our roadmap now?
Our new roadmap is an acceleration over what we were previously planning. The benefits of this are obvious: Apollo brings the commercial tipping point sooner than we previously thought possible. This acceleration is made possible by a set of recent breakthroughs.
First, we solved the “wiring problem”: we demonstrated that trap chip control is scalable using our novel center-to-left-right (C2LR) protocol and broadcasting shared control signals to multiple electrodes. This demonstration of qubit rearrangement in a 2D geometry marks the most advanced ion trap built, containing approximately 40 junctions. This trap was deployed to 3 different testbeds in 2 different cities and operated with 2 different collections of dual-ion-species, and all 3 cases were a success. These demonstrations showed that the footprint of the most complex parts of the trap control stay constant as the number of qubits scales up. This gives us the confidence that Sol, with approximately 100 junctions, will be a success.
Second, we continue to reduce our two-qubit physical gate errors. Today, H1 and H2 have two-qubit gate errors less than 1x10⁻³ across all pairs of qubits. This is the best in the industry and is a key ingredient in our record >2 million quantum volume. Our systems are the most benchmarked in the industry, and we stand by our data - making it all publicly available. Recently, we observed an 8x10⁻⁴ two-qubit gate error in our Helios development test stand in 137Ba+, and we’ve seen even better error rates in other testbeds. We are well on the path to meeting the 5x10⁻⁴ spec in Helios next year.
Third, the all-to-all connectivity offered by our systems enables highly efficient QEC codes. In Microsoft’s recent demonstration, our H2 system with 56 physical qubits was used to generate 12 logical qubits at distance 4. This work demonstrated several experiments, including repeated rounds of error correction where the error in the final result was ~10x lower than the physical circuit baseline.
In conclusion, through a combination of advances in hardware readiness and QEC, we have line-of-sight to Apollo by the end of the decade, a fully fault-tolerant quantum advantaged machine. This will be a commercial tipping point: ushering in an era of scientific discovery in physics, materials, chemistry, and more. Along the way, users will have the opportunity to discover new enabling use cases through quantum error detection and mitigation in Helios and Sol.
Quantinuum has the best quantum computers today and is on the path to offering fault-tolerant useful quantum computation by the end of the decade.
About Quantinuum
Quantinuum, the world’s largest integrated quantum company, pioneers powerful quantum computers and advanced software solutions. Quantinuum’s technology drives breakthroughs in materials discovery, cybersecurity, and next-gen quantum AI. With over 500 employees, including 370+ scientists and engineers, Quantinuum leads the quantum computing revolution across continents.
Visit Quantinuum at SC26 – Booth 4838
Quantinuum is heading to SC26 in Chicago, and we'd love to see you at Booth 4838 in the Quantum Junction. Stop by during exhibit hours to catch partner theater sessions throughout the day, see what's new with Helios and Nexus, and talk with our team about how quantum computing is expanding its footprint in the HPC datacenter, including hybrid quantum-classical applications.
In our booth:
Join our experts and partners at our kiosks and for short sessions in our theater running throughout the day. Topics include:
- Next Gen Enterprise Computing Partners – how leading enterprises are bringing quantum into their computing strategy
- Error Correction: The Path to Fault Tolerance – where quantum error correction stands today and what comes next
- Develop for the Fault Tolerant Era with Nexus – building, running, and managing quantum workflows on the Nexus platfor
- Helios: The Most Accurate Quantum Computer – a closer look at our latest system and what its performance makes possible
- Startup Partners: Accelerating Quantum Ecosystem Innovation – how startups are building on Quantinuum technology
- Real Commercial Impact – quantum applications in pharma, chemicals, materials, and finance
Coffee and cookies on us
Need a break from the show floor? Our barista will be serving up coffee, and we'll have fresh cookies every afternoon. Grab a cup, pull up a seat for a theater session, and chat with the team.
Catch Quantinuum in the SC26 program
Our experts are also speaking in the SC26 technical program. Add these sessions to your schedule (all times CST):
Speaking Sessions
November 15th
9:45 – 10:00am | Room: W178a
Quantum-HPC Workflows Across Multiple Quantum Computing Platforms: Two Case Studies – part of the 2nd International Workshop for Software Frameworks and Workload Management on Quantum-HPC Ecosystems
Presenting: Philipp Seitz
November 16th
3:30 – 4:00pm | Room: W179a
Software for Large Scale Application – part of the 2nd Annual Workshop on Large-Scale Quantum-Classical Computing (LSQCC)
Presenting: Juan Pederson
November 19th
3:30 – 4:00pm | Room: W181abc
Bringing Quantum Computing to the HPC Datacenter
Presenting: Kentaro Yamamoto
See you in Chicago
Whether you're exploring quantum for the first time or planning how to integrate it with your HPC environment, our team is ready to talk. Find us at Booth 4838 in the Quantum Junction, November 16–19.
- RIKEN and Quantinuum have upgraded Reimei to System Model H2, bringing quantum advantage into sight with their hybrid supercomputing platform.
- Using the new quantum processor, a Quantinuum-led frontier project team is combining quantum and classical data to map complex material behavior, using Reimei for classically challenging regimes, the JHPC-quantum GPU supercomputer ROQUO and the supercomputer Fugaku for large-scale simulation and AI, and generative models to predict unexplored conditions.
- A second frontier project is focused on creating a scalable hybrid workflow for biomolecular chemistry, combining quantum computing, supercomputing, and AI to simulate the excited-state properties of complex molecules—with potential applications in drug discovery, advanced materials, and solar energy. Once these projects conclude, Reimei will start regular operations under the Test User Program.
The future of supercomputing just got an upgrade in Japan.
RIKEN and Quantinuum have upgraded the Reimei quantum computer to Quantinuum’s System Model H2, bringing quantum advantage into sight with their hybrid supercomputing platform. Their combination of Reimei, the supercomputer Fugaku, and the ROQUO GPU supercomputer is a world-leading platform that reaches far beyond what any modality can currently offer on its own.
With 56 fully-connected high-fidelity qubits, Reimei is already supporting two frontier projects in quantum materials and biomolecular chemistry. Both are designed to move hybrid computing beyond infrastructure demonstrations and toward high-value scientific applications.
Expanding the landscape of supercomputing
Many scientific problems contain both classically ‘accessible’ and classically ‘inaccessible’ regions.
For example, a classical supercomputer may efficiently explore broad areas of a model’s parameter space but struggle near a phase transition, where correlations grow and the required computational resources increase sharply. In chemistry, classical methods can model much of a molecule accurately but encounter difficulties in small, strongly correlated regions that determine its most important properties. In contrast, quantum computers can often handle these problems deftly, thanks to their native “quantumness”.
We have been working to bring quantum computers together with classical computers, using them as specialized accelerators inside broader heterogeneous computing environments.
RIKEN’s platform is our first instantiation of that vision, bringing together three complementary resources:
- Fugaku, RIKEN’s classical supercomputer, provides large-scale classical modeling, data processing, and established scientific computing methods.
- ROQUO, RIKEN’s GPU supercomputer, supports tensor-network simulation, AI training, and massively parallel computation.
- Reimei, RIKEN’s quantum computer, performs selected calculations involving quantum states and correlations that become prohibitively expensive to represent classically.
Quantinuum Nexus’s hybrid workflow management system coordinates these resources, allowing jobs running on classical infrastructure to submit quantum tasks to Reimei and incorporate the results into a larger calculation.
This foundation has been operational for some time now. A major result from earlier this year used Reimei and Fugaku together to investigate chemical reactions inside biomolecules. Recently, we expanded our work using Fugaku and QPUs: coordinating Reimei and ibm_kobe in a combined VQE–QPE workflow to calculate a simple system’s ground-state energy. In all these cases, quantum hardware augmented the classical supercomputer, with each processor assigned the part of the calculation best suited to its strengths.
The addition of ROQUO now extends this architecture with GPU-accelerated simulation, optimization, and AI. Combined with the upgrade of Reimei to System Model H2, we have launched two frontier projects to push the forefront of scientific computing and prove out Reimei’s capability.
Project 1: GenQAI for materials discovery
The first frontier project brings together quantum simulation, classical tensor networks, and generative AI to investigate many-body physics.
The goal is to discover a sort of ‘treasure map’ for a material: the phase diagram. A phase diagram is a multidimensional map that shows how a material’s properties change when variables like temperature, pressure, or magnetic field are changed. Phase diagrams can hold the secret to exotic properties like superconductivity; can point the way to novel materials for memory devices and energy transfer, or can help to elucidate new medical imaging techniques.
Phase diagrams are extremely valuable, but they can be difficult to calculate or measure. To measure one, you would need a laboratory that could detect material properties at hundreds of points while also generating repeatable parameter changes. Computationally, the problem is similar, but (as mentioned above) one often encounters regions where correlations extend across larger portions of the system, making it incredibly difficult to compute. On top of this, during pre-thermal dynamics or phase transitions, entanglement can grow rapidly, further stretching classical computing capacity.
Reimei is well suited to probing these difficult regimes. We have already used System Model H2 to explore quantum magnetism at scales that frustrate classical approaches. Its high-fidelity operations and flexible qubit connectivity enable the execution of demanding quantum many-body circuits at a scale where matched-accuracy classical simulation can become impractical. But this quantum data is also expensive to generate. The goal is therefore to use it selectively.
ROQUO can perform dense tensor-network simulations across classically tractable regions, parallelizing calculations over model parameters and bond dimensions. This allows Reimei to focus on regimes requiring deep time evolution circuits, where long-range correlations and growing entanglement can sharply increase the cost of classical simulation. Classical data alone is not enough to train a robust generative model across the phase diagram, and that is why quantum data becomes essential.
The team has already collected hardware data for a 6 × 6 two-dimensional spin model, trained a Transformer model for zero-noise extrapolation across the parameter space, and applied active learning to prioritize additional quantum data collection.
Using these results, the team trained a generative AI model capable of learning a parametric representation of the fluctuations and many-body correlations across the combined dataset: the classically reachable and the classically hard regions are both well described by our trained generative model.
Once trained, the generative model is used at inference time on ROQUO to sample the phase diagram at conditions that have not yet been simulated and obtain results for material properties with good accuracy. Step by step, the phase diagram for a material is filled out, generating a ‘treasure map’ of its key behaviors.
For materials researchers, this ‘map’ can add up to a lot. Quantum computers, such as Reimei, could contribute to more accurate predictions of phase diagrams and response functions, helping researchers understand how materials respond to external conditions, a key determinant in electronics, sensing, medical imaging, energy infrastructure, and more.
Project 2: A hybrid blueprint for biomolecular chemistry
The second frontier project applies the same hybrid philosophy to one of quantum computing’s most anticipated applications: the accurate simulation of complex molecules.
Researchers from RIKEN, NVIDIA, and Quantinuum are working together to develop a scalable QPU–GPU–HPC workflow for predicting realistic chemical properties of biomolecular systems. Our initial target is zinc porphyrin, a light-absorbing molecule whose response to light is influenced by its surrounding environment.
While many current projects in quantum computational chemistry are focused on ground state searches, this project focuses on excited states—the electronically energized states involved in processes such as light absorption. These states are typically more complicated to calculate than a molecule’s ground state, but they are essential to understanding how photoactive molecules function in the real world.
As before, the hybrid workflow assigns each part of the calculation to the most appropriate processor:
- Fugaku and conventional HPC methods represent the chromophore’s larger molecular environment and perform the broader chemistry workflow.
- ROQUO’s NVIDIA GPUs support optimization, configuration-interaction calculations, AI-assisted circuit design, and spectral reconstruction.
- Reimei concentrates on strongly correlated electronic regions and searches for important electron configurations that classical methods may miss.
This gives the QPU a focused role: discovering important determinants (candidate electronic configurations) that can enrich the classical calculation. The HPC systems then use those configurations to calculate energies and reconstruct experimentally meaningful properties, including the molecule’s absorption spectrum.
This separation of responsibilities makes the workflow scalable. The QPU is not asked to represent the entire biomolecular environment. Instead, it targets the part of the electronic structure problem where quantum sampling could add information that is difficult to obtain through classical methods alone. To help tackle this, we developed a new hybrid method to solve complicated electronic structure problems.
This approach could provide a blueprint for studying functional biomolecules at the accuracy needed for industrial research. Applications could eventually span drug discovery, biomolecular engineering, advanced materials, and the design of more efficient light-harvesting systems such as solar cells.
A platform for the next era of discovery
Hybrid computing is sometimes described as a future architecture. At RIKEN, these foundations have been operational since 2025 – and they just got a massive upgrade.
Reimei supplies high-fidelity quantum computation. Fugaku provides the scale of a world-leading supercomputer. ROQUO adds accelerated computing and AI. The Nexus workflow management system brings the systems together into coordinated scientific workflows.
Together, they demonstrate a broader principle: the value of quantum computing will not be measured by what a QPU can do in isolation, but by what becomes possible when quantum computers are integrated into the world’s most advanced computing environments.
With Reimei, RIKEN and Quantinuum are building that future now—and building it with Japan.
*Reimei deployment is supported by the New Energy and Industrial Technology Development Organization (NEDO), an organization under the jurisdiction of Japan's Ministry of Economy, Trade and Industry (METI)'s "Development of Integrated Utilization Technology for Quantum and Supercomputers" as part of the "Project for Research and Development of Enhanced Infrastructures for Post 5G Information and Communications Systems."
Fault-tolerant quantum computing is entering a new phase. At Quantinuum, we have demonstrated almost every piece needed for large-scale fault tolerant hardware, from a universal fault tolerant gate set, to a proven fault tolerant architecture, to large-scale materials simulations with encoded qubits, at world-leading fidelity.
However, that’s only half the battle. Developers need practical tools that make this technology accessible without needing to become experts in quantum error correction.
A good quantum computing software stack should capture and reuse QEC1 expertise, turning the complexity of fault tolerance into capabilities that developers can build with.
"Our ambition is for Nexus to be the platform developers turn to for the fault-tolerant era." - Dr. Rajeeb Hazra, President & CEO, Quantinuum
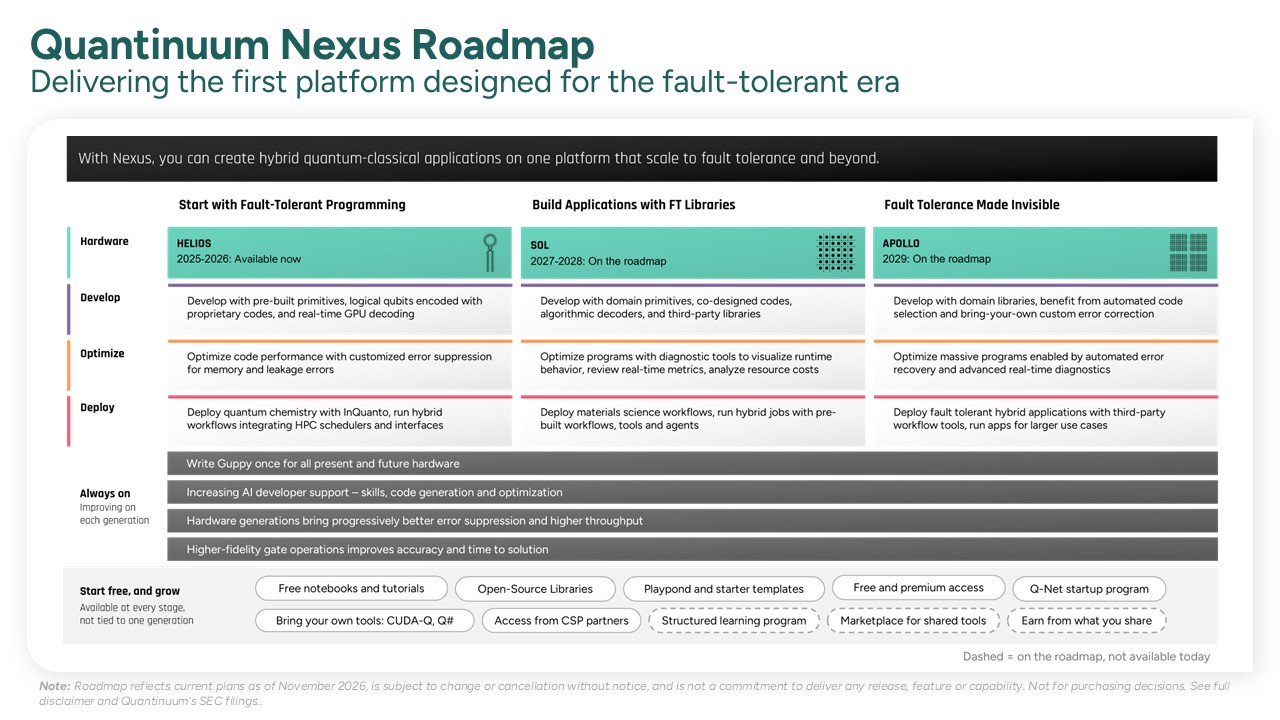
Here at Quantinuum, we are working hard to make that a reality. Since its launch in 2024, Nexus has grown from managing cloud-based quantum workflows into an environment for end-to-end application development and deployment. Our new multi-year roadmap builds on that foundation, connecting software capabilities with each generation of Quantinuum hardware through Apollo, our universal, fault-tolerant quantum computer planned for 2029. Nexus will progressively handle more of the complexity of fault-tolerant development, helping developers build applications that grow in capability as the hardware advances.
With Nexus, you can explore quantum chemistry and materials using InQuanto, and you can make it fault tolerant using our pre-built fault tolerant primitives. You can use GPUs to decode errors in real time, while benefitting from hardware enabled error suppression like Leakage Repump or Dynamical Decoupling. You can also connect your HPC to our QPUs and use Nexus’ Hybrid workflow management system to enjoy the best of both worlds seamlessly.
Of course, all of the above needs a language framework that is fault tolerant in the first place. That’s why we are thrilled to introduce Guppy FT – Nexus’ fault tolerant quantum programming framework, and Guppy Algorithms, Nexus’ library of reusable algorithmic primitives.
Developing for the fault tolerant era: Guppy FT
“The field of QEC is quite abstract, and it is hard for non-experts to gauge what is feasible on current devices. Guppy FT promotes a game-changing paradigm: QEC is no longer just theory, it is also engineering, it is something you can use.” - the Guppy FT team
As we have been saying, the NISQ2 era is coming to an end. The next challenge is to turn fault tolerance from a hardware milestone into a capability developers can use.
We have built the physical QEC architecture: high-fidelity physical qubits, distance scaling and low logical error rates, all-to-all connectivity and reconfigurable qubits, all the primitives working harmoniously, real-time decoding, circuit optimization, and so on. The next step is ensuring our users can easily enjoy the above: with a fault tolerant programming language framework (Guppy FT) inside a fault tolerant user platform (Nexus).
Guppy FT brings three complementary capabilities together:
- A framework for QEC experts to define fault-tolerant architectures.
- Automatic compilation that takes programs written in standard Guppy and turns them into programs running on fault-tolerant architectures.
- Proprietary codes from our own QEC experts that get you the best performance out of our world-leading hardware.
The result is a programming experience in which developers can write quantum algorithms without having to understand the details of the underlying error-correction architecture, while QEC experts retain the ability to define and optimize the architectures that power those programs.
This separation between what the program does and how it is made fault tolerant is central to the approach.
With Guppy FT, QEC experts define the fault-tolerant architecture once, and application developers can program on it without needing to become QEC experts themselves. Developers can continue to write programs in standard, QEC-agnostic Guppy. The Guppy FT framework then automatically lowers those programs into an encoded, fault-tolerant form suitable for execution.
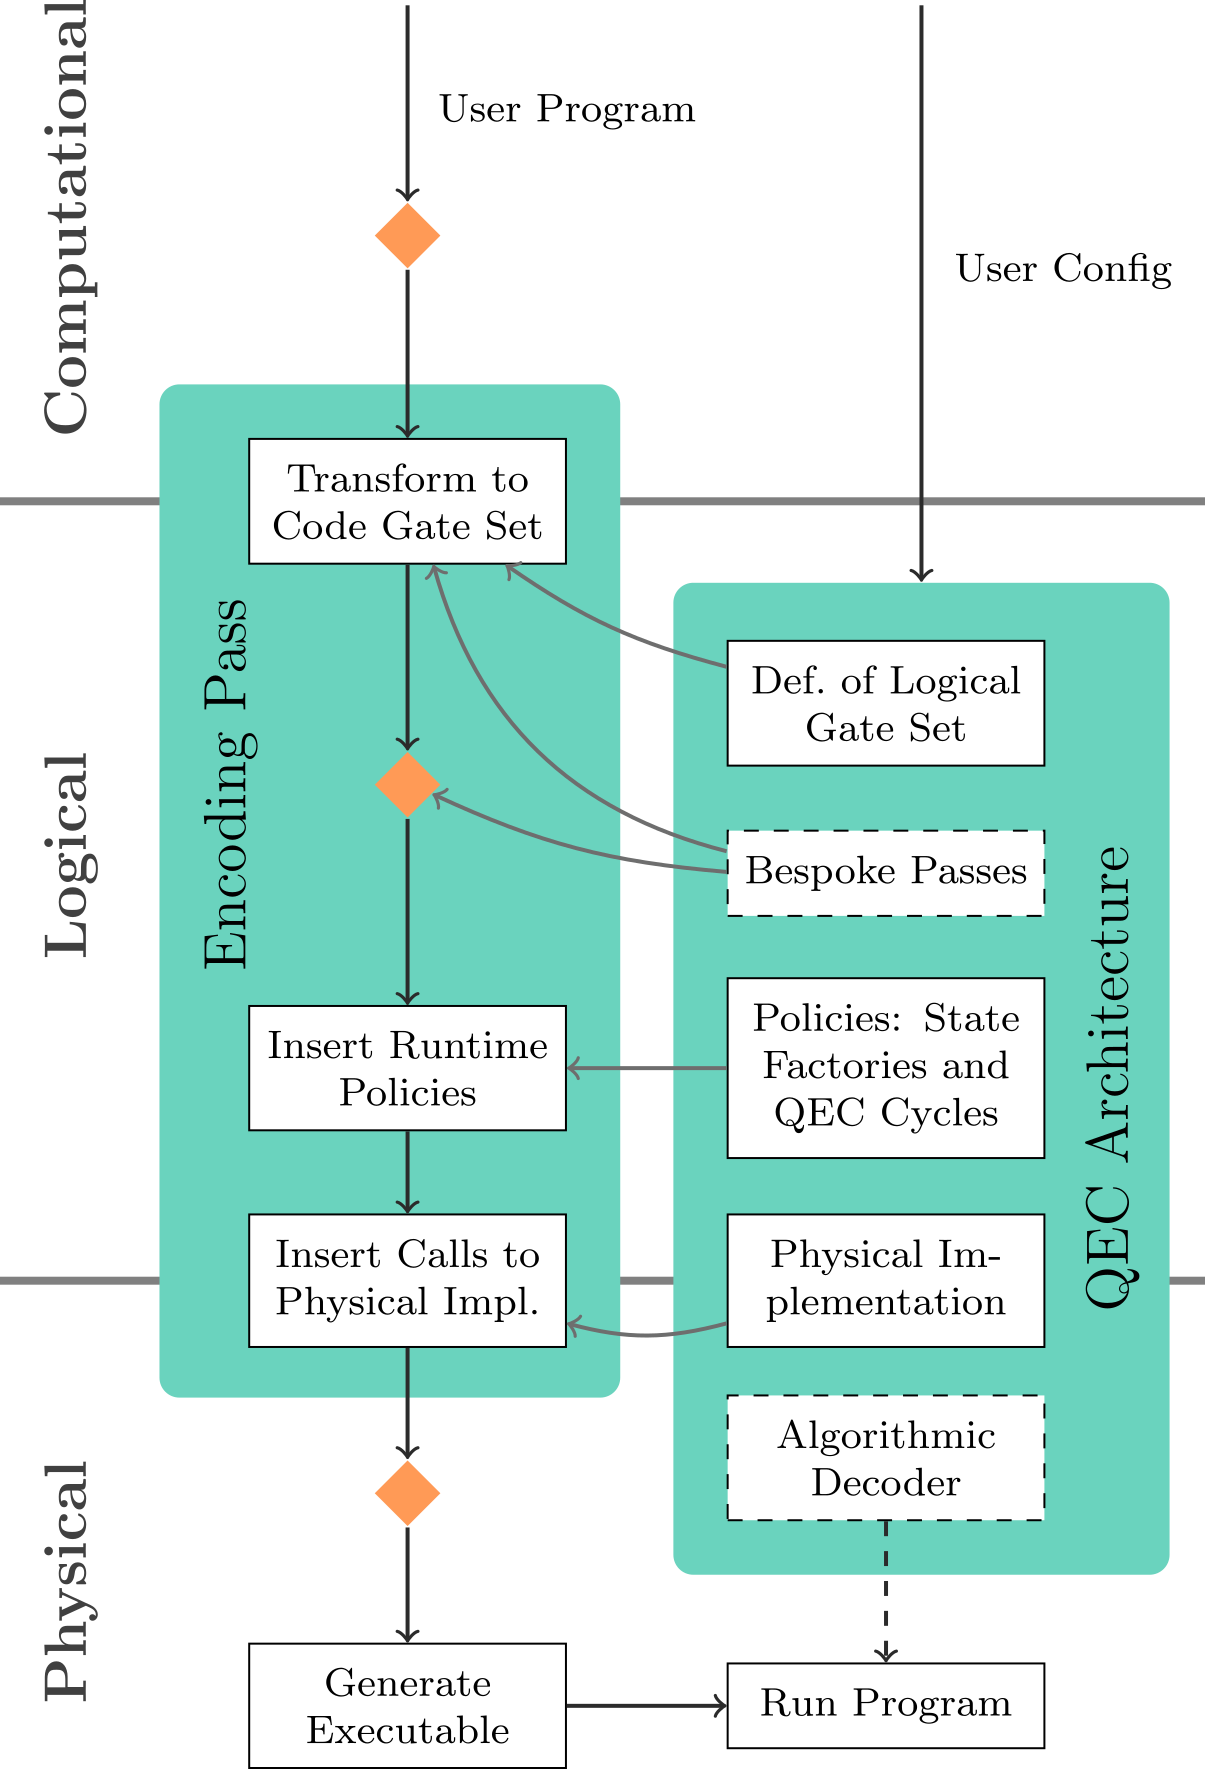
As fault-tolerant techniques improve, the same high-level programming model can therefore serve as a stable interface between applications and increasingly sophisticated QEC implementations. This approach also makes it possible to evolve the underlying architecture without requiring every application developer to rewrite their programs around its implementation details – a crucial benefit as we stay at the forefront of a quickly evolving field.
Available to users today, Guppy FT is an important step toward software designed for the fault-tolerant era. You can use already-perfected codes, like our high-rate quantum error detection code, through Nexus, with more codes coming online as they are developed.
Optimize your work with Guppy Algorithms & Realtime Analytics
We want you doing more than just writing fault tolerant programs – we want to help you write quickly and optimally.
With Guppy Algorithms, you can save needless repetition of work by constructing complex application-level software workflows in an application-agnostic way. Built on Guppy, Guppy Algorithms combines type-safe Guppy primitives with Python builders to help developers construct quantum algorithms out of already optimized building blocks. Guppy Algorithms is also QEC agnostic, enabling users to evolve their fault tolerance approach as the platform grows, without needing to re-write finished programs.
Current highlights include primitives that help you with:
- Trotterisation for Hamiltonian Simulation
- Quantum linear algebra
- Quantum arithmetic
Using Guppy Algorithms is simple. First, you build your abstract (application-specific) algorithm. Then, you simply compose it with Guppy Algorithms: import your desired implementations of circuit sub-components and bring your workflow to life.
"Guppy FT and Guppy Algorithms add a necessary abstraction on top of Guppy’s flexible programming model, so that application development and QEC research can advance in lockstep without either having to bake in assumptions about the other.” - Seyon Sivarajah, Chief Architect of Developer Tools
Soon, we plan to expand Guppy Algorithms to include end-to-end workflows of reusable components.
Of course, a set of optimized building blocks isn’t enough to ensure every program you write is optimal for execution. To that end, Nexus is introducing two tools to help users understand and optimize hardware execution:
- Real-time metrics that provide execution statistics, including gate counts and shot duration.
- ShotPlot, our tool for visualizing gate scheduling, helping users identify idle periods and improve circuit layout.
With these functionalities, you can try new approaches to minimizing gate counts or runtime with real-time feedback that helps you further optimize your result. Taken together, these new tools ensure that Nexus provides an optimal programming experience, from the circuit level to the user experience.
Using Guppy FT to reduce errors on quantum hardware: an end-to-end demonstration on Helios
To demonstrate Guppy FT, the team ran a Steane-encoded quantum algorithm, HHL, on Quantinuum’s Helios quantum computer.
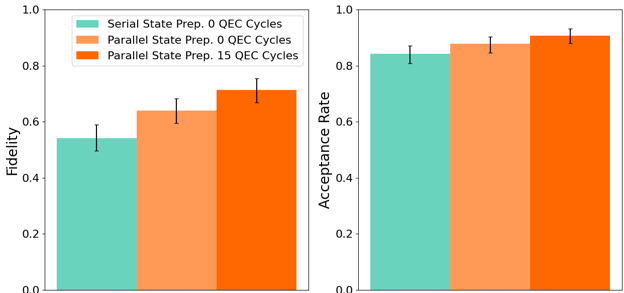
The team compared three versions of the HHL program, with different settings for Guppy FT’s Steane code ([[7, 1, 3]]) encoding, each with 500 shots. The first used no explicit QEC cycles and performed on-demand, sequential state preparation. The second used Guppy FT’s state factories to parallelize state preparation, and the third also applied three QEC cycles to each of the five qubits.
Each shot is comprised of three stages: the HHL program, mid-circuit error detection, and the inverse of the HHL program. Mid-circuit error detection measures the ancilla qubits used by the HHL program, which it ought to disentangle from the data qubits. If an error is detected, the shot is discarded; otherwise, it moves on to the final stage and is marked as accepted. Fidelity is computed as the proportion of accepted shots that the inverse HHL program successfully returns to the initial state.
The results show that both QEC cycles and parallelized state preparation improve performance. QEC cycles actively correct errors while parallelization shortens execution time, reducing the chance of errors. Together, these results demonstrate how Guppy FT can implement fault-tolerant architectures for practical, end-to-end programs running on real quantum hardware.
Deploy Your Hybrid Quantum-Classical Application
The future of quantum computing is more than fault tolerant: it’s hybrid. Close co-ordination between classical and quantum computing resources will be essential for most killer use-cases, with a combination of AI, HPC, and QPU each working on the sub-components they are best suited for.
We’ve been perfecting hybridization for years now, including hybridizing our QPUs with the Fugaku supercomputer at RIKEN. Along the way, we have developed a robust event-based hybrid compute runtime, now available through Nexus. Our updated hybrid compute framework features:
- Multiple storage implementations
- Workflow attempts and restart improvements
- Runtime configuration files
- OTEL tracing and observability
- Workflow cancellation
- SQLite based state management
Quantinuum Nexus: A foundation for what comes next
Nexus brings together the capabilities and infrastructure needed to develop, analyze, run, and manage hybrid quantum-classical programs across the stack. By unifying quantum programming, validation, fault tolerance, compilation, and execution in one place, with interoperability across third-party environments, Nexus is making fault tolerance a practical reality.
Nexus users are already using our quantum processors to explore applications in finance, nuclear physics, particle physics, benchmarking, computational chemistry, and more. As our Nexus roadmap evolves, we plan on deploying ecosystem tools and libraries, as well as an applications marketplace where developers can monetize their work.
“Quantum computers are on the brink of achieving fault tolerance at scale. It's exciting: we are entering terra incognita for what we can compute. The new challenge is putting our high-level quantum algorithms into the right form to successfully run on error-corrected hardware. Developer platforms like Nexus help us bridge that gap between quantum algorithm design and deployment
-José Ignacio Latorre, Director, Centre for Quantum Technologies at the National University of Singapore at the National University of Singapore
By bringing everything together, Nexus is becoming a robust platform in which fault tolerance is a feature, rather than a barrier to entry.
Get ready for the fault tolerant future.
1 Quantum Error Correction
2 Noisy Intermediate Scale Quantum