

How we equip our users to unlock the full potential of H-Series Quantum Computers
Quantinuum is proud to introduce three new tools to help enterprise and academic users to make full use of the world-leading capabilities of the System Model H1 and H2 quantum computers
In a series of recent technical papers, Quantinuum researchers demonstrated the world-leading capabilities of the latest H-Series quantum computers, and the features and tools that make these accessible to our global customers and users.

Our teams used the H-Series quantum computers to directly measure and control non-abelian topological states of matter [1] for the first time, explore new ways to solve combinatorial optimization problems more efficiently [2], simulate molecular systems using logical qubits with error detection [3], probe critical states of matter [4], as well as exhaustively benchmark our very latest system [5].
Part of what makes such rapid technical and scientific progress possible is the effort our teams continually make to develop and improve workflow tools, helping our users to achieve successful results. In this blog post, we will explore the capabilities of three new tools in some detail, discuss their significance, and highlight their impact in recent quantum computing research.
Leakage Detection Gadget in pyTKET
“Leakage” is a quantum error process where a qubit ends up in a state outside the computational subspace and can significantly impact quantum computations. To address this issue, Quantinuum has developed a leakage detection gadget in pyTKET, a python module for interfacing with TKET, our quantum computing toolkit and optimizing compiler. This gadget, presented at the 2022 IEEE International Conference [6], acts as an error detection technique: it detects and excludes results affected by leakage, minimizing its impact on computations. It is also a valuable tool for measuring single-qubit and two-qubit spontaneous emission rates. H-Series users can access this open-source gadget through pyTKET, and an example notebook is available on the pyTKET GitHub repository.
Mid-Circuit Measurement and Qubit Reuse (MCMR) Package
The MCMR package, built as a pyTKET compiler pass, is designed to reduce the number of qubits required for executing many types of quantum algorithms, expanding the scope of what is possible on the current-generation H-Series quantum computers.
As an example, in a recent paper [4], Quantinuum researchers applied this tool to simulate the transverse-field Ising model and used only 20 qubits to simulate a much larger 128 site system (there is more detail below on this work). By measuring qubits early in the circuit, resetting them, and reusing them elsewhere, the package ingests a raw circuit and outputs an optimized circuit that requires fewer quantum resources. Previously, a scientific paper [7] and blog post on MCMR were published highlighting its benefits and applications. H-Series customers can download this package via the Quantinuum user portal.
Quantinuum H2-1 Emulator Release
To enable efficient use of Quantinuum’s 2nd generation processor, the System Model H2, Quantinuum has released the H2-1 emulator to give users greater flexibility with noise-informed state vector emulation. This emulator uses the NVIDIA's cuQuantum SDK to accelerate quantum computing simulation workflows, nearly approaching the limit of full state emulation on conventional classical hardware. The emulator is a faithful representation of the QPU it emulates. This is accomplished by not only using realistic noise models and noise parameters, but also by sharing the same software stack between the QPU and the emulator up until the job is either routed to the QPU or the classical computing processors. Most notable is that the emulator and the QPU use the same compiler allowing subtle and time-dependent errors to be appropriately represented. The H2-1 emulator was initially released as a beta product alongside the System Model H2 quantum computer at launch. It runs on a GPU backend and an upgraded global framework now offering features such as job chunking, incremental resource distribution, mid-execution job cancellation, and partial result return. Detailed information about the emulator can be found in the H2 emulator product datasheet on the Quantinuum website. H-Series customers with an H2 subscription can access the H2-1 emulator via an API or the Microsoft Azure platform.
Enabling Recent Works
Quantinuum's new enabling tools have already demonstrated their efficacy and value in recent quantum computing research, playing a vital role in advancing the field and achieving groundbreaking results. Let's expand on some notable recent examples.
All works presented here benefited from having access to our H-Series emulators; of these two significant demonstrations were the “Creation of Non-Abelian Topological Order and Anyons on a Trapped-Ion Processor” [1] and “Demonstration of improved 1-layer QAOA with Instantaneous Quantum Polynomial” [2]. These demonstrations involved extensive testing, debugging, and experiment design, for which the versatility of the H2-1 emulator proved invaluable, providing initial performance benchmarks in a realistic noisy environment. Researchers relied on the emulator's results to gauge algorithmic performance and make necessary adjustments. By leveraging the emulator's capabilities, researchers were able to accelerate their progress.
The MCMR package was extensively used in benchmarking the System Model H2 quantum computer’s world-leading capabilities [5]. Two application-level benchmarks performed in this work, approximating the solution to a MaxCut combinatorics problem using the quantum approximate optimization algorithm (QAOA) and accurately simulating a quantum dynamics model using a holographic quantum dynamics (HoloQUADS) algorithm, would have been too large to encode on H2's 32 qubits without the MCMR package. Further illustrating the overall value of these tools, in the HoloQUADS benchmark, there is a "bond qubit" that is particularly susceptible to errors due to leakage. The leakage detection gadget was used on this "bond qubit" at the end of the circuit, and any shots with a detected leakage error were discarded. The leakage detection gadget was also used to obtain the rate of leakage error per single-qubit and two-qubit gates, two component-level benchmarks.
In another scientific work [4], the MCMR compilation tool proved instrumental to simulating a transverse-field Ising model on 128 sites, using 20 qubits. With the MCMR package and by leveraging a state-of-the-art classical tensor-network ansatz expressed as a quantum circuit, the Quantinuum team was able to express the highly entangled ground state of the critical Ising model. The team showed that with H1-1's 20 qubits, the properties of this state could be measured on a 128-site system with very high fidelity, enabling a quantitatively accurate extraction of some critical properties of the model.
Key Takeaways
At Quantinuum, we are entirely devoted to producing a quantum hardware, middleware and software stack that leads the world on the most important benchmarks and includes features and tools that provide breakthrough benefit to our growing base of users. In today's NISQ hardware, "benefit" usually takes the form of getting the most performance out of today’s hardware, continually pushing what is considered to be possible. In this blog we describe two examples: error detection and discard using the “leakage detection gadget” and an automated method for circuit optimization for qubit reuse. “Benefit” can also take other forms, such as productivity. Our emulator brings many benefits to our users, but one that resonates the most is productivity. Being a faithful representation of our QPU performance, the emulator is an accessible tool which users have at their disposal to develop and test new, innovative algorithms. The tools and features Quantinuum releases are driven by users’ feedback; whether you are new to H-Series or a seasoned user, please reach-out and let us know how we can help bring benefit to your research and use case.
Footnotes:
[1] Mohsin Iqbal et al., Creation of Non-Abelian Topological Order and Anyons on a Trapped-Ion Processor (2023), arXiv:2305.03766 [quant-ph]
[2] Sebastian Leontica and David Amaro, Exploring the neighborhood of 1-layer QAOA with Instantaneous Quantum Polynomial circuits (2022), arXiv:2210.05526 [quant-ph]
[3] Kentaro Yamamoto, Samuel Duffield, Yuta Kikuchi, and David Muñoz Ramo, Demonstrating Bayesian Quantum Phase Estimation with Quantum Error Detection (2023), arXiv:2306.16608 [quant-ph]
[4] Reza Haghshenas, et al., Probing critical states of matter on a digital quantum computer (2023),
arXiv:2305.01650 [quant-ph]
[5] S. A. Moses, et al., A Race Track Trapped-Ion Quantum Processor (2023), arXiv:2305.03828 [quant-ph]
[6] K. Mayer, Mitigating qubit leakage errors in quantum circuits with gadgets and post-selection, 2022 IEEE International Conference on Quantum Computing and Engineering (QCE), Broomfield, CO, USA, (2022), pp. 809-809, doi: 10.1109/QCE53715.2022.00126.
[7] Matthew DeCross, Eli Chertkov, Megan Kohagen, and Michael Foss-Feig, Qubit-reuse compilation with mid-circuit measurement and reset (2022), arXiv:2210.08039 [quant-ph]
About Quantinuum
Quantinuum, the world’s largest integrated quantum company, pioneers powerful quantum computers and advanced software solutions. Quantinuum’s technology drives breakthroughs in materials discovery, cybersecurity, and next-gen quantum AI. With over 500 employees, including 370+ scientists and engineers, Quantinuum leads the quantum computing revolution across continents.
For years, the quantum landscape has been crowded with headline hype, speculative roadmaps, and vanity qubit counts.
While that noise hasn't completely disappeared, Quantum World Congress 2026 proved that the market's tolerance for hype is rapidly wearing thin. While benchmark simulations and roadmap announcements still generate headlines, the real conversation on the ground has shifted toward a far more demanding question: who is actually delivering useful execution today and making meaningful progress toward fault-tolerant quantum computing?
At Quantinuum, our stance has never wavered. Progress is measured by delivering integrated systems that perform useful computation reliably on real hardware and in live enterprise environments. Prove what you can do and publish the results.
What was most encouraging this year at Quantum World Congress was seeing much of the industry increasingly align around that view, with the conversation converging around several priorities in particular.
1. Fault tolerance proven on real hardware is the only credible path to scale
The industry is converging around a shared reality: useful quantum computing will be defined by fault tolerance.
But fault tolerance is not a single metric, a logical-qubit count, or a standalone error-correction demonstration. It requires a complete end-to-end architecture that can detect, correct, and manage errors across every layer of computation, from logical operations to resource-state preparation, and execution of useful algorithms on live hardware.
That is why context matters when evaluating industry announcements.
Demonstrating more logical qubits is not the same as demonstrating fault tolerance. Demonstrating real-time decoding in a simulation is not the same as demonstrating real-time quantum error correction on real hardware. Logical qubits, decoders, syndrome extraction, and resource-state preparation are all necessary ingredients. But proving an individual ingredient in isolation, particularly through simulations or benchmark environments, is fundamentally different from proving that a complete fault-tolerant architecture works on a live quantum computer.
The industry should not confuse progress on individual building blocks with proof of a scalable fault-tolerant system. The real test is whether all these capabilities work together to improve computational performance beyond the physical layer and in a way that can scale.
This is exactly what Quantinuum's Helix architecture is designed to do.
Running on our Helios system, Helix integrates the full stack required for fault-tolerant quantum computing and has already delivered world-class results on live commercial hardware. Helios achieves physical two-qubit gate error rates of 8×10⁻⁴, while Helix has demonstrated a logical compute error rate of 2.8×10⁻⁴, representing a 4.28× improvement over the physical Clifford gate error rate without post-selection, meaning no cherry-picked results.
Just as importantly, Helix improves efficiency as well as reliability. Through adaptive syndrome extraction, it reduces physical gate requirements by 33% and wall-clock execution time by 23%. Today, the architecture is already supporting full computations using 64 error-detected logical qubits with better-than-physical performance and a highly efficient 1:1.5 encoding rate.
These results matter because they demonstrate more than isolated milestones. They show that a scalable fault-tolerant architecture is operating on real hardware today and delivering measurable improvements in computational reliability. As physical systems grow, Helix provides the framework that enables additional scale to translate into increasingly reliable computation.
The path to fault tolerance will continue to evolve. New codes, encoding approaches, and implementation techniques will emerge over time. What remains constant is the need for an architecture capable of orchestrating those innovations into a practical, scalable system. We believe Helix is well positioned to serve as that architecture.
2. The industry must measure performance with useful, standardized metrics
Customers cannot make informed buying decisions if every vendor continues to grade their own homework. Standardized benchmarks are critical because they shift the conversation from theoretical promises to actual, measurable usefulness.
While earlier benchmarks like Quantum Volume were helpful for NISQ-era systems, they don’t keep pace as fault-tolerant systems scale beyond classical simulation limits. That is why Quantinuum is helping drive industry alignment around QUOPS, developed by Sandia National Laboratories with input from NVIDIA and Quantinuum.
QUOPS measures true computational capability by evaluating both computational Size (QUOPS) and Speed (QUOPS/sec). It’s the difference between rating an engine by theoretical horsepower versus measuring how fast and far a vehicle can drive on an actual track.
Most importantly, QUOPS evaluates the capability delivered by the complete computing stack. As the industry moves toward fault-tolerant systems, useful benchmarks must measure the performance of the entire architecture rather than individual subsystems. They must remain transparent as workloads scale, allowing enterprises to clearly evaluate the real-world utility of a system for their specific problem sets.
3. The industrial manufacturing race is on
Proving a fault-tolerant concept on a laboratory bench is only the first step. The transition to utility-scale computing is fundamentally an engineering, supply chain, and manufacturing race.
Our roadmap clearly defines how we scale from a single chip with a 2D-grid layout to larger multi-chip packages. Rather than reinventing the wheel, we are leveraging proven semiconductor manufacturing techniques that built the modern microelectronics industry. We have backed this architecture with a world-class industrial ecosystem, partnering with commercial foundries and component leaders.
The companies that win the next phase of quantum computing will not simply invent breakthrough technologies. They will demonstrate the ability to manufacture, deploy, and scale them reliably.
4. Growing the ecosystem requires a powerful developer platform built for the fault-tolerant era
A high-performing QPU is only part of the equation. You also need the software layer required to run it. For quantum to succeed, it must integrate into the workflows developers and enterprise researchers are already using today.
Nexus is our developer platform designed to be the purpose-built enterprise integration layer, designed from the ground up to squeeze maximum power and accuracy out of Quantinuum’s architectures. Nexus provides seamless interoperability across native Guppy, NVIDIA CUDA-Q, and Microsoft Q#, directly connecting quantum hardware to classical AI and HPC environments.
This is not an experimental platform. It is already supporting meaningful commercial adoption today.
Adopted by more than 200 organizations, representing approximately 45% growth, and used by more than 1,000 active developers, Nexus has seen annual job submissions increase 10x when comparing August 2024-August 2025 with August 2025-August 2026.
As quantum computing enters the fault-tolerant era, the winning platform will be the one that makes advanced quantum capabilities accessible within the workflows enterprises already depend on.
5. Real progress is measured in live production deployments and real-world research
The future of high-performance computing isn't quantum versus AI or HPC. It is all three working together as a unified compute stack.
But we believe the true test of market leadership isn't a self-funded trial or a desktop simulation that claims hybrid integration. It is putting live hardware into mission-critical operational environments to solve real enterprise problems and advance meaningful science.
That is why we are focused on embedding our quantum systems directly into global computing infrastructure. Through our partnership with Oracle, we expect to bring commercial-scale quantum computing directly into an Oracle Cloud Infrastructure AI data center, with the goal of letting enterprise customers run quantum applications within their existing cloud footprint.
Similarly, our deep, multi-year collaboration with NVIDIA continues to advance the frontiers of hybrid compute: from co-founding the NVAQC center in Boston to physically integrating NVIDIA GPUs into our Helios hardware for real-time error correction, to running live workflows with Pfizer to help accelerate pharmaceutical discovery.
Ultimately, as we scale these capabilities from the system level to the enterprise, we believe quantum computing can serve as the crucial engine to unlock far greater value from classical AI. By integrating QPUs alongside GPUs and supercomputers, we are working to move beyond the limitations of classical compute alone.
This hybrid approach enables enterprises to generate higher-quality quantum training data, build more powerful models, and tackle complex chemistry and materials challenges that remain beyond the reach of classical AI by itself.
Looking Ahead
Quantum World Congress 2026 proved that the market is finally asking the right questions:
- How do we achieve true fault tolerance at scale?
- How do we measure objective computational capability?
- How do we deploy quantum systems to solve real-world enterprise problems?
The conversation is shifting from theoretical possibility to demonstrated capability. From isolated milestones to integrated systems. From simulations to real hardware. That is where meaningful progress happens. And that is where Quantinuum intends to continue to lead.
Forward-Looking Statements:
This blog post contains forward-looking statements within the meaning of the Private Securities Litigation Reform Act of 1995, including statements about expected product capabilities, technology development timelines, planned partnerships and deployments, and anticipated market trends, and expected business metrics and growth rates. These statements are based on current expectations and assumptions and are subject to risks and uncertainties that could cause actual results to differ materially, including risks related to technology development, competitive dynamics, customer adoption, and partnership execution. Forward-looking statements speak only as of the date made, and Quantinuum undertakes no obligation to update them. For a discussion of factors that could affect outcomes, please refer to Quantinuum's public filings.
For enterprise and public sector executives evaluating quantum computing investment
Quantum computing is now a strategic priority for many organizations. It's on track to help solve some of the world's biggest challenges, from drug discovery, to materials science, to optimization problems – all at a scale classical computers simply can't reach. For executives responsible for R&D, technology strategy, or innovation investment, the question is no longer whether quantum computing matters. It's how to approach it wisely.
That's a harder question than it sounds. The quantum computing market is crowded, technical, and moving fast, and most of the guidance available is written for physicists, not for the executives who actually have to make the investment decision. Vendor claims are difficult to compare, pilot programs are easy to get wrong, and the gap between "quantum is exciting" and "quantum is worth investing in this year" isn't always well explained.
Our new guide, A Strategic Guide to Selecting the Right Quantum Computing Solution, is built to close that gap.
What's Inside
The guide is designed to give business and technology leaders a clear, practical path through four essential questions:
- Why quantum computing matters now, and why the window for early strategic advantage is open today
- How to evaluate vendors objectively, using a structured framework rather than marketing claims
- How to design an effective pilot, so early investment produces real, usable evidence
- How to take your first steps with confidence, whether you're just starting to explore or ready to scale
It also includes a glossary of key terms, so readers new to the field aren't left decoding jargon before they can evaluate a single vendor.
Who Should Read It
The guide is written for CTOs, CIOs, CISOs, R&D leaders, and program directors across enterprise and public sector organizations, at any stage of quantum familiarity. Whether your organization hasn't yet started exploring quantum computing, or you already have a program underway and are looking to sharpen your evaluation process, the framework inside is designed to apply.
How to Use It
The evaluation framework at the core of the guide isn't specific to any one vendor; it's designed to be applied to any quantum computing solution you're considering, so you can make an apples-to-apples comparison based on your organization's actual needs. The guide also walks through how Quantinuum maps to that same framework, and what it looks like to work with Quantinuum as a co-development partner, should you want a concrete reference point alongside the general framework.
Start With Confidence, Not Guesswork
Quantum computing is a strategic decision, not just a technical one. The organizations that approach it with a clear framework, rather than reacting to the noise, will be the ones positioned to capture real value as the technology matures.
- QUOPS is a new, architecture-agnostic benchmark designed to measure quantum performance across physical- and logical-qubit systems, using two metrics: Q (computation size) and Ω (operations per second).
- It addresses the limits of traditional metrics like qubit count, gate fidelity, and gate speed by measuring what a quantum system can actually execute successfully—including the effects of error correction, decoding, mitigation, compilation, and other system-level factors.
- QUOPS aims to create a common language for the industry, helping vendors demonstrate progress, enabling buyers and governments to make more objective procurement decisions, and giving researchers a standardized way to track progress toward utility-scale, fault-tolerant quantum computing.
Quantum computing is entering a new era. As systems move from Noisy Intermediate-Scale Quantum (NISQ) toward Fault-Tolerant Application-Scale Quantum (FASQ), traditional metrics like qubit count, gate fidelity, and gate speed are no longer enough to describe what a machine can actually deliver.
Introducing QUOPS
Developed by Sandia National Laboratories, with input from Quantinuum and NVIDIA, QUOPS—the Quantum Universal Operations Performance System—is a common, architecture-agnostic benchmark for measuring quantum performance across both physical- and logical-qubit systems on the path toward quantum utility.
QUOPS can be applied to different architectures, codes, modalities, and levels of fault tolerance. QUOPS runs the same randomized workloads across different computational shapes, measures whether each workload succeeds, identifies the boundary of a system’s capability region, and reports two summary metrics:
- Q: the largest benchmark circuit size that passes the success threshold inside a utility-motivated region. Size is defined as 2*(width)*(depth).
- Ω: the effective operations per second at that point.
The result is a direct measure of how much computation a system can perform and how quickly it can do so. Together, these measurements provide a two-dimensional view of capability while reducing system performance to a common currency: quantum operations.
Why Quantum Computing Needs a New Metric
Component-level metrics remain essential for engineering. Qubit count, two-qubit fidelity, and gate speed can reveal control errors, crosstalk, leakage, connectivity constraints, and other system limitations. But they do not necessarily predict system-level performance.
Fault tolerance makes this gap even larger. Physical operations become logical computation with the addition of logical encoding, syndrome measurement, decoding, logical gate construction, magic-state production, routing, and control. Ultimately, this means that fault tolerance expands the relevant currencies of computation. Code distance, logical fidelity, magic-state throughput, decoding, connectivity, and space-time volume can matter far more for performance than raw qubit count or individual gate speeds.
This creates a growing challenge for buyers, governments, and researchers. As organizations move from experimentation toward larger-scale and potentially on-premise quantum systems, they need to know a simple thing:
What computation can a machine actually execute successfully?
QUOPS addresses that question by measuring the integrated system rather than inferring performance from individual components.
This is particularly important as the field considers workloads requiring roughly 10⁹–10¹² operations on thousands of qubits. Today's measured capabilities are still orders of magnitude smaller; QUOPS turns that gap into a measurable quantity.
QUOPS for Procurement
QUOPS can also provide a practical layer for quantum procurement and planning.
HPC centers need to understand when quantum computing will become useful for real workloads. Customers may have a goal of procuring a system that can, for example, run a trillion error-free operations. Today, answering these questions can require complex resource estimates that depend on hardware modality, QEC code, magic-state factories, decoding, compilation, and other architectural choices.
In both cases, QUOPS provides a simpler system-level reference point: Q describes the size of computation a machine can execute, while Ω describes its effective throughput. Furthermore, because QUOPS is architecture-neutral and includes anti-gaming provisions, it can also help buyers compare competing systems without relying solely on vendor-selected metrics or announcements.
How Quantinuum stacks up
While QUOPS is a new benchmark, it has already been measured on several vendors’ hardware. This marks an important step for our industry: we can now compare vendors directly, assessing their capabilities in a way that flattens the differences introduced by modality and architecture choices.
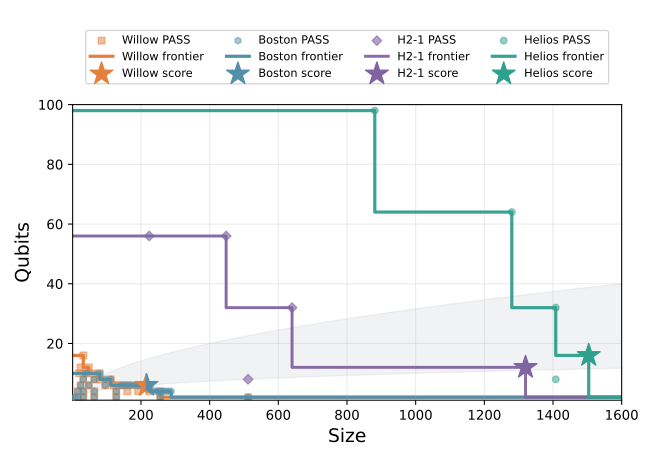
Figure 1. The QUOPS capability region and score for state-of-the-art processors from Quantinuum, Google, and IBM (adapted from Figure 2 of the scientific publication co-authored by Quantinuum, Sandia National Laboratories, and NVIDIA). QUOPS specifies a random circuit construction that can be built for a specified width (number of qubits) and size (number of quantum gates). A set of circuits is run at several width and size points and the average fidelity of those circuits are measured and compared to a predefined threshold. Each labeled point above represents experimental data from QUOPS circuits that passed the threshold with high confidence. The lines are filled capability limits of each machine between the points. The stars indicate the QUOPS score (Q), which is the experimental data point that passes the threshold with maximum size inside the shaded cone of width2 ≤ size ≤ width3.
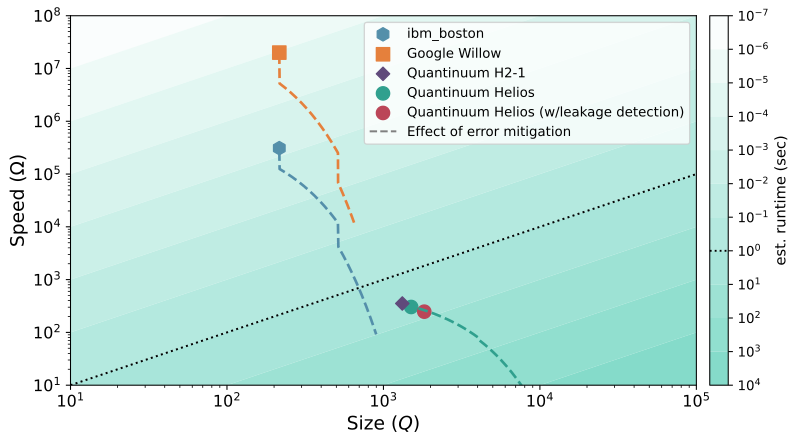
Figure 2. The QUOPS score (Q) vs rate (Ω) for state-of-the-art processors from Quantinuum, Google, and IBM (adapted from Figure 2 of the QUOPS scientific publication co-authored by Quantinuum, Sandia National Laboratories, and NVIDIA). Each point is the maximum QUOPS circuit size that passes the threshold within the specified cone and rate that it was run. The dashed lines indicate the extrapolated effect of error mitigation, which attenuates the rate by including the shot overhead needed for general-purpose error mitigation. The gradient lines show the estimated runtime of a circuit at a given score and rate.
Figures 1 and 2 show how QUOPS quantifies the capability tradeoffs between different systems. Willow and Boston are superconducting systems with very fast gate speeds but limited connectivity, while Helios is a trapped-ion QCCD system with effective all-to-all connectivity but much slower gates. Willow and Boston have smaller capability regions and QUOPS scores but higher QUOPS rates; while Helios reaches larger capability regions and QUOPS scores but lower QUOPS rates. All three systems have the ability to trade speed for larger circuits with error mitigation. This is commonly assumed in the community but is nicely quantified with the QUOPS rate, which accounts for the corresponding sampling overheads of general error mitigation techniques (as shown by the dashed lines in Figure 2).
Building a New Benchmarking Ecosystem
QUOPS will not replace every quantum benchmark. The field will continue to need application-specific suites, component-level measurements, hybrid-HPC benchmarks, and independent verification.
QUOPS instead serves as a common system-level yardstick that can make roadmaps more comparable, procurement more objective, and progress easier to track.
We are calling on vendors to report QUOPS metrics (Q, Ω) and capability regions alongside existing metrics, buyers and agencies to consider QUOPS thresholds in RFPs, and researchers to contribute fault-tolerant architectures and resource estimates.
As quantum computers become fault tolerant, success will no longer be defined simply by how many qubits a machine contains or how low its error rates are.
It will be defined by the computation the machine can deliver.
QUOPS is a step toward measuring that capability—and toward giving the quantum industry a benchmark built for the era ahead.