

Quantinuum Launches the Most Benchmarked Quantum Computer in the World and Publishes All the Data
New H2-1 shows strong performance across 15 benchmarks while expanding to 32 qubits and reaching a new Quantum Volume record of 65,536
Quantinuum’s new H2-1 quantum computer proves that trapped-ion architecture, which is well-known for achieving outstanding qubit quality and gate fidelity, is also built for scale – and Quantinuum’s benchmarking team has the data to prove it.
The bottom line: the new System Model H2 surpasses the H1 in complexity and qubit capacity while maintaining all the capabilities and fidelities of the previous generation – an astounding accomplishment when developing successive generations of quantum systems.
The newest entry in the H-Series is starting off with 32 qubits whereas H1 started with 10. H1 underwent several upgrades, ultimately reaching a 20-qubit capacity, and H2 is poised to pick up the torch and run with it. Staying true to the ultimate goal of increasing performance, H2 does not simply increase the qubit count but has already achieved a higher Quantum Volume than any other quantum computer ever built: 216 or 65,536.
Most importantly for the growing number of industrials and academic research institutions using the H-Series, benchmarking data shows that none of these hardware changes reduced the high-performance levels achieved by the System Model H1. That’s a key challenge in scaling quantum computers – preserving performance while adding qubits. The error rate on the fully connected circuits is comparable to the H1, even with a significant increase in qubits. Indeed, H2 exceeds H1 in multiple performance metrics: single-qubit gate error, two-qubit gate error, measurement cross talk and SPAM.
Key to the engineering advances made in the second-generation H-Series quantum computer are reductions in the physical resources required per qubit. To get the most out of the quantum charge-coupled device (QCCD) architecture, which the H-Series is built on, the hardware team at Quantinuum introduced a series of component innovations, to eliminate some performance limitations of the first generation in areas such as ion-loading, voltage sources, and delivering high-precision radio signals to control and manipulate ions.
The research paper, “A Race Track Trapped-Ion Quantum Processor,” details all of these engineering advances, and exactly what impacts they have on the computing performance of the machine. The paper includes results from component and system-level benchmarking tests that document the new machine’s capabilities at launch. These benchmarking metrics, combined with the company’s advances in topological qubits, represent a new phase of quantum computing.
Advancing Beyond Classical Simulation
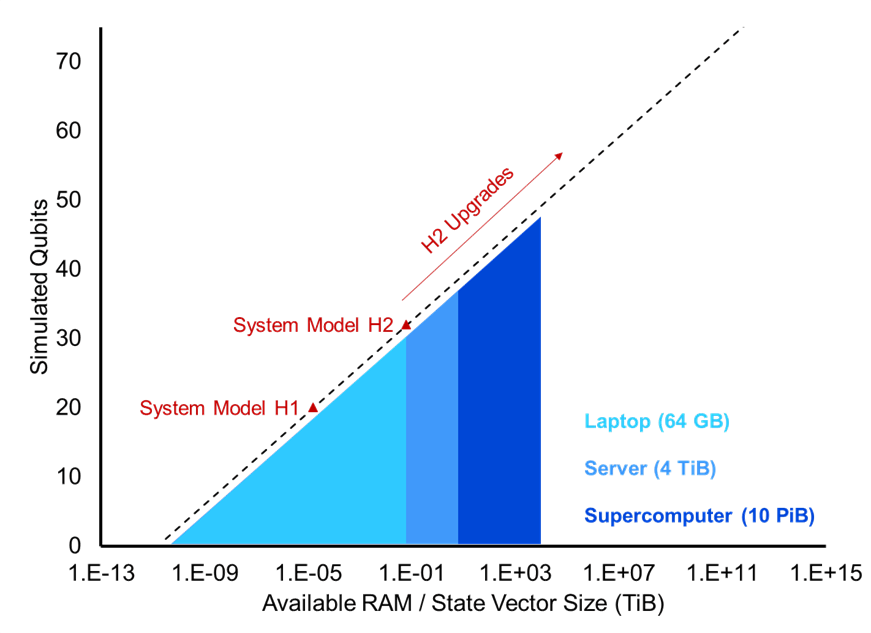
In addition to the expanded capabilities, the new design provides operational efficiencies and a clear growth path.
At launch, H2’s operations can still be emulated classically. However, Quantinuum released H2 at a small percentage of its full capacity. This new machine has the ability to upgrade to more qubits and gate zones, pushing it past the level where classical computers can hope to keep up.
Increased Efficiency in New Trap Design
This new generation quantum processor represents the first major trap upgrade in the H-Series. One of the most significant changes is the new oval (or racetrack) shape of the ion trap itself, which allows for a more efficient use of space and electrical control signals.
One key engineering challenge presented by this new design was the ability to route signals beneath the top metal layer of the trap. The hardware team addressed this by using radiofrequency (RF) tunnels. These tunnels allow inner and outer voltage electrodes to be implemented without being directly connected on the top surface of the trap, which is the key to making truly two-dimensional traps that will greatly increase the computational speed of these machines.
The new trap also features voltage “broadcasting,” which saves control signals by tying multiple DC electrodes within the trap to the same external signal. This is accomplished in “conveyor belt” regions on each side of the trap where ions are stored, improving electrode control efficiency by requiring only three voltage signals for 20 wells on each side of the trap.
The other significant component of H2 is the Magneto Optical Trap (MOT) which replaces the effusive atomic oven that H1 used. The MOT reduces the startup time for H2 by cooling the neutral atoms before shooting them at the trap, which will be crucial for very large machines that use large numbers of qubits.
Industry-leading Results from 15 Benchmarking Tests
Quantinuum has always valued transparency and supported its performance claims with publicly available data.
To quantify the impact of these hardware and design improvements, Quantinuum ran 15 tests that measured component operations, overall system performance and application performance. The complete results from the tests are included in the new research paper.
The hardware team ran four system-level benchmark tests that included more complex, multi-qubit circuits to give a broader picture of overall performance. These tests were:
- Mirror benchmarking: A scalable way to benchmark arbitrary quantum circuits.
- Quantum volume: A popular system-level test with a well-established construction that is comparable across gate-based quantum computers.
- Random circuit sampling: A computational task of sampling the output distributions of random quantum circuits.
- Entanglement certification in Greenberger-Horne-Zeilinger (GHZ) states: A demanding test of qubit coherence that is widely measured and reported across a variety of quantum hardware.
H2 showed state-of-the-art performance on each of these system-level tests, but the results of the GHZ test were particularly impressive. The verification of the globally entangled GHZ state requires a relatively high fidelity, which becomes harder and harder to achieve with larger numbers of qubits.
With H2’s 32 qubits and precision control of the environment in the ion trap, Quantinuum researchers were able to achieve an entangled state of 32 qubits with a fidelity of 82.0(7)%, setting a new world record.
In addition to the system level tests, the Quantinuum hardware team ran these component benchmark tests:
- SPAM experiment
- Single-qubit gate randomized benchmarking
- Two-qubit gate randomized benchmarking
- Two-qubit SU gate randomized benchmarking RB
- Two-qubit parameterized gate randomized benchmarking
- Measurement/reset crosstalk benchmarking
- Interleaved transport randomized benchmarking
The paper includes results from those tests as well as results from these application benchmarks:
- Hamiltonian simulation
- Quantum Approximate Optimization Algorithm
- Error correction: repetition code
- Holographic quantum dynamics simulation
About Quantinuum
Quantinuum, the world’s largest integrated quantum company, pioneers powerful quantum computers and advanced software solutions. Quantinuum’s technology drives breakthroughs in materials discovery, cybersecurity, and next-gen quantum AI. With over 500 employees, including 370+ scientists and engineers, Quantinuum leads the quantum computing revolution across continents.
From Oracle's Quantum AI Compute beta program to upcoming Helios installation milestones and Oracle AI World, our partnership continues to gain momentum.
When Quantinuum and Oracle announced a strategic partnership earlier this year, the goal was not simply to deploy a quantum computer in the cloud. It was to create a practical path for bringing quantum computing into the enterprise environments where AI, data, and high-performance computing (HPC) already come together.
By combining Oracle Cloud Infrastructure (OCI)'s AI, data, and cloud capabilities with Helios, Quantinuum's most advanced quantum computer, we're helping lay the foundation for hybrid quantum AI computing at enterprise scale. The partnership reflects our belief that some of the most valuable future applications will emerge when quantum computing, AI and classical HPC work together to tackle problems that remain difficult to solve today.
Oracle Opens Early Access for Quantum AI Compute
That vision is now being put into practice. This month, Oracle launched the OCI Quantum AI Compute Beta Program, giving select organizations an opportunity to begin evaluating how quantum computing fits into existing workflows and computational challenges.
Through the program, approved participants will gain cloud-based access to Helios, the world's most accurate commercial quantum computer, alongside OCI's GPU and HPC infrastructure. For organizations exploring quantum computing, this creates a practical starting point: access to industry-leading hardware within an enterprise cloud environment, without the need to build specialized infrastructure of their own.
The goal is to help organizations understand where hybrid quantum AI workflows may create value across areas such as drug discovery, materials science, energy, financial modeling, and optimization.
For many organizations, the starting point is not quantum technology itself. It's a business or research problem. Where are today's approaches reaching meaningful limits? Which workloads consume disproportionate resources? And where could a new computational capability create an advantage?
Organizations interested in participating can apply through Oracle's OCI Preview Programs portal. Oracle will review applications and select participants based on eligibility, capacity and program requirements.
Quantinuum and Oracle Leadership Takes the Stage at Oracle AI World
The opportunity for hybrid quantum-AI computing will be a major topic at Oracle AI World 2026.
In a main stage session, "Powering the Next Era of Enterprise AI," Larry Stack, Chief Commercial Officer at Quantinuum, will join Mahesh Thiagarajan, Executive Vice President and Head of Oracle Cloud Infrastructure, to discuss how quantum computing, AI and classical HPC can work together to address some of the world's most computationally demanding challenges.
The discussion will focus on a core question many organizations are asking: where should they start? Rather than leading with technology, the conversation will explore how organizations can identify high-value problems, establish today's performance baseline, and evaluate where quantum computing ultimately provides an advantage.
Later in the day, Quantinuum and Oracle experts will take a deeper look at how bringing Helios into OCI provides managed access to quantum computing natively within an enterprise cloud environment to support hybrid quantum-AI workflows.
Building Momentum Toward Hybrid Quantum-AI Computing
The collaboration between Quantinuum and Oracle continues to progress from vision to execution.
With Helios advancing toward installation, Oracle's Quantum AI Compute program now open for early access, and enterprise interest growing around hybrid computing, the pieces are coming together. Organizations now have a practical way to begin exploring quantum computing through cloud-based access to Helios alongside AI, HPC, and existing enterprise workflows.
We look forward to continuing the conversation at Oracle AI World 2026 and working with customers who want to better understand where hybrid quantum-AI computing can create real-world value.
We're excited to continue that conversation at Oracle AI World 2026 and to help customers begin exploring what's possible through the OCI Quantum AI Compute Beta Program.
By: David Hayes, Sr. Director of Computational Design and Integrated Software
Two recent announcements from Quantinuum and Google mark important progress toward fault-tolerant quantum computing.
Because both announcements focus on reducing errors, it may be tempting to compare the numbers directly. But these results are not the same. They measure different parts of the fault-tolerance challenge and answer fundamentally different technical questions.
This week, we reported a world-record error-correction result, using our error-correction architecture on Helios to deliver a logical fidelity of 99.9995%, equivalent to just five errors per million operations and representing a 100x reduction in errors compared to the best published result across any other modality—reported by Google Quantum AI in 2024.
Last week, Google reported a 99.99% magic-state fidelity result using a new cultivation technique, citing a 40x reduction in errors.
As fault-tolerant quantum computing matures, understanding what is being measured becomes just as important as understanding the headline number itself. Google's work measured the fidelity of a resource used in certain fault-tolerant operations. Our work measured the fidelity of the logical computation that consumes those resources.
Across the published results, Quantinuum demonstrates state-of-the-art performance in fault-tolerance, combining record logical computational fidelity with substantial advantages in resource efficiency. Understanding starts with examining what each study measured, what it achieved, and the resources it required.
Quantinuum's World-Record Result: Measuring the Accuracy of a Logical Computation
This week’s result measured how accurately an error-corrected logical quantum system can execute a computation.
To achieve the result, we used a well-known “color code” within our error-correction architecture. The error rate is 10 times lower than Quantinuum’s own world record achieved last month and 100 times lower than the best published result across all other hardware modalities—the 2024 Google result.
The study also demonstrated that logical errors fell exponentially as code distance increased. Code distance is a key measure of how quantum information can be protected as an error-correction system scales.
Each increase tested in the study reduced the remaining logical error rate by a record factor of 12, demonstrating exponentially effective error suppression as the code grows, a critical capability for scalable fault-tolerant quantum computing.
Together, these results demonstrate how Quantinuum's highly accurate trapped-ion hardware and flexible logical architecture can drive rapid gains in computational accuracy. They also show that fault-tolerant performance can be achieved with substantially fewer physical qubits than competing modalities.
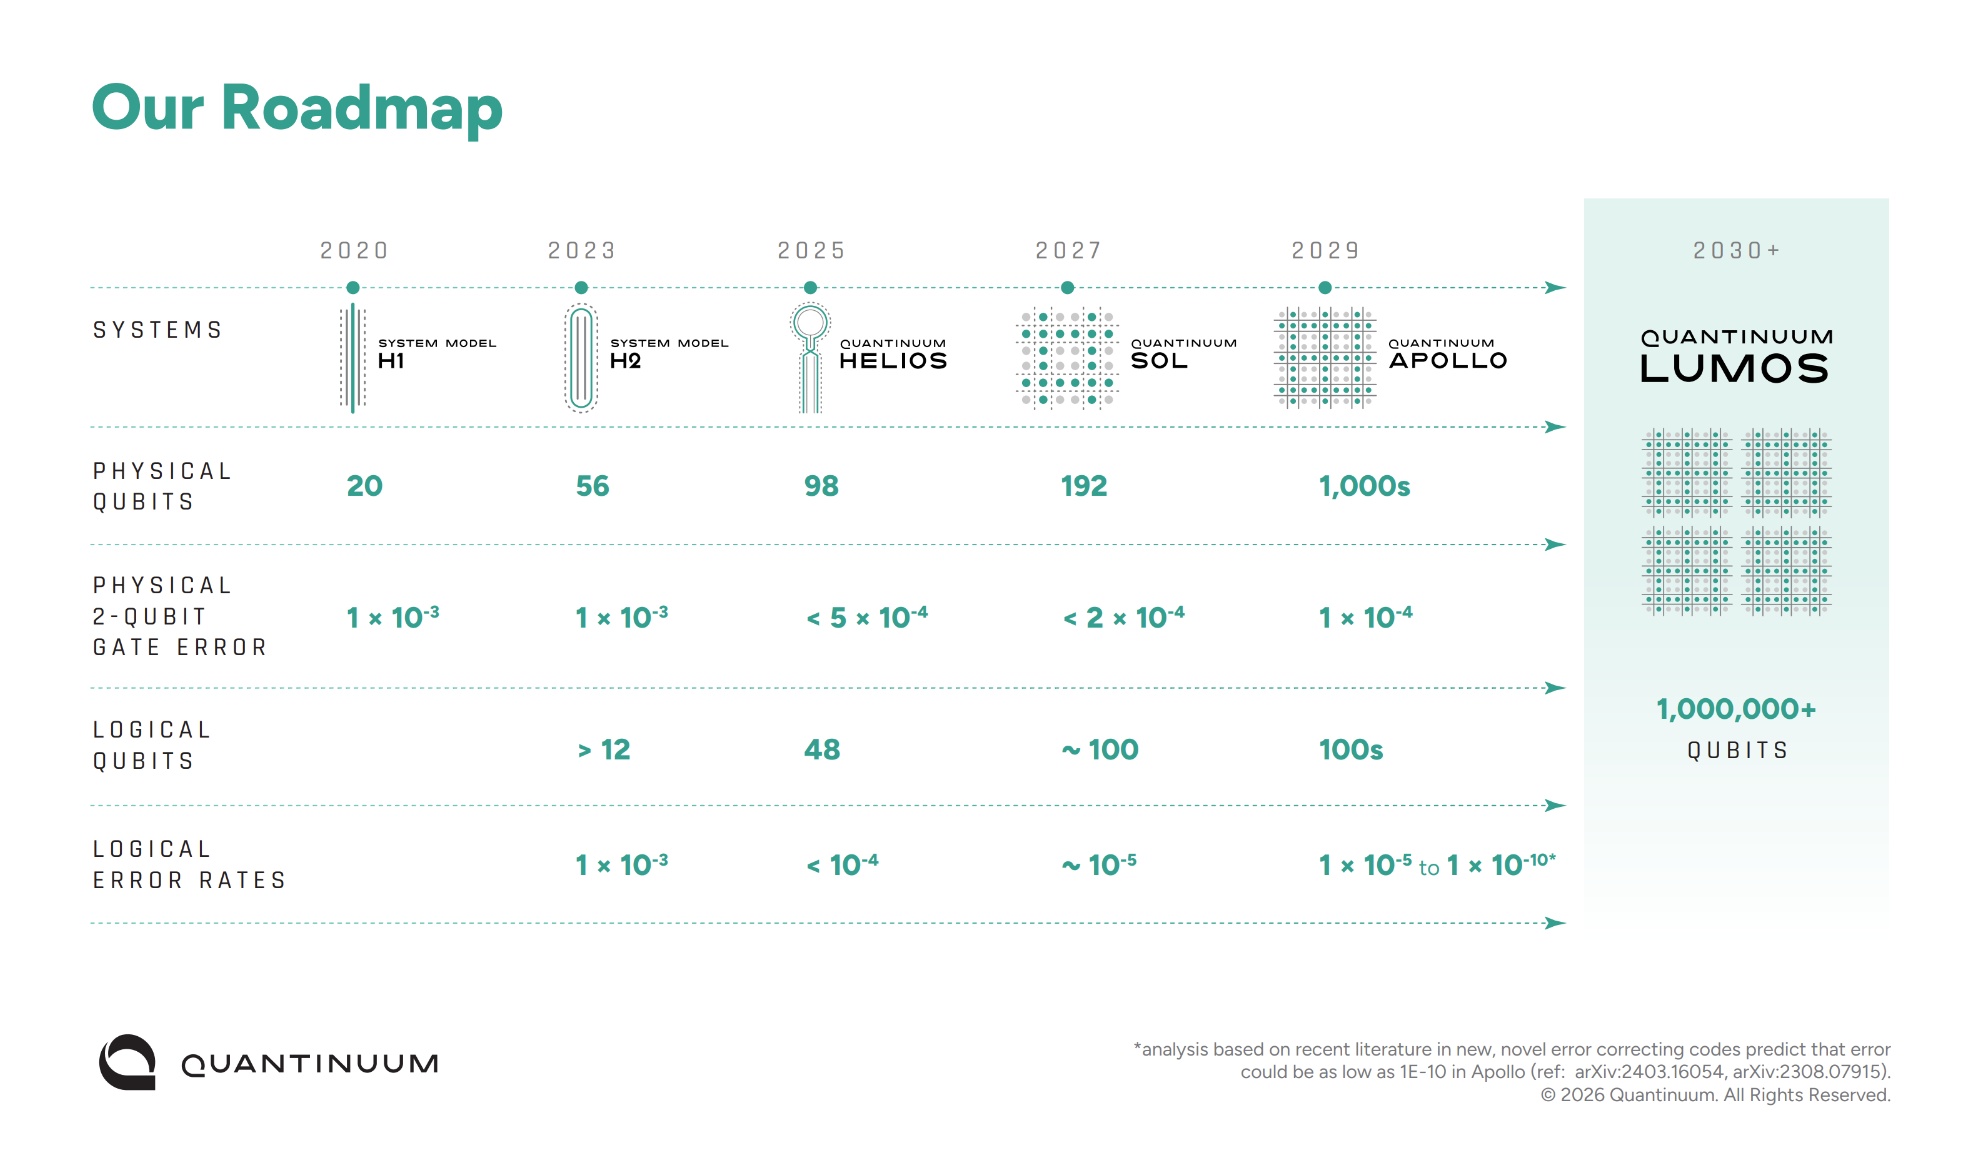
The result places Quantinuum within the target logical-performance range required for Apollo, our planned universal fault-tolerant quantum computer targeted for 2029.
Google's Result: Advancing Magic-State Preparation
Google's latest paper focused on a different aspect of fault tolerance: the preparation of high-fidelity magic states.
Magic states are an important resource required for certain operations in a fault-tolerant quantum computer. Generating them efficiently is widely recognized as one of the key engineering challenges facing large-scale fault-tolerant systems, particularly for certain modalities.
Google's work introduced a new approach known as cultivation, designed to improve the fidelity of magic-state preparation while reducing the resources required to produce those states. The study demonstrated a magic-state fidelity of 99.99% using a protocol that retained approximately 8% of attempts while discarding the remainder. This post-selection process was a key contributor to the reported 40x reduction in error rate.
The study did not measure the fidelity of a larger logical computation that incorporates those magic states into an end-to-end algorithm. Instead, it focused specifically on the creation and refinement of the resource itself.
That distinction is important because preparing a high-fidelity resource and demonstrating the performance of a logical computation are different milestones on the path to fault tolerance.
Directly Comparing Quantinuum and Google’s Magic-State Results
Quantinuum's latest logical computation result should not be compared directly with Google's latest magic-state result. It should be compared against the distance scaling result published by Google in 2024.
That said, we have published studies measuring an analogous magic-state capability examined in Google’s latest work.
In a 2025 study, we achieved 99.993% magic-state fidelity with an 85% retention rate, compared with the 99.99% fidelity and approximately 8% retention reported in Google’s latest work. Our result also required fewer physical qubits and fewer operational steps, resulting in significantly lower space-time overhead.
That combination of smaller qubit and operational steps footprint, along with substantially higher retention means fewer resources are consumed preparing each usable magic state.
As fault-tolerant systems scale, those efficiency advantages become increasingly important because they directly affect the amount of hardware required to perform useful computations.
The Bigger Picture
Taken together, these results establish Quantinuum’s leadership in demonstrated fault-tolerant performance: record logical computation fidelity, alongside a directly comparable magic-state result that achieves higher fidelity with substantially lower resource overhead.
That combination—computational accuracy and the efficiency with which it is achieved—is critical to delivering reliable answers to useful problems at a practical scale.
Ultimately, customers do not buy two-qubit gate fidelities or magic states. They buy answers.
Forward-Looking Statements
This blog post contains forward-looking statements within the meaning of the Private Securities Litigation Reform Act of 1995. These include statements about our technology roadmap, our expected logical performance, and the planned timing and capabilities of future systems, including Apollo. Words such as "target," "expect," "plan," and similar expressions identify forward-looking statements. These statements are based on our current expectations and involve risks and uncertainties that could cause actual results to differ materially. Those risks include challenges in developing, manufacturing, and scaling our quantum computing systems. For a discussion of these and other risks, see the "Risk Factors" section of our most recent Quarterly Report on Form 10-Q and our other filings with the SEC, available at ir.quantinuum.com. Forward-looking statements speak only as of the date of this post, and we undertake no obligation to update them except as required by law.
- Record accuracy: Using Quantinuum’s logical error-correction architecture, Helios achieved a logical memory fidelity of 99.9995%—just five uncorrectable errors per million operations—reducing logical memory errors tenfold compared with Quantinuum’s September record and more than 100-fold compared with the superconducting record.
- Errors fall exponentially as protection grows: Each tested increase in code distance reduced logical memory errors by an average factor of 12, and logical gate errors by an average factor of 9, demonstrating the exponential error suppression needed to scale toward longer, more reliable quantum computations.
- A flexible path to fault tolerance: Successive breakthroughs using different codes within the same logical architecture, on the same commercial Helios hardware, demonstrate how accuracy and qubit efficiency can be optimized as Quantinuum advances toward Apollo in 2029.
Recently, we started making the case that the NISQ1 era is coming to an end. At Quantinuum, we’ve already demonstrated numerous QEC codes, all the primitives needed for logical computation, steadily declining logical error rates, and full computations at the logical level.
To truly leave the NISQ era, though, we need to demonstrate a “megaquop” machine – a quantum computer that can run over a million operations error-free. With our latest result, we are on the cusp of this monumental achievement: using Quantinuum’s logical error-correction architecture, Helios achieved a logical memory fidelity of 99.9995%— or a million operations with only 5 uncorrectable errors, a new world record. This logical error rate is ten times lower than our September record and more than 100 times lower than the record achieved on a superconducting system.
Coming after September’s Helix-code demonstration on the same Helios hardware, this result shows how our flexible logical architecture and highly accurate trapped-ion technology support rapid improvements in accuracy.
These results indicate that an Apollo-scale machine could reach the fault-tolerant quantum advantage regime using 30x fewer physical qubits than other leading approaches, reinforcing our path to Apollo, our first universal fault-tolerant quantum computer.
A quantum memory that lasts
At Quantinuum, we don’t have delicate qubits that can only hold their state for milliseconds at a time. We’ve already shown quantum memories lasting over 20 seconds. However, this latest result takes it to a whole new level: we have demonstrated the most robust quantum memory ever recorded.
This latest result was enabled by something scientists call “distance scaling”, a key result in quantum error correction (QEC) theory: the prediction that error rates should be suppressed exponentially as longer distance codes (more physical qubits per logical qubit) are used.
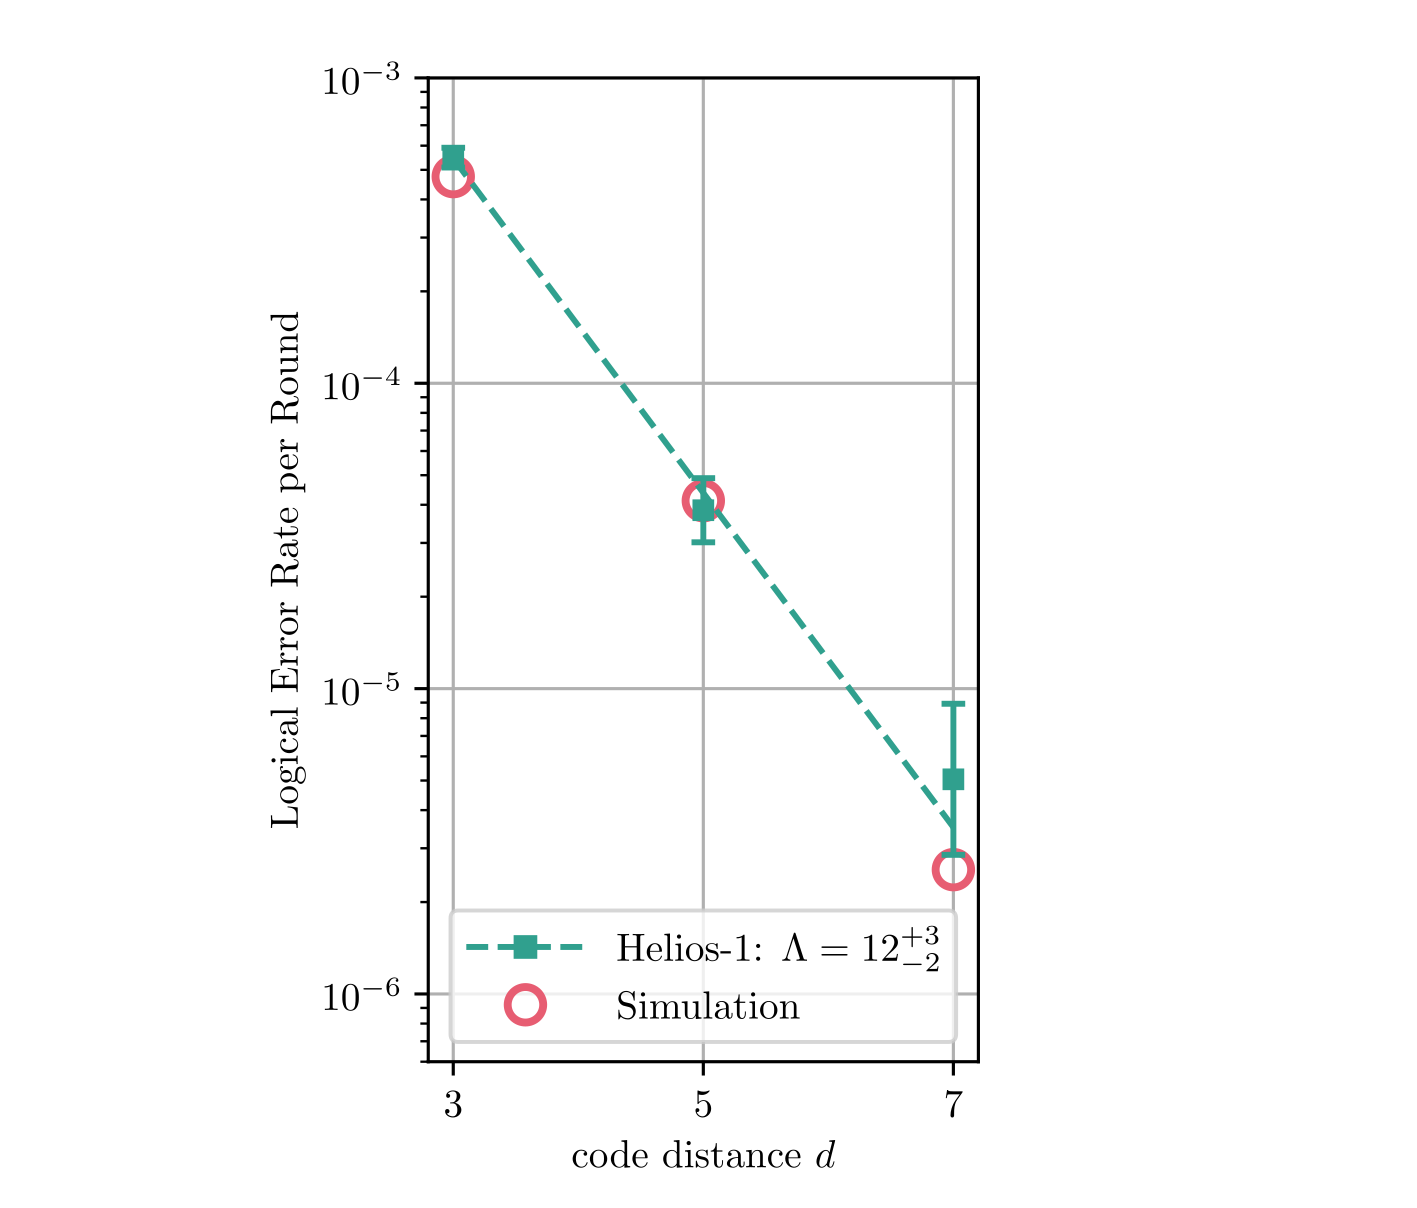
In experiments using color codes of distance 3, 5 and 7, Helios (with code written in Guppy) reduced the logical failure rate by an average factor of 12 each time the code distance increased. At distance 7, the system achieved a logical fidelity of 99.9995% per syndrome-extraction cycle, equivalent to a failure probability of just 5 × 10⁻⁶. This nearly “six nines” result sets a new record for logical accuracy through quantum error correction.
To measure the failure rate of something that rarely fails, you must run it for a long time. This ensures that you get reasonable enough statistics to feel comfortable that your measured value isn’t just a statistical fluctuation (scientists call this 'averaging down’ the uncertainty in your measurement).
When you only get an error 5 times in a million rounds, this often means ‘averaging down’ for a long time to even see an error2.
“We felt a mix of excitement and suspense every time the results came in. When errors are this rare, each one really matters."
- Dr. Adam Reed, Lead Physicist, Commercial Operations
More than a memory: high-fidelity logical gates
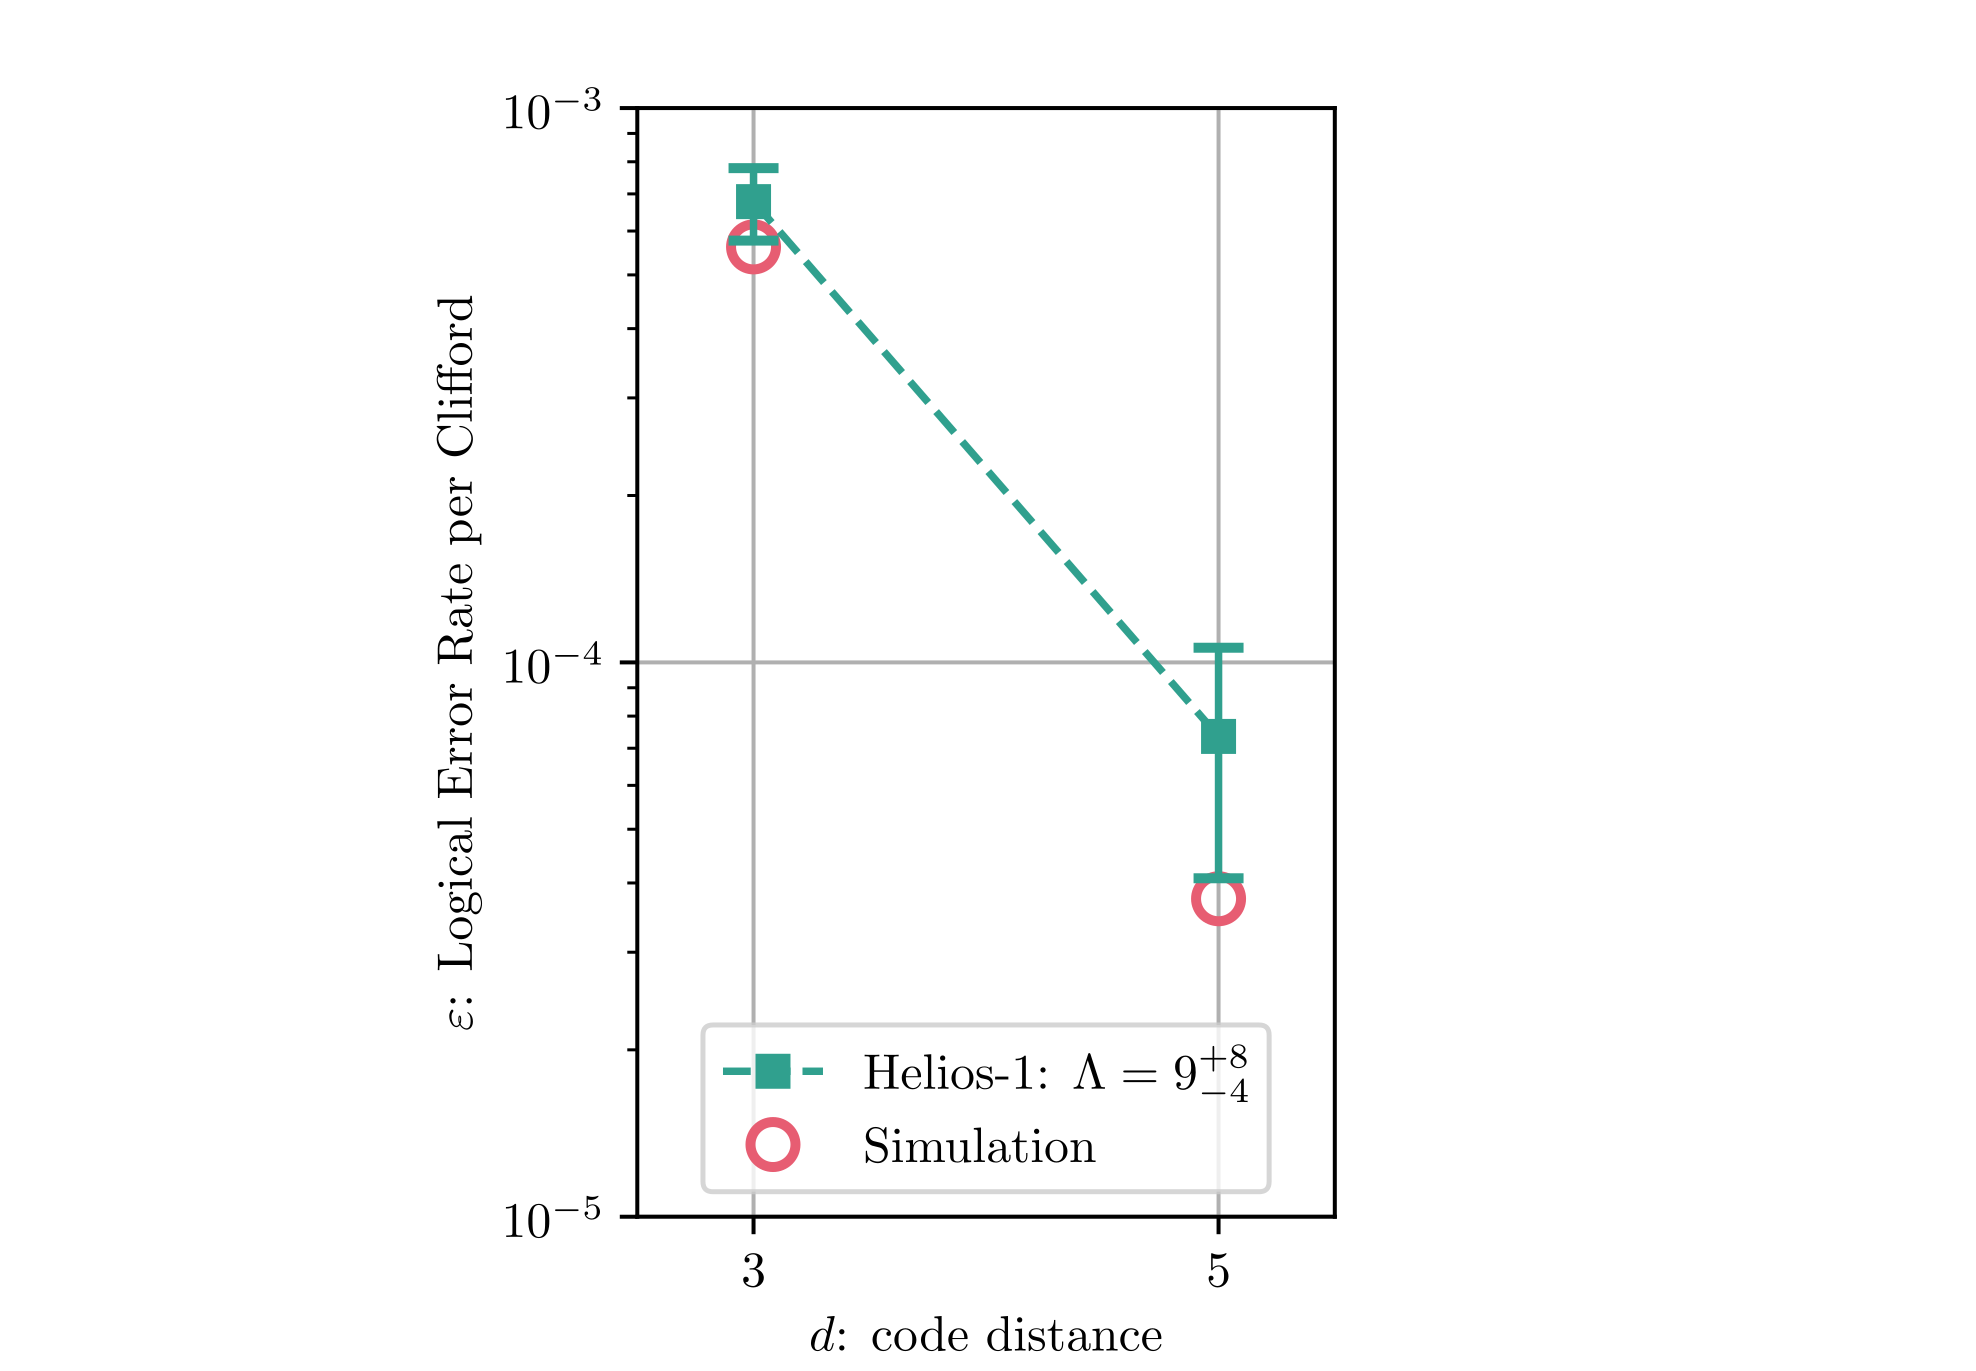
The team also explored logical computation, measuring 2-qubit Clifford gate fidelity at increasing code distance. In this case, the team measured a suppression factor Λ of 9 when stepping the code distance up from 3 to 5, proving again our hardware’s exponential error suppression3.
If one assumes a “Clifford + T” model of universal computation (with T gates teleported via magic state injection), then a fully fault tolerant processor built with this code will have three crucial components:
- Magic state preparation
- Two-qubit Clifford gates
- Syndrome extraction gadgets.
This work demonstrates high accuracy implementation and below threshold scaling of the latter two, and we demonstrated the first in a separate paper (with the same code) back in 2025. Teleporting T gates via magic state injection will require real-time decoding, which we first demonstrated back in 2021 and have been refining ever since – in fact, this work shows that this is viable for near-optimal decoders. There is still work to be done, however: nobody has yet demonstrated below threshold scaling for magic state preparation.
We’ve already put almost everything together in the Helix code. Soon, we will be integrating all these color-code components into increasingly large, reliable computations. Our ability to fully employ multiple codes is a testament to our powerful error correction architecture.
World-record logical fidelities come from world-leading physical fidelities
Distance scaling is great in theory, but it is rarely demonstrated because it only works when the underlying hardware noise falls below a certain threshold. This is known as the “threshold theorem.” Basically, until the physical layer has low enough noise levels, QEC will just add more noise than it takes away.
Helios’ incredible performance – with a ‘suppression rate’ Λ of 12 (for memory) and 9 (for Clifford gates) - is a clear demonstration of our world-leading physical fidelity, which puts us well below the ‘threshold’.
The rate Λ captures the exponential suppression in error rate with increasing code distance4: increasing the code distance once gives an 12x reduction in logical error, increasing the distance twice gives 144x, three times 1728x, and so on. In contrast, a machine with a Λ of 2 gives you a 2x reduction, then a 4x reduction, then 8x, and so on – a much slower gain. The magnitude of Λ is crucial for how well quantum computers can scale, and this is the largest Λ ever measured.
This effect shows up in the best error rates, too. The previous state of the art color-code error rate (at distance 5) was 0.819% per cycle. Helios, in contrast, showed an error rate of 0.0005% with a distance 7 code, a 1,638x improvement5. This massive improvement is due to our excellent physical fidelity, improved scaling behavior, and our ability to go to a longer distance code (in this case, d=7 vs d=5)6.
Comparing at the same code distance, the previous best demonstrated error rate was using a surface code. In this case, the researchers demonstrated an error rate of 0.0772% per cycle with a distance 7 code. In this case, Helios shows a 154x improvement7.
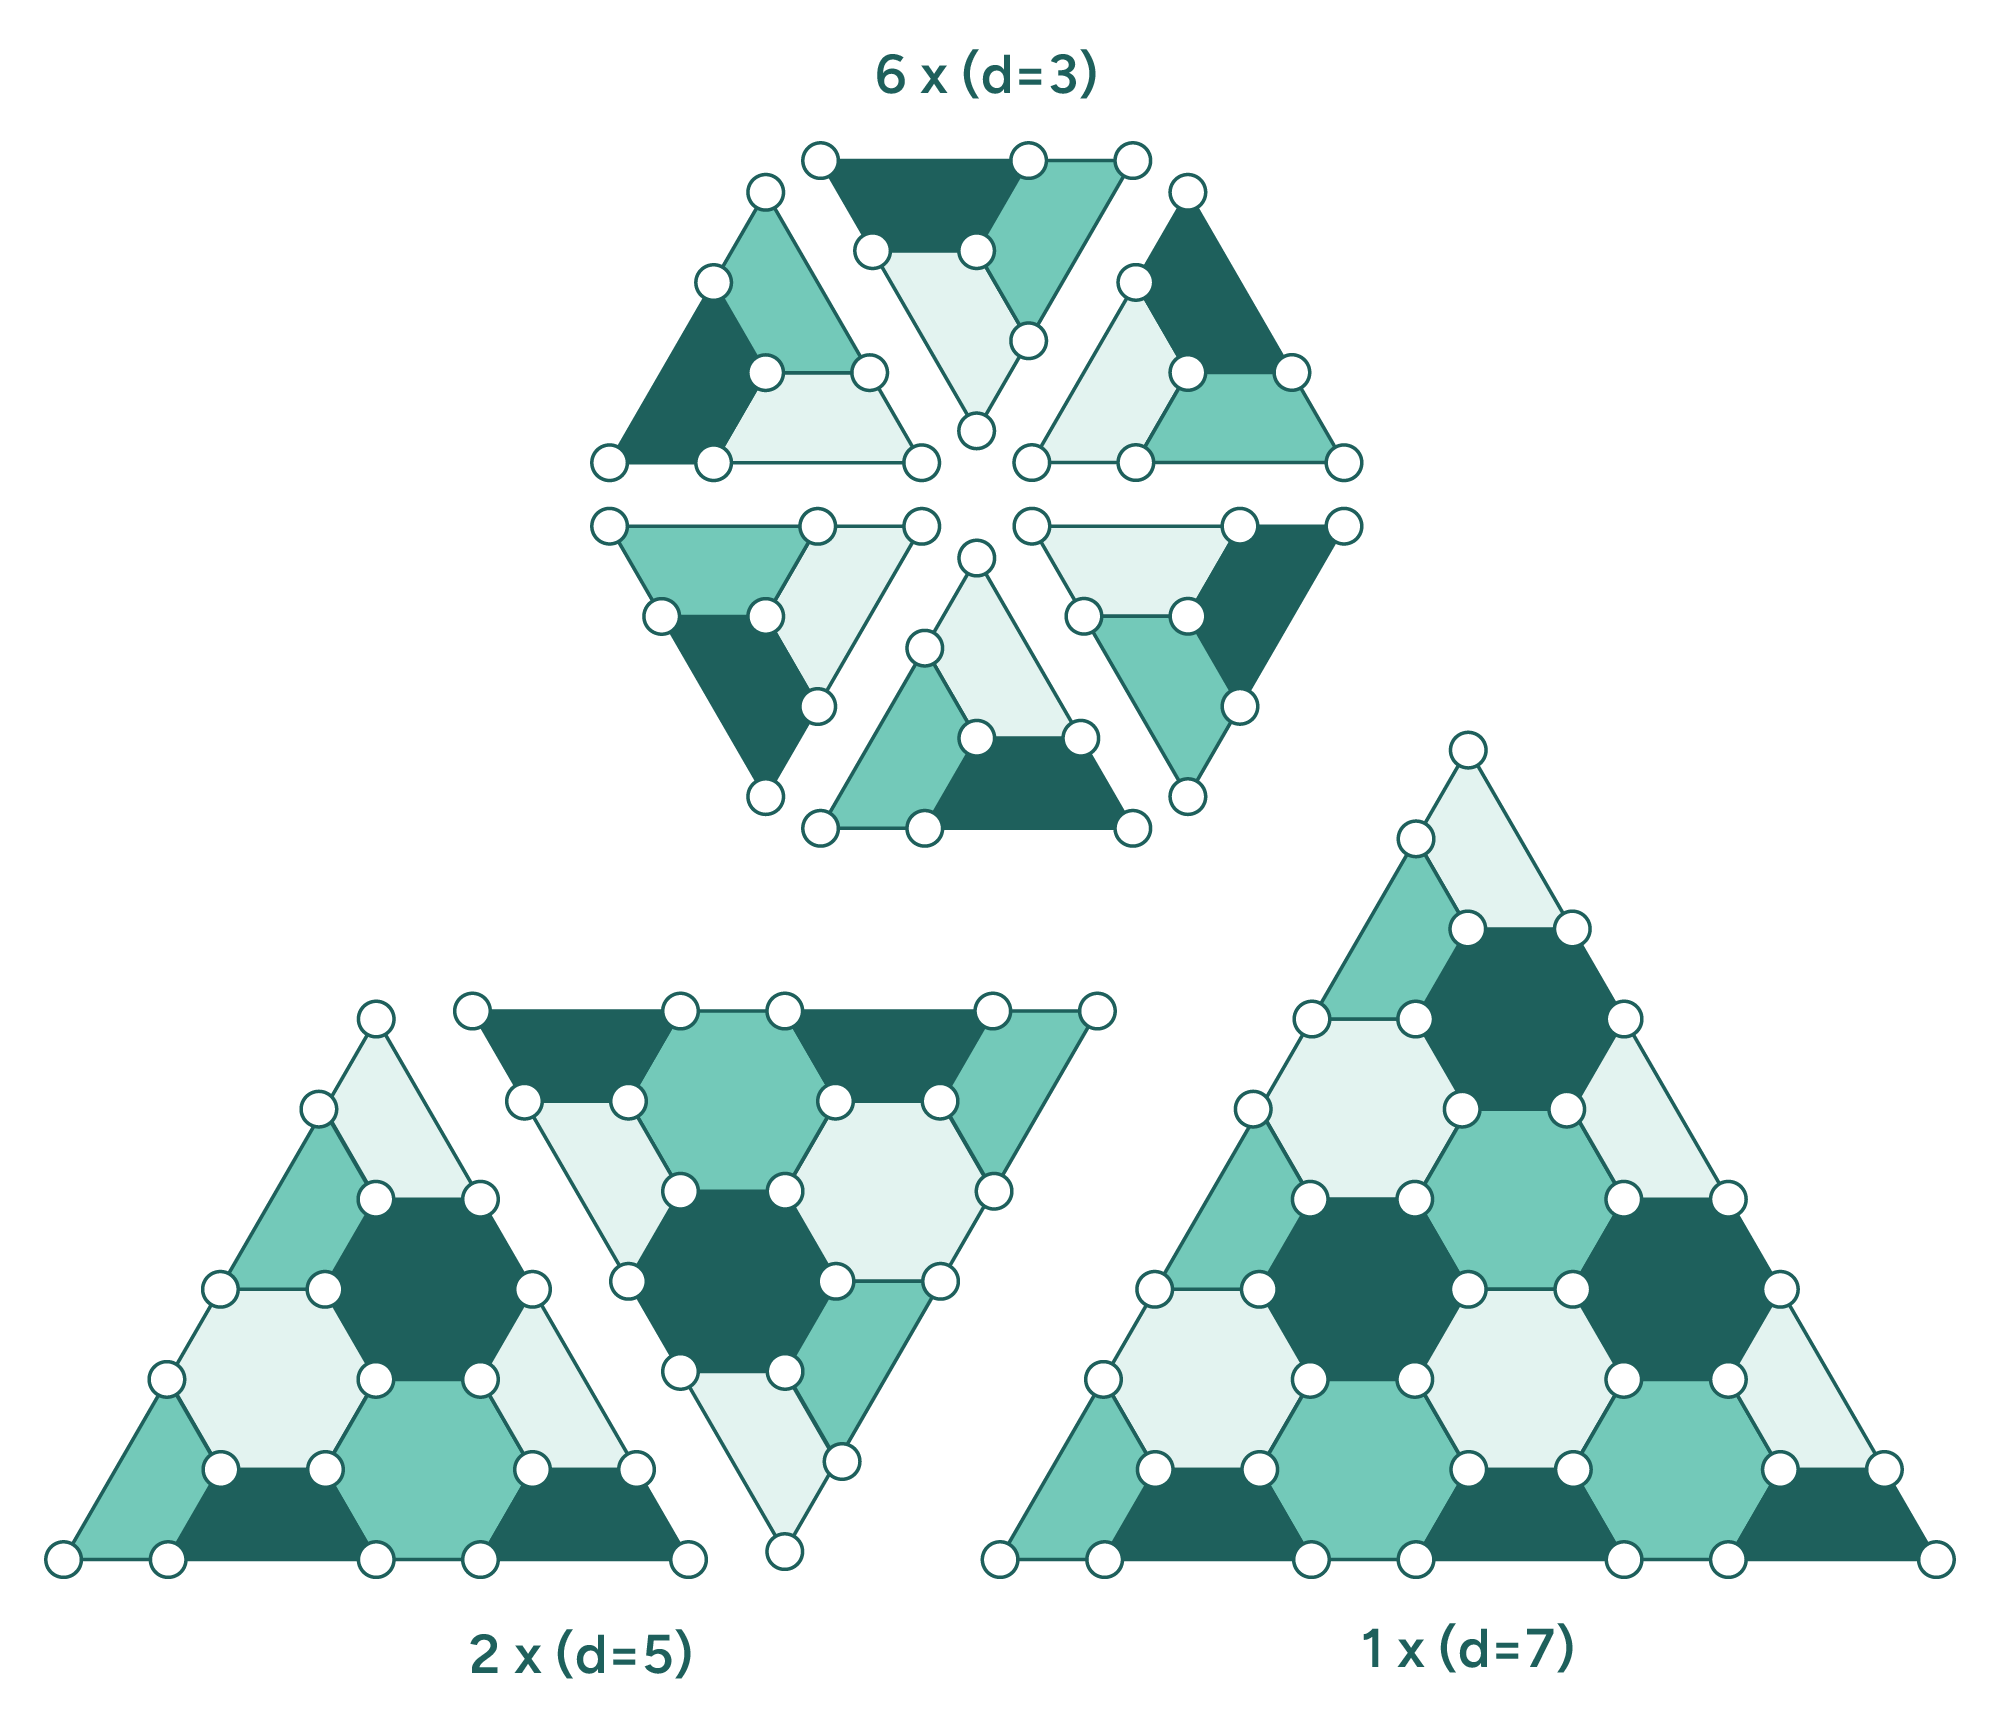
Figure 4. Animation of logical qubit growth with increasing code distance. The white circles represent physical qubits, and the animation shows how logical qubits are formed at color code distances of 3, 5, and 7.
Our trapped-ion qubits lead to significant resource savings
On top of our new record in fidelity, the scaling with code distance reveals something very important: our QCCD8 approach is expected to reach utility scale with far less resources than other modalities.
This all comes down to the value of Λ, which describes how quickly error rates decrease with increasing code distance. The most comparable result, done in a superconducting architecture with the color code, had a Λ of 1.56, while Helios demonstrated a Λ of 12. This means that we can hit a ‘utility scale’ error rate, say 10-12, with shorter distance codes - which translates to far less physical qubits.
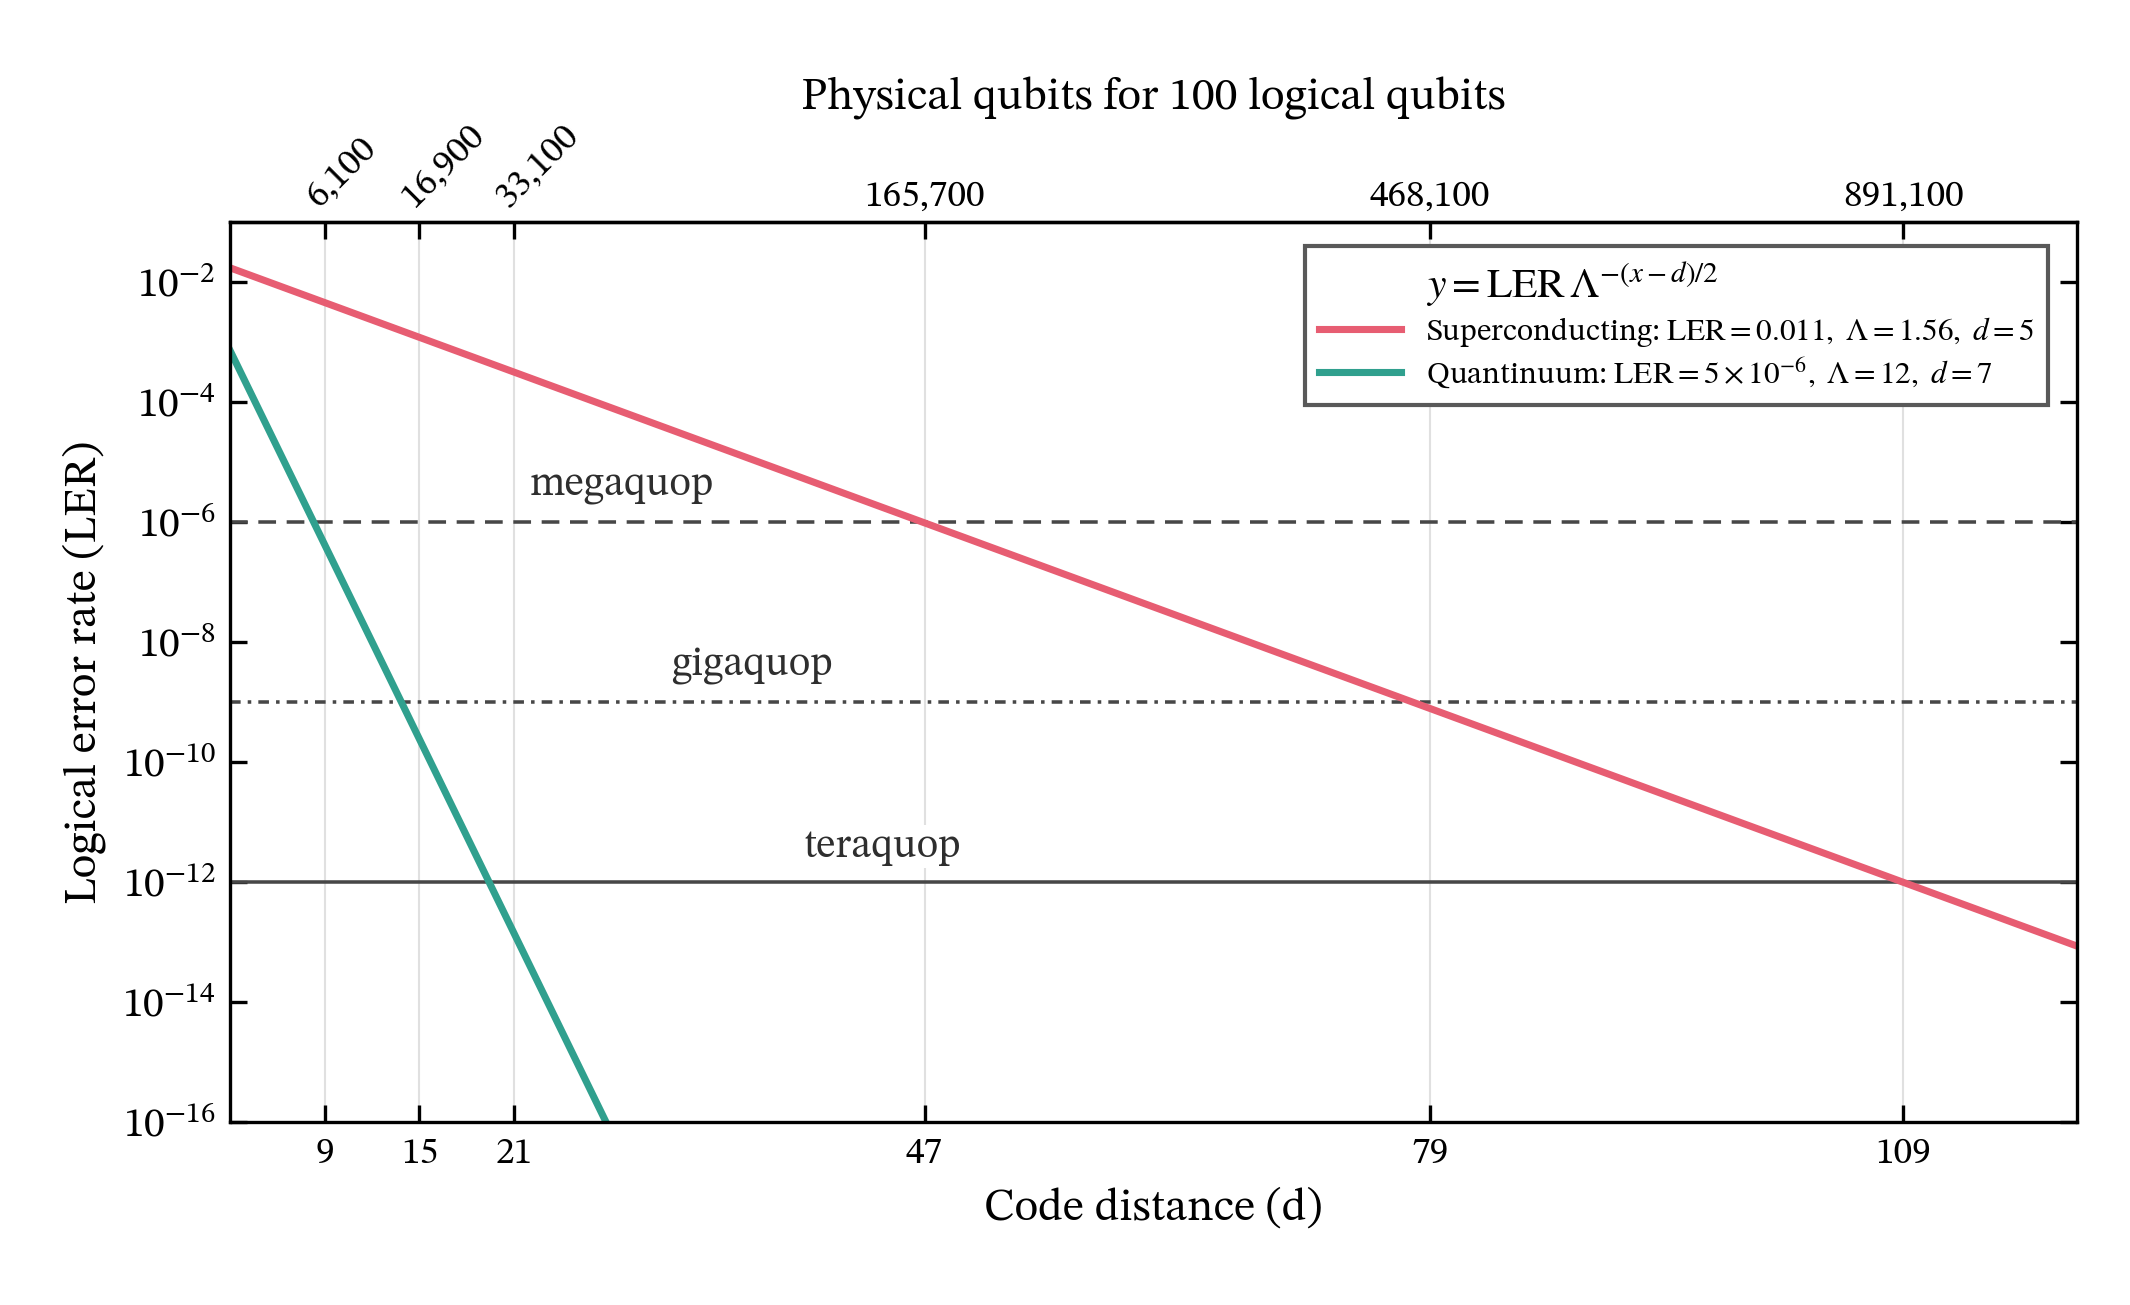
Mathematically, this is a straightforward calculation: you take a known error rate at a given distance (call this LERd), then you compute LERd×Λ(x-d)/2, then find whatever code distance is needed to get to your desired error rate.
The plot above compares state-of-the-art color code implementations on Helios and a superconducting architecture. For an error rate of 10-12, indicated with a horizontal black line, the superconducting system would need a code distance of 109 to achieve the target error rate, while our computers would only need a code distance of 219.
Translating this into a physical qubit requirement to generate 100 logical qubits, the superconducting processor would need ~900,000 physical qubits while our QCCD processors would only need ~30,000, a ~30x resource savings. This also brings in timelines: building a 30,000-qubit processor is much more likely in the near term than a 900,000-qubit processor.
In our recent blog about the Helix QEC architecture, we pointed out how our targeted physical fidelities will keep advancing our logical fidelities. That holds here as well: with the physical fidelity improvements targeted for Sol and Apollo, we will see an improved LERd and Λ, meaning that we can achieve target error rates at even shorter distance codes than above. This brings in timelines further: even fewer physical qubits will be needed.
Finally, we have access to codes that cost less qubits in the first place. These ‘high encoding rate’ codes require connectivity beyond what is available in fixed qubit superconducting systems. With our reconfigurable qubits, we can implement exotic entangling schemes that allow for a single physical qubit to be shared amongst several logical qubits, further improving resource estimates and bringing in the timelines to large scale utility.
Our Sol system, coming next year, will continue to reduce these costs by moving us to a grid-shaped trap, shortening transport and cooling times, while enabling full connectivity at a larger scale.
Figure 6. A qubit moves through a prototype grid trap, demonstrating the precise control and dynamic qubit transport that enable all-to-all connectivity in our QCCD architecture. This is footage from an operating device, not an artist’s rendering.
An important takeaway is that a lot of resource estimates that claim we will need X qubits or Y gates to do some algorithm are outdated; as they rely on assumptions about distance scaling and QEC codes that are not relevant to our QCCD architecture. With our high fidelity and full connectivity, we will be able to achieve target applications sooner than expected (compared to many external estimates), needing fewer qubits and fewer gates overall.
Helios as a pathfinder
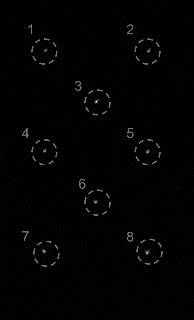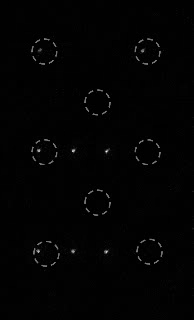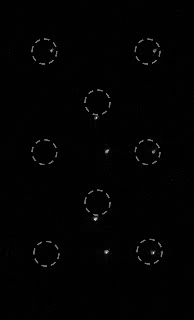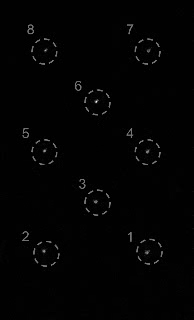
Figure 7. Qubits are rearranged within a prototype grid trap using broadcast control signals, demonstrating our solution to quantum computing’s “wiring problem.” This approach dramatically reduces the number of control signals—or “wires”—needed to route qubits, overcoming a critical barrier to scaling into the megaquop regime. We first demonstrated this capability in 2024. The video shows real qubits in motion—it is not an artist’s rendering.
This result reflects more than the performance of an exceptional QPU. It is the product of a cross-functional, full-stack team working in close coordination, using Helios as a pathfinder for our next generation systems.
For example, one challenge every leading quantum computing platform faces is leakage: an unwanted process that takes the system out of the two qubit states used for computation. Leakage is especially damaging for QEC codes, which are built to fix errors within those two states and are not equipped to handle a qubit that has left them. Moreover, all subsequent operations on a leaked qubit quietly fail — a single leak can lead to a cascade of correlated errors which could result in a logical failure.
On Helios, the team built a mid-circuit fix: ‘leakage repump’, which returns leaked qubits back into the computational states as ordinary, correctable errors — improving our logical error rate by over an order of magnitude and enabling our distance-scaling demonstration.
Another example is ultra-efficient decoding. Syndrome data must be interpreted quickly enough to correct errors before the quantum information degrades. The team evaluated several approaches, including machine-learning decoders developed by Quantinuum’s AI team, ultimately demonstrating accurate decoding with sub-millisecond latency, which is 10-100x faster than needed to get corrections.
Both of these point to Helios operating in pathfinder mode: helping us understand how to extract the best performance from this generation of hardware, while translating those lessons into the next. That knowledge cannot come from simulation alone – we need to build and test real hardware to continue advancing. As Lead Physicist Dr. Adam Reed put it, "When we push Helios to its limits, we often learn something the simulations didn't tell us."
By bringing together our theory, facilities, AI, and hardware teams, we pushed our trapped-ion hardware into a new performance regime—showing how our flexible logical architecture, tailored decoders, and highly accurate trapped-ion hardware work together to advance our path to Apollo in 2029.
1 Noisy Intermediate-Scale Quantum
2 In practice, we ran for 580,000 shots (29k shots, each one having 20 rounds, and observed 3 failures), which gave us just enough statistical confidence to claim the ultimate error rate.
3 As you can see in Figure 3, the suppression factor has error bars of +8 and -4, meaning it could be much better or closer to the 12x we measured in the other experiment.
4 With the color code, only odd code distances are available.
5 The previous state of the art demonstration of distance scaling with the color code (with a maximum distance of 5) showed an error rate of 1.1% per cycle, in which case Helios shows a 2,200x improvement.
6 If you want to compare these demonstrations at the same distance, Helios showed an error rate of 0.004% with a distance 5 code, which is a 204x improvement.
7 The previous state of the art demonstration of distance scaling with the surface code (with a maximum distance of 7) showed an error rate of 0.143% per cycle, in which case Helios shows a 286x improvement.
8 Quantum Charge Coupled Device
9 It might look like we need a shorter distance code, but recall that only odd code distances are available with the color code. To hit the teraquop regime, we need slightly more than a code distance of 19. The next highest distance is 21.