

Quantum Volume Testing: Setting the Steady Pace to Higher Performing Devices

When it comes to completing the statistical tests and other steps necessary for calculating quantum volume, few people have as much as experience as Dr. Charlie Baldwin.
Baldwin, a lead physicist at Quantinuum, and his team have performed the tests numerous times on three different H-Series quantum computers, which have set six industry records for measured quantum volume since 2020.
Quantum volume is a benchmark developed by IBM in 2019 to measure the overall performance of a quantum computer regardless of the hardware technology. (Quantinuum builds trapped ion systems).
Baldwin’s experience with quantum volume prompted him to share what he’s learned and suggest ways to improve the benchmark in a peer-reviewed paper published this week in Quantum.
“We’ve learned a lot by running these tests and believe there are ways to make quantum volume an even stronger benchmark,” Baldwin said.
We sat down with Baldwin to discuss quantum volume, the paper, and the team’s findings.
How is quantum volume measured? What tests do you run?
Quantum volume is measured by running many randomly constructed circuits on a quantum computer and comparing the outputs to a classical simulation. The circuits are chosen to require random gates and random connectivity to not favor any one architecture. We follow the construction proposed by IBM to build the circuits.
What does quantum volume measure? Why is it important?
In some sense, quantum volume only measures your ability to run the specific set of random quantum volume circuits. That probably doesn’t sound very useful if you have some other application in mind for a quantum computer, but quantum volume is sensitive to many aspects that we believe are key to building more powerful devices.
Quantum computers are often built from the ground up. Different parts—for example, single- and two-qubit gates—have been developed independently over decades of academic research. When these parts are put together in a large quantum circuit, there’re often other errors that creep in and can degrade the overall performance. That’s what makes full-system tests like quantum volume so important; they’re sensitive to these errors.
Increasing quantum volume requires adding more qubits while simultaneously decreasing errors. Our quantum volume results demonstrate all the amazing progress Quantinuum has made at upgrading our trapped-ion systems to include more qubits and identifying and mitigating errors so that users can expect high-fidelity performance on many other algorithms.
You’ve been running quantum volume tests since 2020. What is your biggest takeaway?
I think there’re a couple of things I’ve learned. First, quantum volume isn’t an easy test to run on current machines. While it doesn’t necessarily require a lot of qubits, it does have fairly demanding error requirements. That’s also clear when comparing progress in quantum volume tests across different platforms, which researchers at Los Alamos National Lab did in a recent paper.
Second, I’m always impressed by the continuous and sustained performance progress that our hardware team achieves. And that the progress is actually measurable by using the quantum volume benchmark.
The hardware team has been able to push down many different error sources in the last year while also running customer jobs. This is proven by the quantum volume measurement. For example, H1-2 launched in Fall 2021 with QV=128. But since then, the team has implemented many performance upgrades, recently achieving QV=4096 in about 8 months while also running commercial jobs.
What are the key findings from your paper?
The paper is about four small findings that when put together, we believe, give a clearer view of the quantum volume test.
First, we explored how compiling the quantum volume circuits scales with qubit number and, also proposed using arbitrary angle gates to improve performance—an optimization that many companies are currently exploring.
Second, we studied how quantum volume circuits behave without errors to better relate circuit results to ideal performance.
Third, we ran many numerical simulations to see how the quantum volume test behaved with errors and constructed a method to efficiently estimate performance in larger future systems.
Finally, and I think most importantly, we explored what it takes to meet the quantum volume threshold and what passing it implies about the ability of the quantum computer, especially compared to the requirements for quantum error correction.
What does it take to “pass” the quantum volume threshold?
Passing the threshold for quantum volume is defined by the results of a statistical test on the output of the circuits called the heavy output test. The result of the heavy output test—called the heavy output probability or HOP—must have an uncertainty bar that clears a threshold (2/3).
Originally, IBM constructed a method to estimate that uncertainty based on some assumptions about the distribution and number of samples. They acknowledged that this construction was likely too conservative, meaning it made much larger uncertainty estimates than necessary.
We were able to verify this with simulations and proposed a different method that constructed much tighter uncertainty estimates. We’ve verified the method with numerical simulations. The method allows us to run the test with many fewer circuits while still having the same confidence in the returned estimate.
How do you think the quantum volume test can be improved?
Quantum volume has been criticized for a variety of reasons, but I think there’s still a lot to like about the test. Unlike some other full-system tests, quantum volume has a well-defined procedure, requires challenging circuits, and sets reasonable fidelity requirements.
However, it still has some room for improvement. As machines start to scale up, runtime will become an important dimension to probe. IBM has proposed a metric for measuring run time of quantum volume tests (CLOPS). We also agree that the duration of the computation is important but that there should also be tests that balance run time with fidelity, sometimes called ‘time-to-solution.”
Another aspect that could be improved is filling the gap between when quantum volume is no longer feasible to run—at around 30 qubits—and larger machines. There’s recent work in this area that will be interesting to compare to quantum volume tests.
You presented these findings to IBM researchers who first proposed the benchmark. How was that experience?
It was great to talk to the experts at IBM. They have so much knowledge and experience on running and testing quantum computers. I’ve learned a lot from their previous work and publications.
There is a lot of debate about quantum volume and how long it will be a useful benchmark. What are your thoughts?
The current iteration of quantum volume definitely has an expiration date. It’s limited by our ability to classically simulate the system, so being unable to run quantum volume actually is a goal for quantum computing development. Similarly, quantum volume is a good measuring stick for early development.
Building a large-scale quantum computer is an incredibly challenging task. Like any large project, you break the task up into milestones that you can reach in a reasonable amount of time.
It's like if you want to run a marathon. You wouldn’t start your training by trying to run a marathon on Day 1. You’d build up the distance you run every day at a steady pace. The quantum volume test has been setting our pace of development to steadily reach our goal of building ever higher performing devices.
About Quantinuum
Quantinuum, the world’s largest integrated quantum company, pioneers powerful quantum computers and advanced software solutions. Quantinuum’s technology drives breakthroughs in materials discovery, cybersecurity, and next-gen quantum AI. With over 500 employees, including 370+ scientists and engineers, Quantinuum leads the quantum computing revolution across continents.
Thirty participants gathered at Newnham College, Cambridge, for an intensive five-day programme exploring how quantum computers can be used to model chemical systems.
By: Duncan Gowland, Senior Advanced R&D Scientist at Quantinuum
For 30 researchers who gathered at Newnham College, Cambridge this September, that question shaped an intensive five-day programme.
Quantinuum’s first InQuanto Summer School, supported by the UK’s National Quantum Computing Centre (NQCC), combined lectures, hands-on workshops, and mini-projects to help participants connect fundamental concepts with practical research. By the end of the week, participants were applying those ideas to problems ranging from molecular electronic structure to quantum state-preparation circuits.
Applying quantum computing to chemistry can be challenging because it draws on expertise from a broad range of areas, including electronic structure theory, quantum algorithms, software, hardware, noise modelling, and resource estimation. Researchers often enter the field with deep knowledge of one or two of these areas but less familiarity with the others.
A key objective of the course was to help researchers from computational chemistry and quantum computing build stronger foundations, develop a shared language, and deepen their understanding of adjacent disciplines.
For researchers beginning work at this intersection, that shared understanding can make it easier to identify where to start, which assumptions to challenge, and when to seek expertise from another discipline.
Bringing Theory and Practice Together
The programme began with lectures on the foundations of quantum computing, followed by pen-and-paper and computational exercises in the afternoon. On Day 2, lectures and workshops introduced the electronic structure problem: how quantum chemists describe the behaviour of electrons in molecules.
Students then brought these two foundations together by studying fermion-to-qubit mappings, which translate chemistry problems into a form that quantum computers can process, before moving on to the measurement of chemistry observables and the construction of quantum algorithms.
Learners were given free access to InQuanto, Quantinuum’s quantum chemistry software platform designed to accelerate research in fields such as chemistry and condensed matter physics using quantum computers. InQuanto supported the lectures as a broad, well-documented, and thoroughly tested platform that enabled students to explore and reinforce complex concepts through hands-on experience.
Later in the week, attention shifted to state-of-the-art considerations: how to build useful chemical models, make the best use of current quantum devices, and think about how quantum algorithms for chemistry might develop over the next five to ten years.
The students, who travelled from around the world to Cambridge, brought a remarkable range of backgrounds and experience. The material was pitched at roughly first-year doctoral level, for participants with at least a year of experience in one core area and some Python skills. Even with this experience, participants benefited from exposure to other disciplines and from the practical expertise of Quantinuum’s quantum chemistry team—which brings years of experience working with industrial including BMW Group, TotalEnergies, NVIDIA, and Pfizer.
Throughout the week, participants were highly engaged in lectures and brought a thoughtful, collaborative approach to the workshop exercises. Discussions continued throughout the week, from coffee breaks to lunches and dinners, creating valuable opportunities to exchange ideas and experiences.
A particular highlight was the mini-project work. In just a day and a half, participants tackled a wide range of problems and produced impressive prototype solutions. The projects concluded with a poster-style session, where the quality of discussion was exceptional. Examples included state-preparation programmes using mid-circuit measurement in Guppy; investigations of active-space selection and quantum-selected configuration interaction (QSCI) for the chromium dimer; and the use of the atomic valence active space (AVAS) approach to identify active spaces and perform resource estimation for myoglobin.
One participant reimplemented their research on efficient state-preparation circuits based on orbital entanglement in InQuanto and compared the performance of those circuits with the platform’s efficient ansatz methods on the Helios emulator. It was rewarding to see participants apply these tools to their own research challenges and explore new approaches to quantum chemistry.
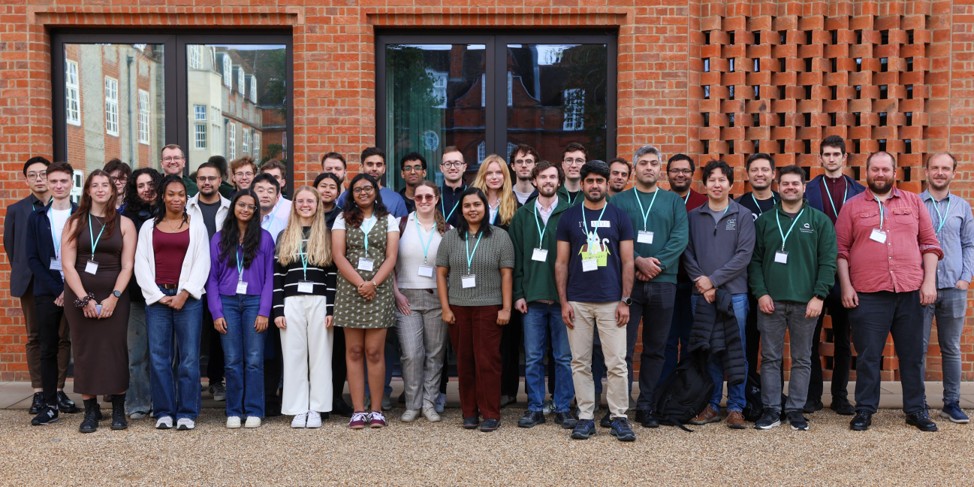
With Support from the UK’s National Quantum Computing Centre
This rewarding week was made possible through the support of the UK’s National Quantum Computing Centre, whose partnership helped bring the programme to life, and by the contributions of colleagues across Quantinuum. The teaching team brought together experts from our quantum chemistry, compiler, and error-correction teams, who developed the course materials, delivered lectures, and led the workshops.
Above all, the programme demonstrated the value of bringing researchers together around a shared foundation, practical tools, and opportunities to learn from one another. We look forward to seeing how participants build on these ideas in their future research.
Interested in future training opportunities, workshops, and community events from Quantinuum? Join QNET to stay connected with the latest updates, resources, and opportunities to engage with the quantum computing community.
For years, the quantum landscape has been crowded with headline hype, speculative roadmaps, and vanity qubit counts.
While that noise hasn't completely disappeared, Quantum World Congress 2026 proved that the market's tolerance for hype is rapidly wearing thin. While benchmark simulations and roadmap announcements still generate headlines, the real conversation on the ground has shifted toward a far more demanding question: who is actually delivering useful execution today and making meaningful progress toward fault-tolerant quantum computing?
At Quantinuum, our stance has never wavered. Progress is measured by delivering integrated systems that perform useful computation reliably on real hardware and in live enterprise environments. Prove what you can do and publish the results.
What was most encouraging this year at Quantum World Congress was seeing much of the industry increasingly align around that view, with the conversation converging around several priorities in particular.
1. Fault tolerance proven on real hardware is the only credible path to scale
The industry is converging around a shared reality: useful quantum computing will be defined by fault tolerance.
But fault tolerance is not a single metric, a logical-qubit count, or a standalone error-correction demonstration. It requires a complete end-to-end architecture that can detect, correct, and manage errors across every layer of computation, from logical operations to resource-state preparation, and execution of useful algorithms on live hardware.
That is why context matters when evaluating industry announcements.
Demonstrating more logical qubits is not the same as demonstrating fault tolerance. Demonstrating real-time decoding in a simulation is not the same as demonstrating real-time quantum error correction on real hardware. Logical qubits, decoders, syndrome extraction, and resource-state preparation are all necessary ingredients. But proving an individual ingredient in isolation, particularly through simulations or benchmark environments, is fundamentally different from proving that a complete fault-tolerant architecture works on a live quantum computer.
The industry should not confuse progress on individual building blocks with proof of a scalable fault-tolerant system. The real test is whether all these capabilities work together to improve computational performance beyond the physical layer and in a way that can scale.
This is exactly what Quantinuum's Helix architecture is designed to do.
Running on our Helios system, Helix integrates the full stack required for fault-tolerant quantum computing and has already delivered world-class results on live commercial hardware. Helios achieves physical two-qubit gate error rates of 8×10⁻⁴, while Helix has demonstrated a logical compute error rate of 2.8×10⁻⁴, representing a 4.28× improvement over the physical Clifford gate error rate without post-selection, meaning no cherry-picked results.
Just as importantly, Helix improves efficiency as well as reliability. Through adaptive syndrome extraction, it reduces physical gate requirements by 33% and wall-clock execution time by 23%. Today, the architecture is already supporting full computations using 64 error-detected logical qubits with better-than-physical performance and a highly efficient 1:1.5 encoding rate.
These results matter because they demonstrate more than isolated milestones. They show that a scalable fault-tolerant architecture is operating on real hardware today and delivering measurable improvements in computational reliability. As physical systems grow, Helix provides the framework that enables additional scale to translate into increasingly reliable computation.
The path to fault tolerance will continue to evolve. New codes, encoding approaches, and implementation techniques will emerge over time. What remains constant is the need for an architecture capable of orchestrating those innovations into a practical, scalable system. We believe Helix is well positioned to serve as that architecture.
2. The industry must measure performance with useful, standardized metrics
Customers cannot make informed buying decisions if every vendor continues to grade their own homework. Standardized benchmarks are critical because they shift the conversation from theoretical promises to actual, measurable usefulness.
While earlier benchmarks like Quantum Volume were helpful for NISQ-era systems, they don’t keep pace as fault-tolerant systems scale beyond classical simulation limits. That is why Quantinuum is helping drive industry alignment around QUOPS, developed by Sandia National Laboratories with input from NVIDIA and Quantinuum.
QUOPS measures true computational capability by evaluating both computational Size (QUOPS) and Speed (QUOPS/sec). It’s the difference between rating an engine by theoretical horsepower versus measuring how fast and far a vehicle can drive on an actual track.
Most importantly, QUOPS evaluates the capability delivered by the complete computing stack. As the industry moves toward fault-tolerant systems, useful benchmarks must measure the performance of the entire architecture rather than individual subsystems. They must remain transparent as workloads scale, allowing enterprises to clearly evaluate the real-world utility of a system for their specific problem sets.
3. The industrial manufacturing race is on
Proving a fault-tolerant concept on a laboratory bench is only the first step. The transition to utility-scale computing is fundamentally an engineering, supply chain, and manufacturing race.
Our roadmap clearly defines how we scale from a single chip with a 2D-grid layout to larger multi-chip packages. Rather than reinventing the wheel, we are leveraging proven semiconductor manufacturing techniques that built the modern microelectronics industry. We have backed this architecture with a world-class industrial ecosystem, partnering with commercial foundries and component leaders.
The companies that win the next phase of quantum computing will not simply invent breakthrough technologies. They will demonstrate the ability to manufacture, deploy, and scale them reliably.
4. Growing the ecosystem requires a powerful developer platform built for the fault-tolerant era
A high-performing QPU is only part of the equation. You also need the software layer required to run it. For quantum to succeed, it must integrate into the workflows developers and enterprise researchers are already using today.
Nexus is our developer platform designed to be the purpose-built enterprise integration layer, designed from the ground up to squeeze maximum power and accuracy out of Quantinuum’s architectures. Nexus provides seamless interoperability across native Guppy, NVIDIA CUDA-Q, and Microsoft Q#, directly connecting quantum hardware to classical AI and HPC environments.
This is not an experimental platform. It is already supporting meaningful commercial adoption today.
Adopted by more than 200 organizations, representing approximately 45% growth, and used by more than 1,000 active developers, Nexus has seen annual job submissions increase 10x when comparing August 2024-August 2025 with August 2025-August 2026.
As quantum computing enters the fault-tolerant era, the winning platform will be the one that makes advanced quantum capabilities accessible within the workflows enterprises already depend on.
5. Real progress is measured in live production deployments and real-world research
The future of high-performance computing isn't quantum versus AI or HPC. It is all three working together as a unified compute stack.
But we believe the true test of market leadership isn't a self-funded trial or a desktop simulation that claims hybrid integration. It is putting live hardware into mission-critical operational environments to solve real enterprise problems and advance meaningful science.
That is why we are focused on embedding our quantum systems directly into global computing infrastructure. Through our partnership with Oracle, we expect to bring commercial-scale quantum computing directly into an Oracle Cloud Infrastructure AI data center, with the goal of letting enterprise customers run quantum applications within their existing cloud footprint.
Similarly, our deep, multi-year collaboration with NVIDIA continues to advance the frontiers of hybrid compute: from co-founding the NVAQC center in Boston to physically integrating NVIDIA GPUs into our Helios hardware for real-time error correction, to running live workflows with Pfizer to help accelerate pharmaceutical discovery.
Ultimately, as we scale these capabilities from the system level to the enterprise, we believe quantum computing can serve as the crucial engine to unlock far greater value from classical AI. By integrating QPUs alongside GPUs and supercomputers, we are working to move beyond the limitations of classical compute alone.
This hybrid approach enables enterprises to generate higher-quality quantum training data, build more powerful models, and tackle complex chemistry and materials challenges that remain beyond the reach of classical AI by itself.
Looking Ahead
Quantum World Congress 2026 proved that the market is finally asking the right questions:
- How do we achieve true fault tolerance at scale?
- How do we measure objective computational capability?
- How do we deploy quantum systems to solve real-world enterprise problems?
The conversation is shifting from theoretical possibility to demonstrated capability. From isolated milestones to integrated systems. From simulations to real hardware. That is where meaningful progress happens. And that is where Quantinuum intends to continue to lead.
Forward-Looking Statements:
This blog post contains forward-looking statements within the meaning of the Private Securities Litigation Reform Act of 1995, including statements about expected product capabilities, technology development timelines, planned partnerships and deployments, and anticipated market trends, and expected business metrics and growth rates. These statements are based on current expectations and assumptions and are subject to risks and uncertainties that could cause actual results to differ materially, including risks related to technology development, competitive dynamics, customer adoption, and partnership execution. Forward-looking statements speak only as of the date made, and Quantinuum undertakes no obligation to update them. For a discussion of factors that could affect outcomes, please refer to Quantinuum's public filings.
For enterprise and public sector executives evaluating quantum computing investment
Quantum computing is now a strategic priority for many organizations. It's on track to help solve some of the world's biggest challenges, from drug discovery, to materials science, to optimization problems – all at a scale classical computers simply can't reach. For executives responsible for R&D, technology strategy, or innovation investment, the question is no longer whether quantum computing matters. It's how to approach it wisely.
That's a harder question than it sounds. The quantum computing market is crowded, technical, and moving fast, and most of the guidance available is written for physicists, not for the executives who actually have to make the investment decision. Vendor claims are difficult to compare, pilot programs are easy to get wrong, and the gap between "quantum is exciting" and "quantum is worth investing in this year" isn't always well explained.
Our new guide, A Strategic Guide to Selecting the Right Quantum Computing Solution, is built to close that gap.
What's Inside
The guide is designed to give business and technology leaders a clear, practical path through four essential questions:
- Why quantum computing matters now, and why the window for early strategic advantage is open today
- How to evaluate vendors objectively, using a structured framework rather than marketing claims
- How to design an effective pilot, so early investment produces real, usable evidence
- How to take your first steps with confidence, whether you're just starting to explore or ready to scale
It also includes a glossary of key terms, so readers new to the field aren't left decoding jargon before they can evaluate a single vendor.
Who Should Read It
The guide is written for CTOs, CIOs, CISOs, R&D leaders, and program directors across enterprise and public sector organizations, at any stage of quantum familiarity. Whether your organization hasn't yet started exploring quantum computing, or you already have a program underway and are looking to sharpen your evaluation process, the framework inside is designed to apply.
How to Use It
The evaluation framework at the core of the guide isn't specific to any one vendor; it's designed to be applied to any quantum computing solution you're considering, so you can make an apples-to-apples comparison based on your organization's actual needs. The guide also walks through how Quantinuum maps to that same framework, and what it looks like to work with Quantinuum as a co-development partner, should you want a concrete reference point alongside the general framework.
Start With Confidence, Not Guesswork
Quantum computing is a strategic decision, not just a technical one. The organizations that approach it with a clear framework, rather than reacting to the noise, will be the ones positioned to capture real value as the technology matures.