

A Quantinuum-led team has built the quantum programming tools for real-time magic state distillation on a quantum computer
Researchers at Quantinuum and Microsoft’s Azure Quantum used the Quantum Intermediate Representation (QIR) to demonstrate a magic state distillation protocol for the first time on quantum hardware – a key element necessary for universal, fault-tolerant quantum computing
Building a quantum computer that offers advantages over classical computers is the goal of quantum computing groups worldwide. A competitive quantum computer must be “universal”, requiring the ability to perform all operations already possible on a classical computer, as well as new ones specific to quantum computing. Of course, that’s just the beginning – it should also be able to do this in a reasonable amount of time, to deal effectively with noise from the environment, and to perform computations to arbitrary accuracy.
This is a lot to get right, and over the years quantum computer scientists have described ways to solve these often-overlapping challenges. To deal with noise from the environment and achieve arbitrary accuracy, quantum computers need to be able to keep going even as noise accumulates on the quantum bits, or qubits, which hold the quantum information. Such fault-tolerance may be achieved using quantum error correction, where ensembles of physical qubits are encoded into logical qubits and those are used to counteract noise and perform computational operations called gates. Unfortunately, no single quantum error correction code plays well with the goal of universality because all codes lack a complete universal set of fault-tolerant gates (the technical reason for this comes down to the way quantum gates are executed between logical qubits – the native gate set on error-corrected logical qubits are known by experts as transversal gates, and they do not include all the gates needed for universal quantum computing).
The solution to this obstacle to universality is a magic state, a quantum state which provides for the missing gate when error correcting codes are used. High fidelity magic states are achieved by a process of distillation, which purifies them from other noisier magic states. It is widely recognized that magic state distillation is one of the totemic challenges on the path towards universal, fault-tolerant quantum computing. Quantinuum’s scientists, in close collaboration with a team at Microsoft, set out to demonstrate the distillation process in real-time using physical qubits on a quantum computer for the first time.
The results of this work are available in a new paper, Advances in compilation for quantum hardware -- A demonstration of magic state distillation and repeat until success protocols.
Magic state distillation
How does magic state distillation work? Imagine a factory, taking in many qubits in imperfect initial states at one end. Broadly speaking, the factory distills the imperfect states into an almost pure state with a smaller error probability, by sending them through a well-defined process over and over. In this case, the process takes in a group of five qubits. It applies a quantum error correcting code that entangles these five qubits, with four used to test whether the fifth, target qubit has been purified. If the process fails, the ensemble is discarded and the process repeats. If it succeeds, the newly distilled target qubit is kept and combined with four other successes to form a new ensemble, which then rejoins the process of continued purification. By undertaking this process many times, the purity of the magic state increases at each step, gradually moving towards the conditions required for universal, fault-tolerant quantum computing.
Despite being the subject of theoretical exploration over decades, real-time magic state distillation had never been realized on a quantum computer. In typical pioneering style, the Quantinuum and Microsoft team decided to take on this challenge. But before they could get started, they recognized that their toolset would have to be significantly sharpened up.
Creating new tools for quantum programming
At the heart of magic state distillation is a highly complex repeating process, which requires state-of-the-art protocols and control flow logic built on a best-in-class programming toolset. The research team turned to Quantum Intermediate Representation (QIR) to simplify and streamline the programming of this complex quantum computing process.
QIR is a is a quantum-specific code representation based on the popular open-sourced classical LLVM intermediate language, with the addition of structures and protocols that support the maturation and modernization of quantum computing. QIR includes elements that are essential in classical computing, but which are yet to be standardized in quantum computing, such as the humble programming loop.
Loops, which often take forms like "for...next" or "do...while," are central to programming, allowing code to repeat instructions in a stepwise manner until a condition is met. In quantum computing, this is a tough challenge because loops require control flow logic and mid-circuit measurement, which are difficult to realize in a quantum computer but have been demonstrated in Quantinuum’s System Model H1-1, Powered by Honeywell. Loops are essential for realizing magic state distillation and it’s well-understood that LLVM is great at optimizing complex control flow, including loops. This made magic state distillation a natural choice for demonstrating a valuable application of QIR and making for a great example of the use of a classical technique in a quantum context.
Result: demonstrating a magic state distillation protocol
The team used Quantinuum’s H1-1 quantum computer – benefiting from industry-leading components such as mid-circuit measurement, qubit reuse and feed-forward – to make possible the quantum looping required for a magic state distillation protocol, and becoming the first quantum computing team ever to run a real-time magic state distillation protocol on quantum hardware.
Four ways to achieve a quantum computer programmable loop
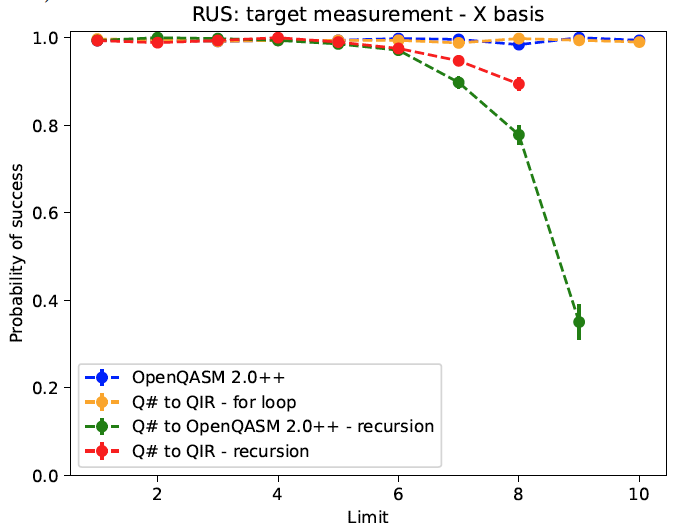
Building on this success, the team designed further experiments to assess the potential of four methods for exploring the use of a quantum protocol called a repeat-until-success (RUS) circuit to achieve a loop process. First, they hard-coded a loop directly into the extended OpenQASM 2.0, a widely used quantum assembly language, but which requires additional overhead to target advanced components on Quantinuum's very versatile H-Series quantum computer. Against this, they compared two alternative methods for coding a loop in a standard high-level programming language: controlled recursion, which was directed through both OpenQASM and through QIR; and a native for loop made possible within QIR.
The results were clear-cut: the hard-coded OpenQASM 2.0 loop performed as well as the theoretical prediction, maintaining high quality results after a number of loops, as did the natively-coded QIR for loop. The two recursive loops saw the quality of their results drop away fast as the loop limit was raised. But in a head-to-head between hard-coded OpenQASM and QIR, which converts high-level source code from many prominent and familiar languages into low-level machine code, QIR won hands-down on the basis of practicality.
Martin Roetteler, Director of Quantum Applications at Microsoft, shared: “This was a very exciting exploration of control flow logic on quantum hardware. In seeking to understand the capabilities of QIR to optimize programming structures on real hardware, we were rewarded with a clear answer, and an important demonstration of the capabilities of QIR.”
H2’s 32 qubits will power the next phase
In follow-up work, the team is now preparing to run a logical magic state protocol on the H2-1 quantum computer with its 32 high-fidelity qubits, and hopes to become the first group to successfully achieve logical magic state distillation. The features and fidelity offered by the H2 make it one of the best quantum computers currently capable of shooting for such a major milestone on the journey towards fault tolerance, while the current work demonstrates that, in QIR, the necessary control flow logic is now available to achieve it.
The paper discussed in this post was authored by Natalie C. Brown, John P. Campora III, Cassandra Granade, Bettina Heim, Stefan Wernli, Ciaran Ryan-Anderson, Dominic Lucchetti, Adam Paetznick, Martin Roetteler, Krysta Svore and Alex Chernoguzov.
About Quantinuum
Quantinuum, the world’s largest integrated quantum company, pioneers powerful quantum computers and advanced software solutions. Quantinuum’s technology drives breakthroughs in materials discovery, cybersecurity, and next-gen quantum AI. With over 500 employees, including 370+ scientists and engineers, Quantinuum leads the quantum computing revolution across continents.
Quantum computing is often framed as a race to the most qubits, the fastest gates, and the biggest benchmarks.
But a race needs a destination. In the fault-tolerant era, that means solving a valuable problem faster or at a lower cost than the best classical approach—and the time to solution is ultimately what matters most.
In this context, gate speed metrics have received a lot of attention. While gate speed is a meaningful component of the overall quality of a quantum computer, what actually matters most is fidelity. As we all know, speed on its own matters little if we don’t arrive at the correct destination.
Fidelity has emerged as the most important foundation for success in quantum computing. Higher fidelity means fewer errors in the underlying physical operations. Combined with quantum error correction, higher fidelity can reduce the number of additional qubits and operations needed to make computations reliable. This reduction in overhead can lower costs and shorten the time to deliver a useful answer—even compared with systems that have faster gates but lower fidelity.
Fast Gates Do Not Guarantee Fast Answers
Consider a simple example. In an independent-error model, a computation with 10,000 operations, each with an error rate of 10⁻³, or 99.9% fidelity, will experience about ten faults on average that can render the computation useless.
Now make every gate ten times faster without changing its error rate. You still get ten faults. You just get them ten times sooner.
Speed matters, but the relevant measure is the total time required to obtain a trustworthy and useful result. Getting to that point requires performance in many different and connected areas such as state preparation, measurement, error correction, repeated runs, and other work needed to complete the computation.
Gate speed alone cannot establish which system performs best. A fast machine that cannot reliably finish a sufficiently large computation cannot deliver commercial value.
Why Fidelity Changes the Resource Equation
Quantum error correction protects information by encoding it across multiple physical qubits. That protection requires resources: additional qubits, measurements, operations, and classical processing. These techniques work better when the underlying physical operations are reliable enough that increasing error protection reduces the logical error rate.
This requirement is known as the fault-tolerance threshold, the point below which physical error rates are low enough that adding protection reduces logical errors. Faster gates can shorten the computation, but they cannot replace the physical fidelity needed to cross that threshold.
At Quantinuum, our latest error-correction results on Helios demonstrate this principle. Using our error-correction architecture, logical memory errors fell exponentially as we increased protection. Across the tested code sizes, the fitted error reduction was about twelvefold for each increase of two in code distance. In the largest quantum-memory experiment, the estimated failure rate was about five in a million per error-correction cycle.[1] This demonstrates how high-fidelity physical operations and effective error correction work together to make quantum information more reliable as protection grows.
The next question is what that reliability enables. How large a computation can a system complete, and how quickly can it deliver the result?
A New Performance Benchmark
The Quantum Universal Operations Performance System, or QUOPS, provides a standardized way to assess both. This architecture-neutral benchmark gauges performance by measuring computational “reach” and speed.[2]
“Reach” measures how large a benchmark circuit a system can execute successfully. Speed measures how quickly it executes that circuit, in effective quantum operations per second. QUOPS uses wall-clock time and accounts for extra samples and discarded runs caused by noise.
Together, these measures provide a common basis for comparing what different quantum systems deliver and tracking progress toward better time to solution.
Quantinuum’s H2 and Helios systems executed substantially larger benchmark circuits than Google’s Willow and IBM’s Boston. These superconducting systems sometimes achieved higher effective operation rates, but on smaller circuits, which means that they are not computationally comparable.
Superconducting systems can use error mitigation to tackle larger computations, but at a steep cost in speed. The QUOPS study estimates that the additional repetitions can make effective processing thousands of times slower [6]. Some computations remain beyond the system’s reliable reach, even with mitigation. In those cases, faster gates may deliver no useful answer at all within practical limits on time and cost.
Useful applications require speed on much larger circuits. For example, the study estimates that factoring RSA-2048 or calculating FeMoco’s ground-state energy within five days would require roughly 100,000 times the computational reach demonstrated by today’s physical-qubit processors. Some machines approach the estimated speed requirement, but only on small circuits. The challenge is to sustain that speed at the required scale, including the additional work needed for error correction.
Larger uncorrected circuits accumulate more errors. Protecting them requires extra qubits and time. Reliability and speed must therefore scale together, and QUOPS offers a way to track both.
Higher Fidelity Makes Larger, Reliable Computations Possible
Improving fidelity can reduce the extra qubits and operations needed for error correction, lowering the time, cost, and resources required for useful computation. The benefit comes from reaching the required reliability with less protection, leaving more resources available for the computation itself.
Helios brings together the physical performance and error-correction capabilities needed to pursue those savings. In our paper published in Nature we showed that the system achieved an average single-qubit gate fidelity of 99.9975% and average two-qubit gate fidelity of 99.921% across its operational zones, while scaling the trapped-ion architecture to 98 fully connected physical qubits.[3]
The latest color-code experiments build on that physical performance. Alongside the logical memory results, protected two-qubit Clifford operations also became more reliable as protection increased. This connects improvements in the underlying hardware to improvements in logical computation.
A flexible error-correction architecture creates further opportunities to improve efficiency. Our recent Helix and color-code demonstrations used the same Helios hardware to explore different balances of accuracy and physical-qubit requirements. That flexibility allows us to evaluate which codes best suit different computational tasks as systems scale.
However, we continue to push ahead and accelerate the development of machines, such as Apollo, where quantum utility comes into play at scale. Decoding in the new color-code benchmarks was performed offline, and we are now turning our attention to integrating error correction, magic-state resources and real-time control into longer, reliable computations.
While that work continues, today’s systems can already contribute to scientific research. NISQ systems have advanced algorithms and hardware, enabled certified randomness, and supported studies of quantum magnetism and superconducting pairing correlations. These results leave room for useful applications before fault tolerance, even as error correction provides the scalable path to larger, reliable computations.[4]
The goal is to combine these capabilities so that larger computations can run reliably within practical limits on time and resources. Fidelity provides the foundation, and optimizing the full system turns that foundation into better time to solution.
Fidelity First. Then Optimize Time to Solution.
Scaling quantum computation requires continued progress in fidelity. As physical operations move further below threshold, increasing error protection can suppress logical errors more effectively, enabling longer, more demanding computations.
Speed must improve alongside that reliability. Advances in transport, cooling, measurement, compilation, and parallel execution can reduce the time and total cost of solving useful problems. These improvements become increasingly valuable as systems gain the reliability needed to complete larger computations.
Our latest Helios results are proof points on the path to Apollo, our planned universal fault-tolerant quantum computer, expected by 2029. The goal is to translate these gains into systems that can solve industrially relevant problems faster or at lower cost than the best classical approach.
Industrial partnerships help connect that progress to problems that matter, from understanding high-temperature superconductivity to how molecules interact to accelerate drug discovery. They bring practical research questions into the development process and help identify where improving quantum capabilities could deliver useful results beyond the reach of classical computing alone.
Our motto is simple: fidelity first, with speed built on that foundation.
References & For Further Reading
[1] A. Lavasani et al., "Quantum error correction well below the color code threshold," arXiv:2610.24077 [quant-ph] (2026). doi:10.48550/arXiv.2610.24077.
[2] T. Proctor et al., "Benchmarking the computational power of quantum computers," arXiv:2609.12146 [quant-ph] (2026). doi:10.48550/arXiv.2609.12146.
[3] A. Ransford et al., "A 98-qubit trapped-ion quantum computer with all-to-all connectivity," Nature 655, 81-86 (2026). doi:10.1038/s41586-026-10676-4.
[4] M. Liu, R. Shaydulin, P. Niroula et al., "Certified randomness using a trapped-ion quantum processor," Nature 640, 343-348 (2025). doi:10.1038/s41586-025-08737-1.
S. Dasu et al., "Computing with many encoded logical qubits beyond break-even," arXiv:2602.22211 [quant-ph] (2026). doi:10.48550/arXiv.2602.22211.
E. Granet et al., "Superconducting pairing correlations on a trapped-ion quantum computer," arXiv:2511.02125 [quant-ph] (2025; revised 2026). doi:10.48550/arXiv.2511.02125.
Quantinuum and GE Vernova’s Advanced Research Center are launching a collaboration to apply quantum computing to one of the research community’s most consequential challenges: understanding the behavior behind high-temperature superconductivity. Advances in this field could, over the long term, transform the energy sector by enabling lighter generators, more compact and powerful motors, and electricity infrastructure that carries more power and better withstands faults.
The research will focus on Fermi–Hubbard modeling, a framework for studying how interacting electrons give rise to complex material properties. By combining Quantinuum’s full-stack quantum computing capabilities—including access to the company’s Helios computer—with GE Vernova’s expertise in material science and engineering simulation applied to industrial applications, the collaboration will bring an industry perspective to a promising area of quantum research.
Why superconductors matter for energy
As energy systems grow, the size, weight, and performance of electrical equipment become increasingly important constraints. High-temperature superconductors offer potential ways to address those limits through their ability to carry large electrical currents without resistance under suitable operating conditions.
Potential applications span power generation, electricity grids, and industrial electrification. Superconducting generators could reduce the weight and footprint of industrial equipment. Superconducting windings could also help make utility generators and industrial or marine propulsion motors more compact and efficient. In electricity networks, superconducting cables could carry more power through constrained spaces, while fault current limiters could help protect equipment during short circuits.
Realizing those benefits more widely depends on overcoming challenges in cooling, material performance, manufacturing, and cost. Better understanding of the physics behind high-temperature superconductivity could help inform the search for materials with more practical operating characteristics.
Why quantum computing may offer new tools for understanding high-temperature superconductivity
High-temperature superconductivity involves the collective behavior of strongly interacting electrons. Accurately modeling these systems is exceptionally difficult: the interactions that make them scientifically interesting also make important aspects of their behavior computationally challenging.
The Fermi–Hubbard model captures essential features of those interactions in a simplified mathematical framework. Although it is not a complete description of a material used in industrial applications, it provides a foundation for investigating mechanisms associated with high-temperature superconductivity.
Quantum computing offers a promising way to explore the physics. Quantinuum researchers have already measured superconducting pairing correlations—including s-wave and d-wave pairing—in Fermi–Hubbard models simulated on the Helios quantum computer. These results demonstrate the ability to prepare and probe quantum states relevant to superconductivity research, establishing a foundation for further investigation.
The collaboration with GE Vernova will build on that foundation, bringing industrial expertise to the selection and interpretation of research questions.
Connecting quantum capabilities with industrial expertise
The research will be enabled through access to Quantinuum’s full-stack capabilities, including cloud-based access to Helios, the world’s most accurate quantum computer1, and Nexus, Quantinuum’s developer platform. Nexus connects quantum hardware with the software tools researchers need to develop and run applications in a unified environment.
GE Vernova’s Advanced Research Center brings the expertise in material science, engineering, and industrial applications to the research and development activity.
“High-temperature superconductors could help us overcome important limits on the size, weight, and efficiency of electrical equipment, but understanding and improving these materials remains a significant scientific challenge,” said Jonathan Owens, PhD, Senior Scientist, Computational Materials Physics at GE Vernova. “By combining our materials simulation and industrial expertise with Quantinuum’s quantum computing capabilities, we can explore new approaches to these difficult problems while building the expertise to assess where quantum computing can make a meaningful contribution.”
The collaboration also extends GE Vernova’s exploration of quantum computing into a new area of materials research while supporting the development of its internal quantum talent. Its previous published work includes investigations of quantum algorithms for carbon-capture materials using simulated quantum processors.
Building toward industrial value
Translating insights from simplified models into practical materials requires sustained scientific and engineering work. Industrial expertise helps connect that effort to the properties, operating conditions, and manufacturing considerations that ultimately determine a material’s usefulness.
For Quantinuum, this collaboration is an opportunity to advance quantum simulation with an industrial collaborator that understands both the potential applications and the barriers to adoption. It brings together demonstrated computing capabilities, a challenging materials problem, and the expertise needed to connect scientific progress with industrial requirements.
The research collaboration aims to deepen understanding of this field and explore how quantum computing may contribute to future energy technologies.
1 Based on two-qubit gate fidelity as of December 31, 2025.
From Oracle's Quantum AI Compute beta program to upcoming Helios installation milestones and Oracle AI World, our partnership continues to gain momentum.
When Quantinuum and Oracle announced a strategic partnership earlier this year, the goal was not simply to deploy a quantum computer in the cloud. It was to create a practical path for bringing quantum computing into the enterprise environments where AI, data, and high-performance computing (HPC) already come together.
By combining Oracle Cloud Infrastructure (OCI)'s AI, data, and cloud capabilities with Helios, Quantinuum's most advanced quantum computer, we're helping lay the foundation for hybrid quantum AI computing at enterprise scale. The partnership reflects our belief that some of the most valuable future applications will emerge when quantum computing, AI and classical HPC work together to tackle problems that remain difficult to solve today.
Oracle Opens Early Access for Quantum AI Compute
That vision is now being put into practice. This month, Oracle launched the OCI Quantum AI Compute Beta Program, giving select organizations an opportunity to begin evaluating how quantum computing fits into existing workflows and computational challenges.
Through the program, approved participants will gain cloud-based access to Helios, the world's most accurate commercial quantum computer, alongside OCI's GPU and HPC infrastructure. For organizations exploring quantum computing, this creates a practical starting point: access to industry-leading hardware within an enterprise cloud environment, without the need to build specialized infrastructure of their own.
The goal is to help organizations understand where hybrid quantum AI workflows may create value across areas such as drug discovery, materials science, energy, financial modeling, and optimization.
For many organizations, the starting point is not quantum technology itself. It's a business or research problem. Where are today's approaches reaching meaningful limits? Which workloads consume disproportionate resources? And where could a new computational capability create an advantage?
Organizations interested in participating can apply through Oracle's OCI Preview Programs portal. Oracle will review applications and select participants based on eligibility, capacity and program requirements.
Quantinuum and Oracle Leadership Takes the Stage at Oracle AI World
The opportunity for hybrid quantum-AI computing will be a major topic at Oracle AI World 2026.
In a main stage session, "Powering the Next Era of Enterprise AI," Larry Stack, Chief Commercial Officer at Quantinuum, will join Mahesh Thiagarajan, Executive Vice President and Head of Oracle Cloud Infrastructure, to discuss how quantum computing, AI and classical HPC can work together to address some of the world's most computationally demanding challenges.
The discussion will focus on a core question many organizations are asking: where should they start? Rather than leading with technology, the conversation will explore how organizations can identify high-value problems, establish today's performance baseline, and evaluate where quantum computing ultimately provides an advantage.
Later in the day, Quantinuum and Oracle experts will take a deeper look at how bringing Helios into OCI provides managed access to quantum computing natively within an enterprise cloud environment to support hybrid quantum-AI workflows.
Building Momentum Toward Hybrid Quantum-AI Computing
The collaboration between Quantinuum and Oracle continues to progress from vision to execution.
With Helios advancing toward installation, Oracle's Quantum AI Compute program now open for early access, and enterprise interest growing around hybrid computing, the pieces are coming together. Organizations now have a practical way to begin exploring quantum computing through cloud-based access to Helios alongside AI, HPC, and existing enterprise workflows.
We look forward to continuing the conversation at Oracle AI World 2026 and working with customers who want to better understand where hybrid quantum-AI computing can create real-world value.
We're excited to continue that conversation at Oracle AI World 2026 and to help customers begin exploring what's possible through the OCI Quantum AI Compute Beta Program.