

Quantinuum announces a world record in fidelity for quantum computing qubits
99.9904% SPAM Fidelity with barium-137 sets the standard and creates a further step towards solving some of the world’s most intractable problems
Quantinuum researchers have set a record for the number of times they were able to place qubits into a quantum state and then measure the results, beating the previously stated best in class many times over.
The team led by Alex An, Tony Ransford, Andrew Schaffer, Lucas Sletten, John Gaebler, James Hostetter, and Grahame Vittorini achieved a state preparation and measurement, or SPAM, fidelity of 99.9904 percent — the highest of any quantum technology to date — using qubits formed from non-radioactive barium-137. The results, which are detailed here, have been submitted to arXiv.

This work has major implications for the quantum industry and trapped-ion technologies.
Improving SPAM fidelity helps reduce errors that accumulate in today’s “noisy” quantum machines, which is critical for moving to “fault-tolerant” systems that prevent errors from cascading through a system and corrupting circuits.
In addition, being able to form qubits from barium-137 and place them into a quantum state with high fidelity is advantageous for scaling trapped-ion hardware systems. Researchers can use lasers in the visible spectrum, a more mature and readily available technology, to initialize and manipulate qubits.
“This is a major step forward for the Quantinuum team and our high-performing trapped-ion quantum hardware,” said Tony Uttley, Quantinuum president and chief operating officer. “The advancement of the quantum computing industry as a whole is going to come from lots of individual technological achievements like this one, paving the way for future fault-tolerant systems.”
What is SPAM?
For most people, the word “spam” conjures images of unwanted emails flooding an inbox or of chopped pork in a can.
In quantum computing, SPAM stands for state preparation and measurement - two of the five conditions identified by theoretical physicist David DiVincenzo as necessary for the operation of quantum computer. It refers to initializing qubits (placing them in a quantum state) and then measuring the output. SPAM is measured in terms of fidelity, or the ability to complete these tasks at a high rate of success. The higher the fidelity the better because it means a quantum computer is performing these critical tasks with fewer errors.
Researchers at Quantinuum believe SPAM fidelity will need to hit 99.97 to 99.99 percent to reach the point at which the logical error rate beats the leading order physical error rate.
Why barium?
Neutral ytterbium atoms have long been a source of ions in trapped-ion quantum computers. Charged by lasers, ytterbium ions are transformed into qubits. But using ytterbium presents challenges. Expensive ultraviolet lasers are needed to manipulate ytterbium ions and the results can be difficult to measure.
Barium ions, however, are easier to measure and can be manipulated with less expensive and more stable lasers in the green range. But until this work with non-radioactive barium-137, researchers have only been able to achieve low SPAM errors with barium-133 atoms, which are radioactive and require special handling.
“Nobody thought you could do quick, robust SPAM with non-radioactive barium-137,” said Dr. Anthony Ransford, a Quantinuum physicist and technical lead. “We were able to devise a scheme that enabled us to initialize the qubits and measure them better than any other qubits. We are the first to do it.”
What’s next
Being able to initialize non-radioactive barium-137 ions is just the first step. The goal is to incorporate these ions into future Quantinuum hardware technologies.
“We believe using non-radioactive barium-137 ions as qubits is an attractive path to increasingly robust, scalable, quantum hardware,” Uttley said.
About Quantinuum
Quantinuum, the world’s largest integrated quantum company, pioneers powerful quantum computers and advanced software solutions. Quantinuum’s technology drives breakthroughs in materials discovery, cybersecurity, and next-gen quantum AI. With over 500 employees, including 370+ scientists and engineers, Quantinuum leads the quantum computing revolution across continents.
Fault-tolerant quantum computing is entering a new phase. At Quantinuum, we have demonstrated almost every piece needed for large-scale fault tolerant hardware, from a universal fault tolerant gate set, to a proven fault tolerant architecture, to large-scale materials simulations with encoded qubits, at world-leading fidelity.
However, that’s only half the battle. Developers need practical tools that make this technology accessible without needing to become experts in quantum error correction.
A good quantum computing software stack should capture and reuse QEC1 expertise, turning the complexity of fault tolerance into capabilities that developers can build with.
"Our ambition is for Nexus to be the platform developers turn to for the fault-tolerant era." - Dr. Rajeeb Hazra, President & CEO, Quantinuum
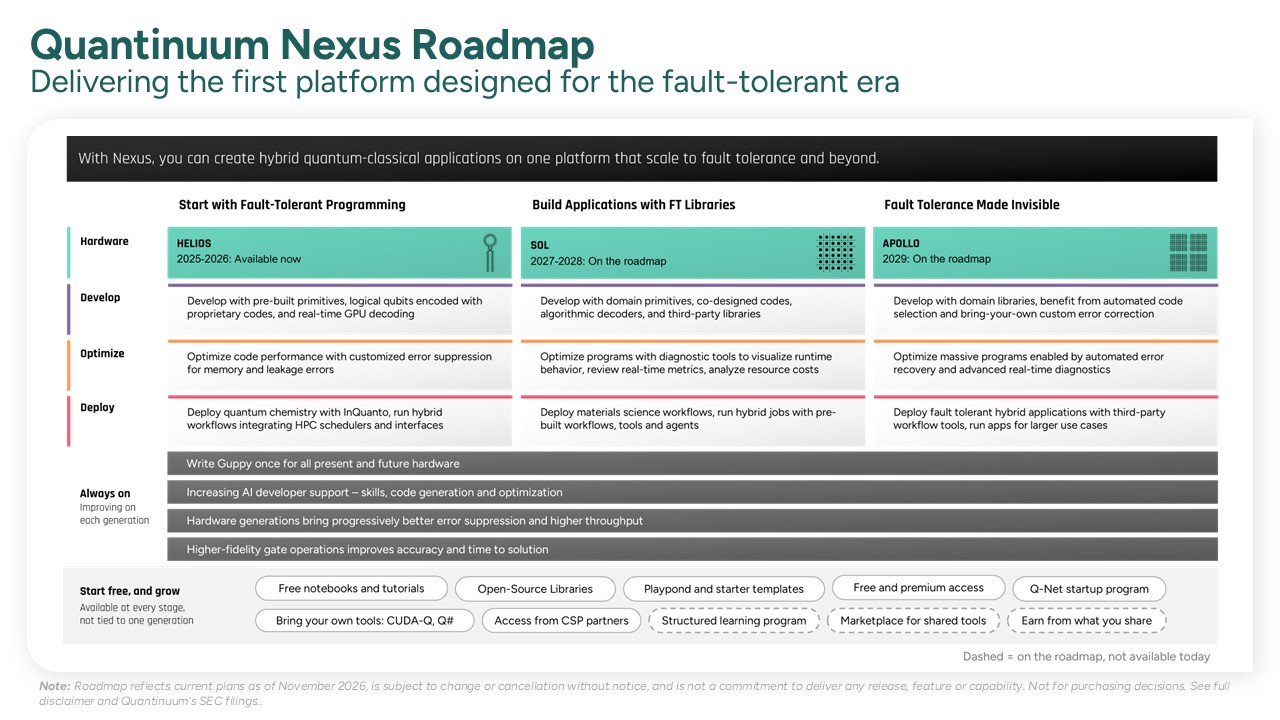
Here at Quantinuum, we are working hard to make that a reality. Since its launch in 2024, Nexus has grown from managing cloud-based quantum workflows into an environment for end-to-end application development and deployment. Our new multi-year roadmap builds on that foundation, connecting software capabilities with each generation of Quantinuum hardware through Apollo, our universal, fault-tolerant quantum computer planned for 2029. Nexus will progressively handle more of the complexity of fault-tolerant development, helping developers build applications that grow in capability as the hardware advances.
With Nexus, you can explore quantum chemistry and materials using InQuanto, and you can make it fault tolerant using our pre-built fault tolerant primitives. You can use GPUs to decode errors in real time, while benefitting from hardware enabled error suppression like Leakage Repump or Dynamical Decoupling. You can also connect your HPC to our QPUs and use Nexus’ Hybrid workflow management system to enjoy the best of both worlds seamlessly.
Of course, all of the above needs a language framework that is fault tolerant in the first place. That’s why we are thrilled to introduce Guppy FT – Nexus’ fault tolerant quantum programming framework, and Guppy Algorithms, Nexus’ library of reusable algorithmic primitives.
Developing for the fault tolerant era: Guppy FT
“The field of QEC is quite abstract, and it is hard for non-experts to gauge what is feasible on current devices. Guppy FT promotes a game-changing paradigm: QEC is no longer just theory, it is also engineering, it is something you can use.” - the Guppy FT team
As we have been saying, the NISQ2 era is coming to an end. The next challenge is to turn fault tolerance from a hardware milestone into a capability developers can use.
We have built the physical QEC architecture: high-fidelity physical qubits, distance scaling and low logical error rates, all-to-all connectivity and reconfigurable qubits, all the primitives working harmoniously, real-time decoding, circuit optimization, and so on. The next step is ensuring our users can easily enjoy the above: with a fault tolerant programming language framework (Guppy FT) inside a fault tolerant user platform (Nexus).
Guppy FT brings three complementary capabilities together:
- A framework for QEC experts to define fault-tolerant architectures.
- Automatic compilation that takes programs written in standard Guppy and turns them into programs running on fault-tolerant architectures.
- Proprietary codes from our own QEC experts that get you the best performance out of our world-leading hardware.
The result is a programming experience in which developers can write quantum algorithms without having to understand the details of the underlying error-correction architecture, while QEC experts retain the ability to define and optimize the architectures that power those programs.
This separation between what the program does and how it is made fault tolerant is central to the approach.
With Guppy FT, QEC experts define the fault-tolerant architecture once, and application developers can program on it without needing to become QEC experts themselves. Developers can continue to write programs in standard, QEC-agnostic Guppy. The Guppy FT framework then automatically lowers those programs into an encoded, fault-tolerant form suitable for execution.
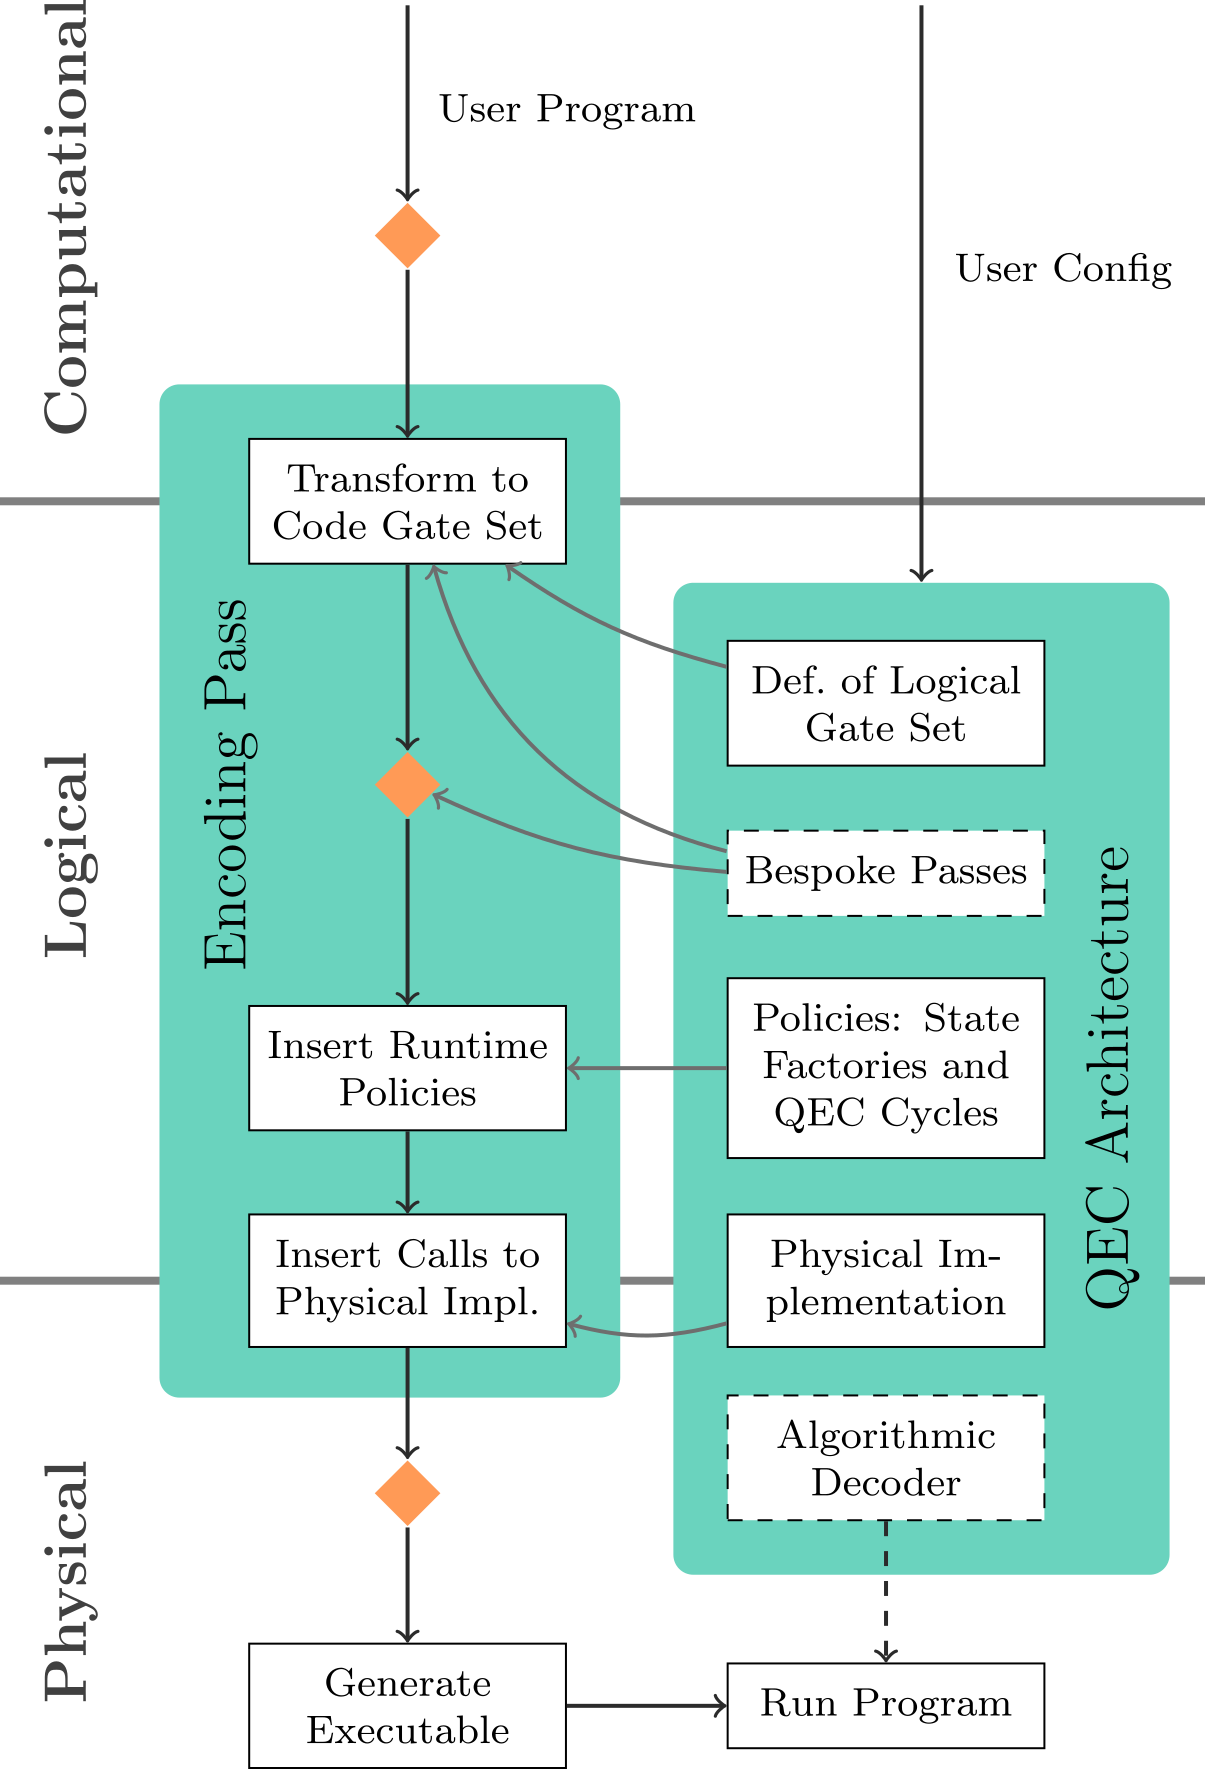
As fault-tolerant techniques improve, the same high-level programming model can therefore serve as a stable interface between applications and increasingly sophisticated QEC implementations. This approach also makes it possible to evolve the underlying architecture without requiring every application developer to rewrite their programs around its implementation details – a crucial benefit as we stay at the forefront of a quickly evolving field.
Available to users today, Guppy FT is an important step toward software designed for the fault-tolerant era. You can use already-perfected codes, like our high-rate quantum error detection code, through Nexus, with more codes coming online as they are developed.
Optimize your work with Guppy Algorithms & Realtime Analytics
We want you doing more than just writing fault tolerant programs – we want to help you write quickly and optimally.
With Guppy Algorithms, you can save needless repetition of work by constructing complex application-level software workflows in an application-agnostic way. Built on Guppy, Guppy Algorithms combines type-safe Guppy primitives with Python builders to help developers construct quantum algorithms out of already optimized building blocks. Guppy Algorithms is also QEC agnostic, enabling users to evolve their fault tolerance approach as the platform grows, without needing to re-write finished programs.
Current highlights include primitives that help you with:
- Trotterisation for Hamiltonian Simulation
- Quantum linear algebra
- Quantum arithmetic
Using Guppy Algorithms is simple. First, you build your abstract (application-specific) algorithm. Then, you simply compose it with Guppy Algorithms: import your desired implementations of circuit sub-components and bring your workflow to life.
"Guppy FT and Guppy Algorithms add a necessary abstraction on top of Guppy’s flexible programming model, so that application development and QEC research can advance in lockstep without either having to bake in assumptions about the other.” - Seyon Sivarajah, Chief Architect of Developer Tools
Soon, we plan to expand Guppy Algorithms to include end-to-end workflows of reusable components.
Of course, a set of optimized building blocks isn’t enough to ensure every program you write is optimal for execution. To that end, Nexus is introducing two tools to help users understand and optimize hardware execution:
- Real-time metrics that provide execution statistics, including gate counts and shot duration.
- ShotPlot, our tool for visualizing gate scheduling, helping users identify idle periods and improve circuit layout.
With these functionalities, you can try new approaches to minimizing gate counts or runtime with real-time feedback that helps you further optimize your result. Taken together, these new tools ensure that Nexus provides an optimal programming experience, from the circuit level to the user experience.
Using Guppy FT to reduce errors on quantum hardware: an end-to-end demonstration on Helios
To demonstrate Guppy FT, the team ran a Steane-encoded quantum algorithm, HHL, on Quantinuum’s Helios quantum computer.
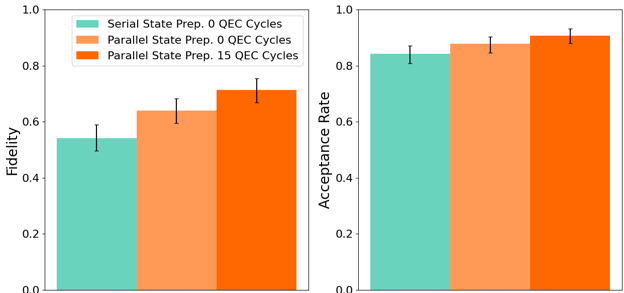
The team compared three versions of the HHL program, with different settings for Guppy FT’s Steane code ([[7, 1, 3]]) encoding, each with 500 shots. The first used no explicit QEC cycles and performed on-demand, sequential state preparation. The second used Guppy FT’s state factories to parallelize state preparation, and the third also applied three QEC cycles to each of the five qubits.
Each shot is comprised of three stages: the HHL program, mid-circuit error detection, and the inverse of the HHL program. Mid-circuit error detection measures the ancilla qubits used by the HHL program, which it ought to disentangle from the data qubits. If an error is detected, the shot is discarded; otherwise, it moves on to the final stage and is marked as accepted. Fidelity is computed as the proportion of accepted shots that the inverse HHL program successfully returns to the initial state.
The results show that both QEC cycles and parallelized state preparation improve performance. QEC cycles actively correct errors while parallelization shortens execution time, reducing the chance of errors. Together, these results demonstrate how Guppy FT can implement fault-tolerant architectures for practical, end-to-end programs running on real quantum hardware.
Deploy Your Hybrid Quantum-Classical Application
The future of quantum computing is more than fault tolerant: it’s hybrid. Close co-ordination between classical and quantum computing resources will be essential for most killer use-cases, with a combination of AI, HPC, and QPU each working on the sub-components they are best suited for.
We’ve been perfecting hybridization for years now, including hybridizing our QPUs with the Fugaku supercomputer at RIKEN. Along the way, we have developed a robust event-based hybrid compute runtime, now available through Nexus. Our updated hybrid compute framework features:
- Multiple storage implementations
- Workflow attempts and restart improvements
- Runtime configuration files
- OTEL tracing and observability
- Workflow cancellation
- SQLite based state management
Quantinuum Nexus: A foundation for what comes next
Nexus brings together the capabilities and infrastructure needed to develop, analyze, run, and manage hybrid quantum-classical programs across the stack. By unifying quantum programming, validation, fault tolerance, compilation, and execution in one place, with interoperability across third-party environments, Nexus is making fault tolerance a practical reality.
Nexus users are already using our quantum processors to explore applications in finance, nuclear physics, particle physics, benchmarking, computational chemistry, and more. As our Nexus roadmap evolves, we plan on deploying ecosystem tools and libraries, as well as an applications marketplace where developers can monetize their work.
“Quantum computers are on the brink of achieving fault tolerance at scale. It's exciting: we are entering terra incognita for what we can compute. The new challenge is putting our high-level quantum algorithms into the right form to successfully run on error-corrected hardware. Developer platforms like Nexus help us bridge that gap between quantum algorithm design and deployment
-José Ignacio Latorre, Director, Centre for Quantum Technologies at the National University of Singapore at the National University of Singapore
By bringing everything together, Nexus is becoming a robust platform in which fault tolerance is a feature, rather than a barrier to entry.
Get ready for the fault tolerant future.
1 Quantum Error Correction
2 Noisy Intermediate Scale Quantum
By Chris Langer
Trustworthy answers are a prerequisite for useful quantum computing. First build machines that deliver answers reliably. Then focus on delivering them quickly.
A trustworthy answer also needs to arrive soon enough to be useful. But understanding how long that takes requires looking beyond the speed of any single operation.
Think about your commute: a car’s 0–60 time doesn’t tell you when you’ll arrive. Traffic, detours, and bottlenecks all affect the journey. Quantum computing works much the same way. No isolated metric, including gate speed, indicates how quickly the entire system can get the job done.
The goal of quantum computing is to solve valuable problems reliably and soon enough to matter.
At Quantinuum, we are pursuing that goal by scaling our systems and removing bottlenecks. Speed depends on how much work is required to make a computation reliable and how much of that work can happen simultaneously. We are improving how we build and operate logical qubits—an essential mechanism for complex computations—through more efficient error correction, faster qubit movement, and more parallel operations.
Understanding how these advances translate into faster answers starts with looking beyond the speed of a single gate.
The Gap Between Fast Gates and Useful Answers
Gate speed reveals how quickly a single step happens in a quantum calculation. It does not tell us how many steps are needed, how many can happen together, or how often a computation must be repeated.
An example illustrates the distinction.
Researchers from the University of Tokyo ran a small, three-qubit circuit on superconducting and trapped-ion systems.1 Armed with faster gates, the superconducting machine executed the circuit roughly 200 times faster. But it needed about 50 times more repetitions to reach comparable accuracy, reducing its practical speed advantage to approximately four times.
Faster gates led to faster answers in this example, but the headline execution speed overstated the advantage dramatically.
Even on a modestly larger circuit, the fourfold advantage could disappear entirely. A more complicated circuit means more room for errors and significantly more repetitions to overcome them. Now consider what is required of the systems, larger still, to solve real-world challenges. This calls for a move to logical qubits, which spread information across multiple physical qubits so that errors can be detected and corrected without loss.
At that scale, the question becomes how quickly the system can do useful work while keeping errors under control. The metric that tracks the rate of useful work is logical throughput, the amount of useful work a system completes per second.
What Drives Logical Throughput and Faster Answers
Logical throughput depends on logical clock rate (how quickly logical operations happen) and parallelism (how many can happen at once).
Consider two hypothetical machines: the first completes one logical operation at a time, each taking a microsecond. The second performs 1,000 independent logical operations simultaneously, each taking a millisecond. In one millisecond, each machine completes 1,000 operations. The second machine’s operations take 1,000 times longer, but parallelism offsets the difference.
Error correction takes time and physical qubits. Using both more efficiently can speed up logical operations and enable more work in parallel.
Three levers help improve that throughput:
Connectivity. Better connectivity enables error correction that is more efficient in time and space. Faster correction improves logical clock rate; fewer physical qubits per logical qubit leave room for more logical qubits. Connectivity also enables logical operations to work in parallel.
Fidelity. More reliable physical operations reduce the resources needed for error correction. This improves efficiency in space: fewer physical qubits can deliver the required logical reliability, leaving capacity for more logical qubits.
Scale. More physical qubits create room for more logical qubits. Efficient error correction, strong connectivity, and enough places to perform operations help turn that added capacity into more work happening at once. As systems scale to 1,000 logical qubits and beyond, putting more qubits to work simultaneously can help offset slower individual operations.
How Quantinuum Is Turning Scale into Speed
Faster gates, better connectivity, efficient error correction, and greater parallelism must work together. That is the thinking behind Quantinuum’s approach to scaling.
We are working to accelerate gate execution, qubit movement, and other factors while reducing unnecessary operations and improving error-correction efficiency. More efficient error correction lets us reach the required reliability with fewer resources. That means we can exploit parallelism and spend more of our extra qubits on speed.
Superconducting systems, by contrast, boast faster clock speeds, but limited connectivity forces more operations to run in sequence. That constrains the parallel capabilities of these systems, the other side of the throughput equation. Put simply, completing each step faster does not guarantee finishing the job sooner if more steps must wait their turn. Greater error-correction overhead also leaves fewer logical qubits available for computation from a given number of physical qubits. Even with more logical qubits, connectivity remains a separate constraint on how many operations can run in parallel. Together, these factors limit how effectively faster physical gates translate into faster computation.
Quantinuum’s architecture allows us to scale logical qubits and facilitate greater throughput. Maximizing the value of qubits remains an engineering challenge, which our roadmap to larger, faster machines addresses in three steps:
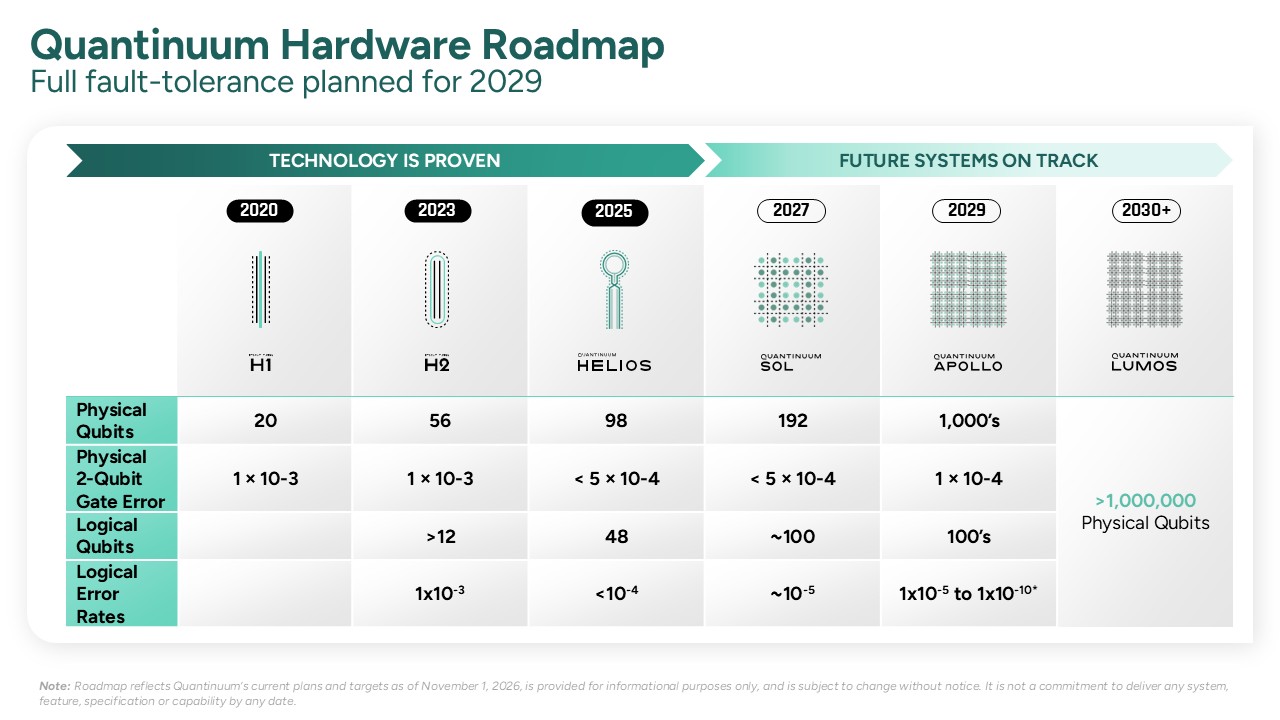
First, improve how qubits move. Sol, planned to launch in 2027, is our expected proving ground for a two-dimensional architecture that allows more efficient, parallel rearrangement of qubits as the system grows. Our prototypes have already demonstrated our two-dimensional geometry, operating concepts, and scalable controls work.2 We continue to improve the speed of qubit movement.
Second, create more places to work simultaneously. Adding operating zones enables more operations to run at once, increasing throughput by leveraging space.
Third, increase scale. Our planned progression from Sol to Apollo (targeted to launch in 2029) and then Lumos in the decade ahead is intended to increase physical qubit counts from approximately 200 to thousands and eventually millions.
On these larger systems, efficient error correction and connectivity-enabled parallelism will allow us to turn more qubits into dramatically higher computational throughput.
Measure the Time to a Useful Answer
As quantum computers grow, they must solve larger problems in a useful amount of time. Fast gates can’t guarantee that. Any speed advantage on a small, uncorrected circuit could vanish at the logical level. For superconducting systems, scaling this small-scale edge would mean overcoming architectural limits on connectivity and efficient error correction, which is no small feat.
For users and investors, the speed equation includes how much work the system requires, how efficiently it corrects errors, and how much computation it can perform at once. Additional qubits deliver their full value when these capabilities translate scale into increased logical throughput.
It doesn’t matter how fast you get to the wrong answer. What matters is getting the right answers efficiently. Returning to the commute analogy, we’re adding horsepower to our car and identifying the traffic detours on the road. The measure of progress will be how quickly we arrive at the destination.
References:
[1] E. Lötstedt and K. Yamanouchi, “Comparison of current quantum devices for quantum computing of Heisenberg spin chain dynamics,” Chemical Physics Letters, vol. 856, Art. no. 141817, Feb. 2024, doi: 10.1016/j.cplett.2023.141817.
[2] R. D. Delaney et al., “Scalable Multispecies Ion Transport in a Grid-Based Surface-Electrode Trap,” Physical Review X, vol. 14, no. 4, p. 041028, 2024, doi: 10.1103/PhysRevX.14.041028.
Forward-Looking Statements
This post contains forward-looking statements within the meaning of the Private Securities Litigation Reform Act of 1995. These include statements about Quantinuum's technology and product roadmap; the expected timing, capabilities, and performance of future systems, including Sol, Apollo, and Lumos; anticipated improvements in error correction, qubit transport, parallelism, and logical throughput; and the potential applications of quantum computing. Words such as "will," "intend," "plan," "expect," "target," "designed to," "may," "can," "could," and similar expressions identify forward-looking statements.
These statements are based on current expectations and assumptions and are subject to risks and uncertainties that could cause actual results to differ materially. These risks include technical challenges in scaling quantum hardware and error correction; delays in development, manufacturing, or supply of components; the pace of customer adoption; competition and advances in alternative technologies; our ability to fund research and development; and the other risks described under "Risk Factors" in the prospectus for our initial public offering and in our most recent Quarterly Report on Form 10-Q, each filed with the Securities and Exchange Commission. Forward-looking statements speak only as of the date of this post, and we undertake no obligation to update them, except as required by law.
By: Harry Buhrman, Chief Scientist
Quantum computing is often framed as a race to the most qubits, the fastest gates, and the biggest benchmarks.
But a race needs a destination. In the fault-tolerant era, that means solving a valuable problem faster or at a lower cost than the best classical approach—and the time to solution is ultimately what matters most.
In this context, gate speed metrics have received a lot of attention. While gate speed is a meaningful component of the overall quality of a quantum computer, what actually matters most is fidelity. As we all know, speed on its own matters little if we don’t arrive at the correct destination.
Fidelity has emerged as the most important foundation for success in quantum computing. Higher fidelity means fewer errors in the underlying physical operations. Combined with quantum error correction, higher fidelity can reduce the number of additional qubits and operations needed to make computations reliable. This reduction in overhead can lower costs and shorten the time to deliver a useful answer—even compared with systems that have faster gates but lower fidelity.
Fast Gates Do Not Guarantee Fast Answers
Consider a simple example. In an independent-error model, a computation with 10,000 operations, each with an error rate of 10⁻³, or 99.9% fidelity, will experience about ten faults on average that can render the computation useless.
Now make every gate ten times faster without changing its error rate. You still get ten faults. You just get them ten times sooner.
Speed matters, but the relevant measure is the total time required to obtain a trustworthy and useful result. Getting to that point requires performance in many different and connected areas such as state preparation, measurement, error correction, repeated runs, and other work needed to complete the computation.
Gate speed alone cannot establish which system performs best. A fast machine that cannot reliably finish a sufficiently large computation cannot deliver commercial value.
Why Fidelity Changes the Resource Equation
Quantum error correction protects information by encoding it across multiple physical qubits. That protection requires resources: additional qubits, measurements, operations, and classical processing. These techniques work better when the underlying physical operations are reliable enough that increasing error protection reduces the logical error rate.
This requirement is known as the fault-tolerance threshold, the point below which physical error rates are low enough that adding protection reduces logical errors. Faster gates can shorten the computation, but they cannot replace the physical fidelity needed to cross that threshold.
At Quantinuum, our latest error-correction results on Helios demonstrate this principle. Using our error-correction architecture, logical memory errors fell exponentially as we increased protection. Across the tested code sizes, the fitted error reduction was about twelvefold for each increase of two in code distance. In the largest quantum-memory experiment, the estimated failure rate was about five in a million per error-correction cycle.1 This demonstrates how high-fidelity physical operations and effective error correction work together to make quantum information more reliable as protection grows.
The next question is what that reliability enables. How large a computation can a system complete, and how quickly can it deliver the result?
A New Performance Benchmark
The Quantum Universal Operations Performance System, or QUOPS, provides a standardized way to assess both. This architecture-neutral benchmark gauges performance by measuring computational “reach” and speed.2
“Reach” measures how large a benchmark circuit a system can execute successfully. Speed measures how quickly it executes that circuit, in effective quantum operations per second. QUOPS uses wall-clock time and accounts for extra samples and discarded runs caused by noise.
Together, these measures provide a common basis for comparing what different quantum systems deliver and tracking progress toward better time to solution.
Quantinuum’s H2 and Helios systems executed substantially larger benchmark circuits than Google’s Willow and IBM’s Boston. These superconducting systems sometimes achieved higher effective operation rates, but on smaller circuits, which means that they are not computationally comparable.
Superconducting systems can use error mitigation to tackle larger computations, but at a steep cost in speed. The QUOPS study estimates that the additional repetitions can make effective processing thousands of times slower. Some computations remain beyond the system’s reliable reach, even with mitigation. In those cases, faster gates may deliver no useful answer at all within practical limits on time and cost.
Useful applications require speed on much larger circuits. For example, the study estimates that factoring RSA-2048 or calculating FeMoco’s ground-state energy within five days would require roughly 100,000 times the computational reach demonstrated by today’s physical-qubit processors. Some machines approach the estimated speed requirement, but only on small circuits. The challenge is to sustain that speed at the required scale, including the additional work needed for error correction.
Larger uncorrected circuits accumulate more errors. Protecting them requires extra qubits and time. Reliability and speed must therefore scale together, and QUOPS offers a way to track both.
Higher Fidelity Makes Larger, Reliable Computations Possible
Improving fidelity can reduce the extra qubits and operations needed for error correction, lowering the time, cost, and resources required for useful computation. The benefit comes from reaching the required reliability with less protection, leaving more resources available for the computation itself.
Helios brings together the physical performance and error-correction capabilities needed to pursue those savings. In our paper published in Nature we showed that the system achieved an average single-qubit gate fidelity of 99.9975% and average two-qubit gate fidelity of 99.921% across its operational zones, while scaling the trapped-ion architecture to 98 fully connected physical qubits.3
The latest color-code experiments build on that physical performance. Alongside the logical memory results, protected two-qubit Clifford operations also became more reliable as protection increased. This connects improvements in the underlying hardware to improvements in logical computation.
A flexible error-correction architecture creates further opportunities to improve efficiency. Our recent Helix and color-code demonstrations used the same Helios hardware to explore different balances of accuracy and physical-qubit requirements. That flexibility allows us to evaluate which codes best suit different computational tasks as systems scale.
However, we continue to push ahead and accelerate the development of machines, such as Apollo, where quantum utility comes into play at scale. Decoding in the new color-code benchmarks was performed offline, and we are now turning our attention to integrating error correction, magic-state resources and real-time control into longer, reliable computations.
While that work continues, today’s systems can already contribute to scientific research. NISQ systems have advanced algorithms and hardware, enabled certified randomness, and supported studies of quantum magnetism and superconducting pairing correlations. These results leave room for useful applications before fault tolerance, even as error correction provides the scalable path to larger, reliable computations.4
The goal is to combine these capabilities so that larger computations can run reliably within practical limits on time and resources. Fidelity provides the foundation, and optimizing the full system turns that foundation into better time to solution.
Fidelity First. Then Optimize Time to Solution.
Scaling quantum computation requires continued progress in fidelity. As physical operations move further below threshold, increasing error protection can suppress logical errors more effectively, enabling longer, more demanding computations.
Speed must improve alongside that reliability. Advances in transport, cooling, measurement, compilation, and parallel execution can reduce the time and total cost of solving useful problems. These improvements become increasingly valuable as systems gain the reliability needed to complete larger computations.
Our latest Helios results are proof points on the path to Apollo, our planned universal fault-tolerant quantum computer, expected by 2029. The goal is to translate these gains into systems that can solve industrially relevant problems faster or at lower cost than the best classical approach.
Industrial partnerships help connect that progress to problems that matter, from understanding high-temperature superconductivity to how molecules interact to accelerate drug discovery. They bring practical research questions into the development process and help identify where improving quantum capabilities could deliver useful results beyond the reach of classical computing alone.
Our motto is simple: fidelity first, with speed built on that foundation.
References & For Further Reading
[1] A. Lavasani et al., "Quantum error correction well below the color code threshold," arXiv:2610.24077 [quant-ph] (2026). doi:10.48550/arXiv.2610.24077.
[2] T. Proctor et al., "Benchmarking the computational power of quantum computers," arXiv:2609.12146 [quant-ph] (2026). doi:10.48550/arXiv.2609.12146.
[3] A. Ransford et al., "A 98-qubit trapped-ion quantum computer with all-to-all connectivity," Nature 655, 81-86 (2026). doi:10.1038/s41586-026-10676-4.
[4] M. Liu, R. Shaydulin, P. Niroula et al., "Certified randomness using a trapped-ion quantum processor," Nature 640, 343-348 (2025). doi:10.1038/s41586-025-08737-1.
S. Dasu et al., "Computing with many encoded logical qubits beyond break-even," arXiv:2602.22211 [quant-ph] (2026). doi:10.48550/arXiv.2602.22211.
E. Granet et al., "Superconducting pairing correlations on a trapped-ion quantum computer," arXiv:2511.02125 [quant-ph] (2025; revised 2026). doi:10.48550/arXiv.2511.02125.